devsecops
DevSecOps foundations
Agile vs Waterfall
Waterfall was a paradigm in the past where devs would spend months trying to figure out the architecture of the app, then implement that architecture. After a year is over they deploy the production-ready app.
The main problem with Waterfall was that clients don't know what they want so the finished app would often end up being very bad.
Agile fixes this by making sure the product updates in 2-3 week sprints and accounting for client feedback, and multiple sprints make a release.
However, even with Agile, we are still missing essential components that DevOps fixes:
- waterfall: development, testing, and operations are all separate teams, so progress is slow and frustrating.
- agile: development and testing are intertwined, but operations are left out, so deployment is a headache.
- devops: brings development, testing, and operations to work together with ease, simplifying the development and deployment process
NOTE
DevOps is a culture shift that integrates Agile to make both development and release cycle very fast

Why devsecops
The old way of security testing was manual and took a long time

The DevSecOps approach aims to improve security testing speed via two approaches:
- increase speed by automation: include automation scripts that run code analysis checks
- enable developers to participate in security: developers should be responsible for the security of the code they write. Enable them with security tools for this purpose.
NOTE
DevSecOps is the merging of the security team into the DevOps process, to further the goal of giving dev teams more ownership over security by integrating automated security checks into every step of the process.
Here is how DevSecOps differs from traditional security:
- Traditional security is often slow and manual, with security teams running scans and reviewing code over weeks, which doesn't fit the fast pace of DevOps.
- Traditional application security is slow and manual, with security teams working separately from developers, causing delays and bottlenecks.
- DevSecOps integrates security directly into the development pipeline, automating tests and giving developers ownership of security tasks.
- DevSecOps integrates security directly into the development pipeline, embedding automated security checks early to provide real-time feedback to developers.
This means developers get real-time feedback within their workflow and can fix issues quickly, while security teams shift to an auditing role.
How DevSecOps helps developers
The focus is on empowering developers with tools and education to handle security themselves, making security a continuous, fast, and collaborative process.
We can help devs by integrating into their workflow and building automations they would actually use:
- security notifications: automate delivering important security notifications not in cloudwatch logs but in a Slack or Teams channel everyone uses.
- automate what matters: don't automate pushing a button. Automate painful workflows for devs and make those easy.
If you automate a mess, you get an automated mess.
So when you automate security, do it right. Make sure automation helps devs, not frustrates them.
Shift security to the left
DevSecOps is all about shifting security to the left, meaning having security checking earlier in the agile sprint pipeline.
 We accomplish this by moving automated security checks like SAST and DAST into the development lifecycle.
CI/CD in DevSecOps
Continuous integration
Continuous integration is when a bunch of devs commit to source control, and then a build server like TeamCity builds an artifact from source control, then runs tests and code quality checks on it before deploying it.
Here's the basic flow:
- Developers push their code to centralized source control
- Build server like TeamCity detects changes, builds an artifact, runs tests, and deploys to different environments
Continuous delivery
Software is built in short cycles via agile, and then continuously deployed sequentially to testing, preprod, and prod environments, where source code only passes from one stage to the nest if it passes all tests for that stage.
Continuous delivery ensures that only tested and approved software is delivered to users.
Continuous Improvement and feedback
DevOps is meant to be a continuous loop that builds upon feedback to improve.

- continuous feedback: each DevOps task should have a feedback loop that notifies developers as to what went wrong or right.
- continuous improvement: improving based on feedback
DevOps tools and methodologies
Use APIs
APIs are crucial in DevSecOps security automation because they allow security tools to be controlled remotely and integrated seamlessly into the development pipeline.
Instead of manual scans, APIs enable automated security testing to run frequently and efficiently without slowing down development.
- They also help connect security processes with systems like Jira for automatic updates, reducing manual work.
- This automation makes it easier for developers to incorporate security into their workflow, supporting faster and more continuous security checks aligned with DevSecOps principles.
Metrics
Metrics are used to help define the success of a program, and turn goals into measurable outcomes.
There are 3 types of metrics:
- operational metrics: metrics for the ops team, ensuring pipeline and infrastructure health
- MTTR (mean time to recover)
- MTTD (mean time to delivery)
- Deployment frequency
- flow time: detection to resolution
- vulnerabilities: number of critical vulnerabilities, and vulnerabilities by type.
- code metrics: focus on security and quality assurance of code.
- application coverage: measures test coverage percentage
- vulnerability remediation time: how quickly issues get fixed
NOTE
Track metrics that encourage good behaviors and practice, like limiting vulnerabilities.
Intro to security testing
There are two types of pipelines that a product goes through:
- build pipeline: packages certain source code for deployment
- release pipeline: pipeline that handles the process of releasing code to a target environment, prod, staging, or preprod.
NOTE
The main reason why you would want to separate these two pipelines is so you can run them a different number of times or where you only want to build once but then you want to release to multiple different environments from one single build.
Here are the two main types of testing:
- white-box testing: you have full knowledge of the codebase, so you test internal logic.

- black-box testing: the code is a black box to you - like testing an external API - so you test functional logic

You can further subdivide those blanket testing categories into two more categories of testing:
- static security testing: analyzes source code for security vulnerabilities.
- con: It is language specific and can lead to several false positives.
- pro: very quick
- dynamic security testing: tests an app while it is currently running to test application flow and discovers vulnerabilities by interacting with the website./
- pro: catches elusive bugs and vulnerabilities
- con: a black-box approach that takes a lot of time to complete
Here are the static security testing techniques:
- Software composition analysis (SCA): analyzes open source packages to see if they are vulnerability-free and up to date
- Static code analysis (SCA): analyzes IaC in an automated manner to check for known vulnerabilities when creating the infra by analyzing code patterns.
- Pro: quick, automated, no need for devs to know intimate security details.
- Con: not 100% effective, may lead to false positives or may not find everything.
- Static application security testing (SAST): a white-box testing method with normal application code testing via unit and integration tests
Here are the dynamic security testing techniques:
- Dynamic application security testing (DAST): black-box testing method that examines an application while it's running to find vulnerabilities, testing the app as it runs.
- runtime testing: testing suspicious API calls, networking, commands run on the server, audit trails.

Static testing
SAST
SAST is static application security testing, where it reviews the source code of software to identify potential vulnerabilities.
SAST scanners are tools that can help with the security analysis of static source code. When you use the SAST scanner, it's important to understand what cases SAST can help cover, as well as what areas may be best to supplement with other scanners or tools. Below are some strengths and considerations for the SAST scanner.
NOTE
SAST tools are great for finding well-defined security vulnerabilities, however more complex vulnerabilities often need a different approach. Logic based vulnerabilities such as access control issues are often best tested with other scanners such as DAST.
pros
- CI/CD friendly: runs very quickly and can catch many common vulnerabilities
- ease of scaling: One of the main strengths of SAST is the ability to scale it. If you have many projects or large code bases, you can use SAST to ensure a baseline security posture is met for all of your code.
- consistent security scanning: Additionally, you can schedule SAST scans to allow for consistent security scanning.
- identification of common vulnerabilities: SAST excels with detecting well-known vulnerabilities, such as buffer overflows and SQL injections. SAST scanners help ensure that these common and well-defined vulnerabilities do not make it into your production code.
cons
- many false positives: very simple and errs on the side of caution, so you may have many false positives.
- doesn't catch runtime errors: can't catch runtime security vulnerabilities like authorization misconfiguration. For this, use something like DAST.
- doesn't catch access control errors: logical vulnerabilities require more interactive security testing methods like DAST.
Static code analysis (SCA)
Static code analysis is a white-box testing procedure that works by first defining checks or policies based on what your organization wants and then, based on those policies, scanning for common security vulnerabilities, deployment best practices, and coding best practices.
Here is an example of using SNYK as an SCA tool:
docker run --rm -it --env SNYK_TOKEN -v $(pwd):/app snyk/snyk:node
Software Composition Analysis (SCA)
SCA analyzes the third-party package dependency tree for any vulnerabilities.

Continuous secret scanning
Secret scanning is a white-box testing approach that statically searches for exposed secrets in your codebase via Regex or Entropy-based searching (entropy-based is better).
Secret scanning is crucial to prevent accidental exposure of sensitive credentials like AWS keys, passwords, and API tokens, especially in infrastructure as code files.
Here are the best practices:
- add pre-commit hooks to block exposed secrets: implement pre-commit hooks that block commits if secrets are detected, ensuring secrets are caught early in the development process.
- use automated secret-scanning tools: Tools like Aikido and TruffleHog can automate secret scanning by integrating with code repositories and CI/CD pipelines, enabling continuous protection as part of your DevSecOps workflow.

Dependency scanning and ontinuous dependency scanning
dependency scanning is able to create SBOM reports, determine licenses of open-source libraries, and detect vulnerabilities in libraries.
Here is what dependency scanning allows you to do:
- detect licenses and vulnerabilities: As software continues to evolve, we have more reliance on open-source or third-party libraries. These libraries are useful, however they also increase the attack surface of our applications. Having dependency scanning in place lets us ensure that with the increased attack surface, we still have proper awareness of the vulnerabilities in these libraries.
- create SBOMs: SBOM reporting allows you to get a full picture of what open-source components exist in your projects. This is essential for situations where a critical issue occurs in a component. In these cases, the SBOM reports you generate can allow you to quickly validate if any of your projects are impacted by the issue.
TIP
you should combine dependency scanning with other tools such as SAST to get a full coverage of your application code.
Automated dependency scanning integrated into your CI/CD pipeline helps quickly identify vulnerable components by comparing dependencies against known vulnerability databases (CVEs).
Continuous dependency scanning uses an automated dependency scanner tool that scans your codebase's third party packages for vulnerabilities or outdated dependencies.

Continuous container scanning
Continuous container scanning scans these three main security focus areas for containerized applications:
- image vulnerabilities: Identifying known vulnerabilities in the container's base image and its installed libraries and dependencies.
- detection of licenses and vulnerabilities: Similarly to dependency scanning, container scanning can also report license and vulnerability details for components inside container images. This helps you ensure you maintain license compliance, while also being aware of vulnerabilities in your containers.
- SBOM reports: Container scanning will generate an SBOM report, allowing you to add container image components to a dependency scan SBOM report.
- Policy Enforcement: Ensuring containers are built and configured following security best practices, such as those outlined in CIS Benchmarks.
- Runtime Protection: Monitoring running containers for suspicious activity and preventing container breakouts.

Continuous IaC scanning
Infrastructure as code scanning is the process of statically analyzing infrastructure configuration files to detect misconfigurations, security vulnerabilities, and policy violations before they are deployed.
Continuous IaC scanning scans your IaC code with static analysis tools like Checkov that can be fit into CI/CD pipelines to catch misconfigurations with your infra design.

NOTE
A single misconfiguration in IaC can propagate across all deployments, so integrating security checks early in the development process is crucial to catch issues when they are cheapest to fix.
Security scanning tools like Akido Security and open-source Checkov can analyze IaC for vulnerabilities, providing instant feedback through IDE integration and bug tracking systems.
This is also combined with [[03-intro-devops#Policies as code]].
You have these tools for IaC scanning:

Dynamic testing
DAST
DAST stands for Dynamic Application Security Testing, it is a form of black-box testing, and it tests a running application via its UI or API for common vulnerabilities such as SQL injection and buffer overflows.
NOTE
DAST simulates how a real attacker interacts with apps, testing vulnerabilities with simulated SQL injections and XSS attacks.
DAST allows you to run tests against a running copy of your application. This can potentially find issues that were not present in your static source code, allowing you to have a more complete picture of the security posture of your application.
DAST scanners provide a variety of different configurations and modes you can use. The two main modes available are passive and active scans.
- passive scan: A passive scan checks for vulnerabilities in an application by crawling the application. Passive scans aim to interact with the application the same way a normal user would. This means that passive scans do not attempt to simulate adversarial behavior. A passive check is great for highlighting issues in HTTP messages, cookies, storage events, console events, and DOM.
- active scan: If you need a more intensive scan, you can opt for an active scan. Active scans will check for vulnerabilities by injecting attack payloads into HTTP requests. The goal of this is to simulate adversarial behavior, attempting to explicitly exploit the application. In order to use active mode, you need to add specific configurations to your application to prove you own the server being scanned. More details on this will be discussed later in the course.
An active DAST scan will determine if an exploit is successful through two methods: match responses and time responses:
- match responses: With this method, the scanner is checking to see if the result received matches the expected result of a successful exploit. For example, if the request was trying to access a password file, a response in the format of a password file is considered successful.
- timing response: Some requests will add sleeps to their payload to see if the application pauses for the specified amount of time. If pauses are seen as a response, it indicates a potentially successful exploit.
Here are the three core components DAST handles:
- Crawling and Spidering: The scanner navigates the live application to discover all entry points, URLs, forms, inputs, and API endpoints.
- Active Attack Simulation: It sends automated malicious inputs—such as SQL injections, Cross-Site Scripting (XSS) payloads, and path traversals—into those entry points.
- Response Analysis: The tool monitors the application’s responses, looking for error messages, unexpected behaviors, or exposed data that indicate a vulnerability.
NOTE
It can be run in CI/CD, but it's more accurate when using in manual testing.
This is an example of using OWASP ZAP DAST tool, which tests a URL for networking and OWASP vulnerabilities:
docker run -t owasp/zap2docker-stable zap-baseline.py -t http://10.0.2.15:3000
API security scanning
If you are writing a web application, it is likely that your application uses an API to retrieve data from your web server. API security scanners are designed to ensure that your API endpoints stay protected from common vulnerabilities such as unauthorized access and malicious inputs.
As a part of the API security scan configuration, you provide details about your API endpoints. There are four supported formats you can use to do this:
- OpenAPI spec
- GraphQL schema
- HTTP archive
- Postman collection
After you have specified the API format, the API scanner will use the configuration to send requests to your API. These requests are designed to attempt to trigger vulnerabilities in your API functionality.
- The goal of the scan is to simulate a real-world hacking attempt to see how your API reacts to these types of requests.
- The scans are language agnostic, as they only rely on the API request definitions to run.
Like DAST, API Security can also be configured in a passive or active mode.
- A passive scan will search for vulnerabilities by calling the API normally and reviewing the results.
- An active scan will search with specific vulnerabilities, such as SQL injection.
Dynamic code analysis
For DevSecOps, dynamic scans should run asynchronously in CI/CD pipelines to avoid blocking builds, and tools should be fast, accurate, support automation (API/CLI), and integrate with bug trackers
IAST
IAST stands for interactive app security testing, and is a combination of DAST with SAST, where it performs testing by integrating into the runtime.
Interactive Application Security Testing (IAST) works by instrumenting the application during runtime, allowing real-time monitoring of data flows and behavior to detect vulnerabilities accurately.
NOTE
IAST offers continuous security testing with fewer false positives compared to static or dynamic scanning, making it well-suited for integration into DevSecOps pipelines.
Continous application runtime monitoring
Continuous monitoring is essential because new vulnerabilities and threats emerge daily, and traditional periodic scans can't catch everything, especially zero-day vulnerabilities.
Runtime monitoring detects suspicious activities in real time, such as unusual processes, unexpected connections, and unauthorized changes, enabling rapid incident response.
AWS GuardDuty is an example of a runtime monitoring solution that collects logs from various sources (like EC2 and Aurora) to detect suspicious API calls, malware, and misconfigurations, providing comprehensive visibility across your cloud environment.
Security scanning pipeline
The security scanning pipeline makes use of automated SAST and DAST tools that integrate with CI/CD to perform security scanning on merge requests, artifact uploads, and pushing to the main branch.

Merge request security reports
The goal of merge request reporting is twofold.
- The first goal is to ensure that security vulnerabilities do not reach the main branch of an application.
- The second goal is to show developers where security vulnerabilities are with every commit they make to a merge request.
This helps developers catch vulnerabilities early, reducing the impact of security vulnerabilities during development.
SAST tools
SNYK
snyk is a static vulnerability analysis tool that also offers a CLI that lets you find out any vulnerabilities of code files.
Checkov
Checkov is a popular static code analysis tool used to scan cloud infrastructure configurations across major cloud providers, used for scanning vulnerabilities in IaC cocdebases.
- It works by applying pre-built policies that enforce security and compliance best practices, and you can also add custom policies if needed.
- In the pipeline you're watching, Checkov is installed and run to scan the entire code directory, generating a report of any security vulnerabilities found.
This helps catch issues early in the build process, ensuring your infrastructure code follows industry standards and improving overall security and compliance in your deployments.
Basics
Here's how to use it generally:
- Install checkov
pip3 install checkov
- Scan a directory
checkov --directory src/ --soft-fail -o junitxml --output-file-path checkovreport.xml
Here are the flags on the checkov command you can set:
--directory / -d: accepts a folder path to scan all code in--soft-fail: exits with a 0 exit code no matter what-o <output-style>: outputs the security testing analysis results in a certain output style, of which you have these possible values:junitxml: outputs results in XML
--output-file-path <filepath>: the filepath to publish test results to.
NOTE
Checkov always returns a zero exit code by default.
Skipping checkov checks
You can use comments with Checkov in order to skip checking certain problematic lines of code that you know are not vulnerabilities but Checkov flags them as false positives.

Trivy
Basic scan
After installation, you can begin scanning a configuration directory which contains the main.tf file by running the following command below:
trivy config --format template --template @contrib/html.tpl -o results.html 04_06/
Github action
# Trivy Scanning YAML File
name: Trivy Scan

on:
  push:
    branches:
      - main
    pull_request:

jobs:
  trivy_scan:
    runs-on: ubuntu-latest

    steps:
      # Checkout the repository
      - name: Checkout code
        uses: actions/checkout@v4

      # Run Trivy Scan
      - name: Run Trivy Scan
        uses: aquasecurity/trivy-action@0.32.0
        with:
          scan-type: config
          exit-code: "1"
          severity: "HIGH,CRITICAL"
DAST tools
OWASP Zap
OWASP ZAP (Zed Attack Proxy) is one of the most widely used open-source DAST tools. Ot os a PEN-testing tool that performs MITM attacks against your app to test it dynamically.

It can be operated via a Desktop GUI, a command-line interface, or an automated Docker container.
Docker networking issue
When running a DAST tool like OWASP ZAP inside a Docker container, it is isolated in its own virtual network. If you tell ZAP to scan http://localhost:3000, it will try to attack port 3000 inside itself and fail.
To bypass this and let the container reach services running on your host machine, you must use special host addresses:
- Linux/Windows/macOS: Use
http://docker.internalto route traffic out of the container network back to your host machine's ports.
Basic use cases
- Baseline Scan: Runs the spider for a few minutes to map the site and reports passive vulnerabilities without attacking.
docker run -t owasp/zap2docker-stable zap-baseline.py -t http://10.0.2.15:3000
- Full Scan: Performs a deep spidering process followed by an aggressive active scan against every uncovered parameter.
docker run -t owasp/zap2docker-stable zap-full-scan.py -t http://10.0.2.15:3000
- API Scan: Tailored for REST, GraphQL, or OpenAPI/Swagger structures.
docker run -t owasp/zap2docker-stable zap-api-scan.py -t http://10.0.2.15:3000 -f openapi
Application security
Application security means building software that is secure from the start by protecting it from vulnerabilities that attackers might exploit. It involves adding layers of protection to prevent unauthorized access, data breaches, and malicious attacks. This applies to all modern applications, including web apps, mobile apps, APIs, and microservices.
It's important because it helps safeguard sensitive data, ensures the stability of systems, prevents costly disruptions, maintains customer trust, and helps meet regulatory requirements.
Application security principles
Secure by design
Secure by Design in software applications means building security into the product from the very beginning rather than adding it later. It shifts the responsibility of security from users to developers and organizations. The approach is based on three core principles:
- Take ownership of customer security outcomes: Security features like multi-factor authentication and strong credentials are enabled automatically without user configuration.
- Embrace radical transparency and accountability: Organizations openly disclose vulnerabilities and share their security processes to build trust and improve continuously.
- Lead from the top: Senior leadership prioritizes security as a core business goal, ensuring proper resources and accountability.
Secure coding practices
- Memory safety is fundamental: Using languages like Rust, Go, Python, or Java can prevent common vulnerabilities like buffer overflows, or use compiler tools for C/C++.
- Input validation is your first defense: Always validate data types, length, character sets, and business logic to prevent injection attacks.
- Output encoding protects users: Encode outputs to prevent cross-site scripting (XSS) by ensuring user input is treated as plain text, not executable code.
- Defensive programming builds resilience: Implement fail-safe defaults, least privilege access, and error handling that avoids revealing sensitive system details.
- fail-safe defaults: deny by default if detection fails, prioritize security over convenience.
Secure by default
Secure by default in application configuration means that security features and settings are automatically enabled and correctly configured out of the box, without requiring manual setup by users or administrators.
Here are the common security settings to enable in a secure by default approach:
- HTTPS: force HTTPS and automatic redirect from HTTP to HTTPS
- session timeout: timeout sessions for all users to avoid hijacking somebody else's session
- secure cookies: make sure cookies are HTTP-only, secure, and lax.
- secure DB credentials: generate unique DB credentials on install
- disable debug modes and unused services in production: prevent security misconfiguration by ensuring there is a smaller attack surface, and no verbose logs that reveal too much info.
Supply chain attacks and SBOM
Your application is only as secure as the dependencies, frameworks, build tools, libraries, and CI/CD systems it relies on. DevSecOps extends beyond your code to securing the entire software supply chain.
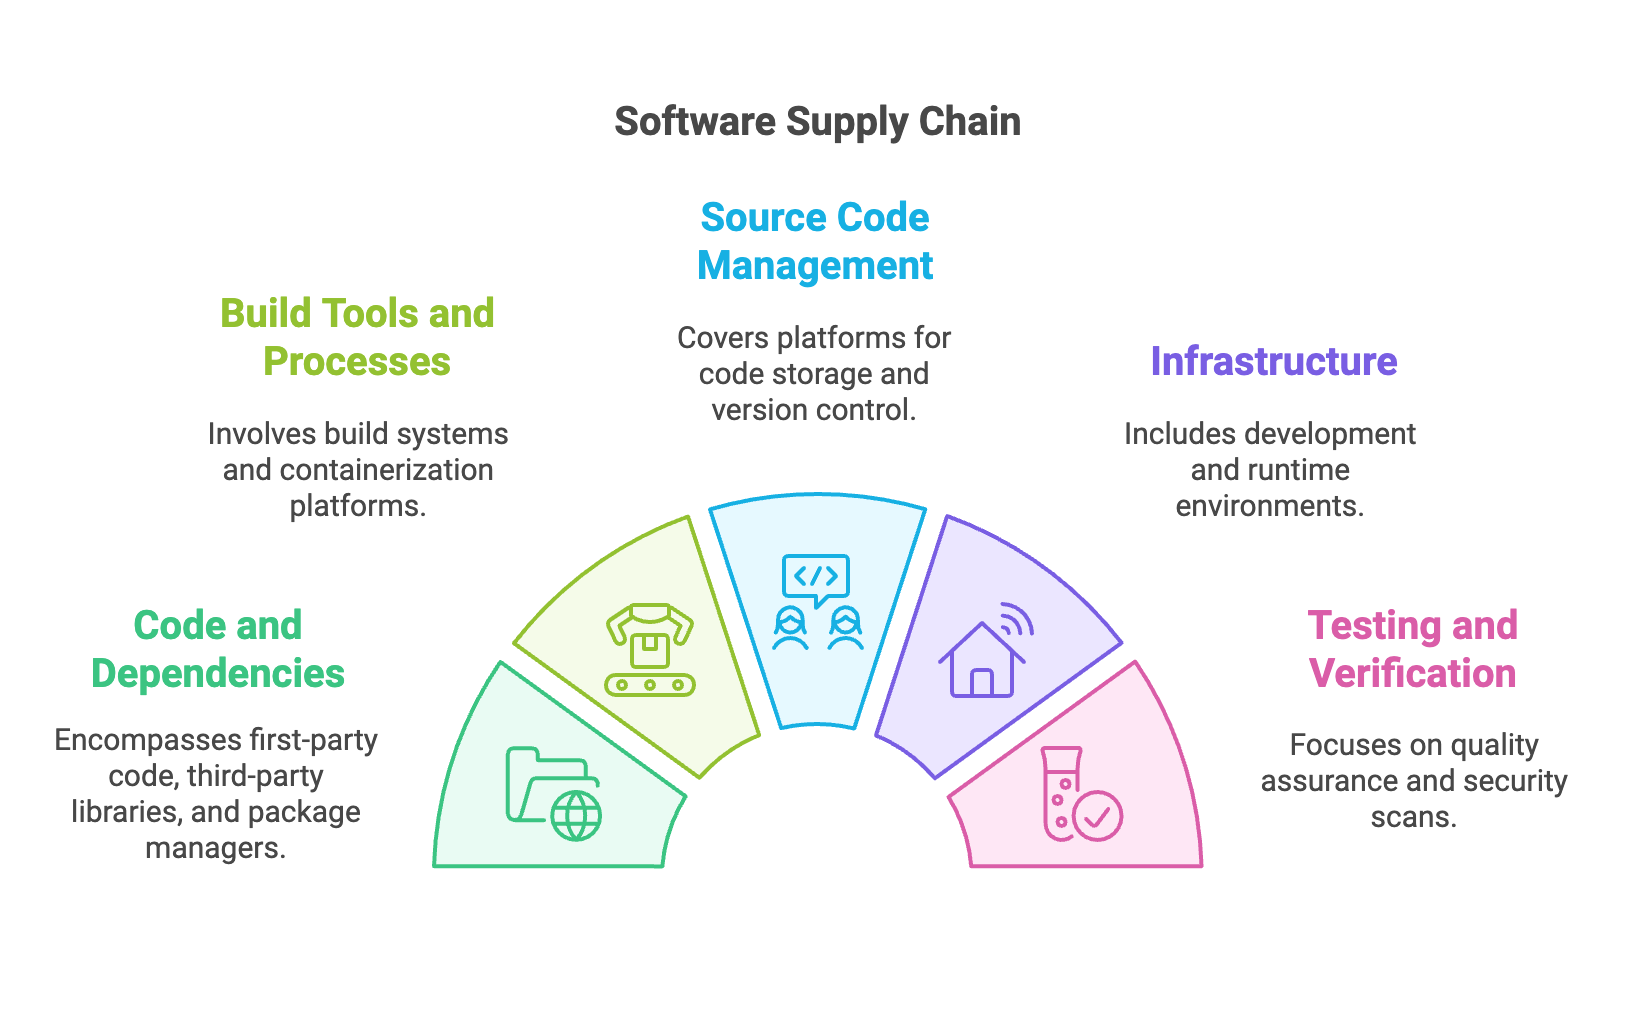
A supply chain attack happens when attackers compromise trusted software components or updates that your application depends on.
Instead of attacking your code directly, they infiltrate the software build or distribution process—like what happened in the SolarWinds breach—injecting malicious code into legitimate updates of third-party packages. This lets attackers access thousands of organizations while staying hidden for months.
NOTE
This attack is devastating because each third-party GitHub repo we use or each third-party NPM package we install becomes a possible attack vector.
NOTE
These attacks are dangerous because you’re not just trusting your own code but also all third-party libraries and tools you use.
SBOM
To defend against this, the course emphasizes using a Software Bill of Materials (SBOM), which is like an ingredient list detailing every component and its origin in your software.
A Software Bill of Materials (SBOM) is like an ingredient list for your software. It details all the components used in an application, including direct and transitive dependencies, along with their origins (pedigree) and authenticity (provenance). This comprehensive inventory helps you understand exactly what makes up your software.
An SBOM consists of three critical elements:
- inventory: lists direct and transitive dependencies
- direct dependencies: dependencies you explicitly install with npm commands
- transitive dependencies: the peer dependencies of direct dependencies, so you indirectly depend on these dependencies.
- pedigree: shows the complete origin and version control history of every code component.
- provenance: verifies the authenticity and integrity of components in code. It ensures that the code you downloaded is exactly what the author intended to publish.
SBOMs are important because they give you full visibility into your software supply chain, allowing you to quickly identify and respond to vulnerabilities.
For example, in supply chain attacks like the SolarWinds breach, attackers compromised trusted software updates to infiltrate thousands of organizations. With an SBOM, you can track and verify every component, reducing the risk of such attacks and enabling faster threat detection and response.
Dependency management
Along with SBOM, this is how you you perform dependency management:
- Systematic Evaluation: Use OWASP and industry criteria to assess open source components before adding them, focusing on maintainer credibility, release frequency, and vulnerability response.
- Dependency Pinning: Control exactly which versions of dependencies run in production through version pinning, lock files, or hash pinning, depending on your risk tolerance.
- Balanced Update Policies: Prioritize updates based on severity and stability, with immediate updates for critical vulnerabilities and scheduled updates for less severe issues.
Third-party vendor security frameworks
Third-party vendors pose significant security risks as attackers often exploit trusted partners to breach organizations, making systematic vendor risk management essential.
Three main frameworks help manage vendor security effectively:
- NIST Cybersecurity Framework 2.0 (with six core functions and supply chain risk focus)
- ISO 27001 (with comprehensive ISMS controls and certification requirements
- SOC 2 Type 2 (an evidence-based approach assessing operational effectiveness over time).
Continuous supply chain monitoring
Continuous supply chain monitoring in software security means continuously tracking and analyzing all software components and dependencies in real time to detect vulnerabilities and threats as soon as they appear.
Instead of periodic scans, it provides ongoing visibility into changes in your software bill of materials (SBOM) and integrates automated threat intelligence to prioritize risks based on severity and usage.
This proactive approach enables faster response to security issues, reducing the time from discovery to remediation from weeks to hours, and helps maintain a secure software supply chain.

Continuous supply chain monitoring is only possible with these core components:
- Realtime SBOM management: treats SBOM as a living inventory and constantly updates with each new deployment.
- automated threat intelligence integration: goes beyond detection of known vulnerabilities and also covers emerging threats.
Supply chain Compliance
The EU Cyber Resilience Act mandates maintaining a comprehensive, machine-readable Software Bill of Materials (SBOM), secure-by-default product configurations, formal vulnerability disclosure programs, and ongoing security updates throughout the product lifecycle.
Crowdstrike case study: incident response
Organizations that recovered faster from the CrowdStrike incident shared several key capabilities:

- They had mature supply chain monitoring systems that detected widespread issues quickly and activated incident response protocols.
- They maintained direct, pre-established communication channels with vendors, enabling fast technical guidance and coordinated response.
- They had dedicated teams trained for manual system recovery with clear roles specific to supply chain incidents.
- They implemented alternative processes to keep critical operations running during recovery.
- They used systematic recovery approaches prioritizing revenue-generating systems and had pre-positioned teams trained in complex recovery procedures.
In contrast, organizations lacking these capabilities treated the problem as isolated hardware failures, lacked vendor communication, and had poor recovery prioritization, resulting in prolonged downtime.
NOTE
This shows that preparation, monitoring, communication, and structured recovery planning are crucial for rapid incident recovery.
Secure logging and monitoring
Logging and monitoring are essential to create a complete audit trail to catch and flag suspicious activity. It has 4 pillars:
- authentication events: log every single authentication event, like logins, passwords changes, sessions ending, etc.
- authorization violations: log when users attempt to access resources they are unauthorized to access.
- data access events: log when sensitive data is accessed and by who
- system and configuration changes: log whenever security configuration or permissions change.
There are 6 essential attributes of a security log entry:
- who: unique identification of the prinicipal performing the action
- what: action attempted or performed
- when: timestamp with timezone
- where: system, application, or resource
- why: context for triggering the event
- outcome: success, failure, or partial completion

There are three ways to classify the severity of what you should log and the actions you should take based on those logs:
- high-severity (alert): for anything like multiple failed authentication attempts, suspicious data access patterns, and access to unauthorized resources, you should immediately alert point of contacts about the attempt.
- medium severity (monitor): unusual login times or locations, failed authorization attempts, or configuration changes
- low-severity: successful logins, usual attempts, maintenance
Artifact security
SLSA framework
The SLSA framework, which stands for Supply Chain Levels for Software Artifacts, is a security framework designed to improve software supply chain integrity.
It provides four graduated levels of security assurance in increasing competence, from no guarantees (Level 0) to maximum tamper protection with strict controls (Level 4).
- level 0 - no controls, test builds only: no supply chain information or SBOM generated
- level 1 - build automation and provenance: Basic supply chain visibility and provenance generated from metadata about the software build
- level 2 - version control and tamper protection
- level 3 - enforce hardened source and build platforms: prevents threats like cross-build contamination by using dedicated build platforms that handle stuff like build agents and runners.
- level 4 - requires two-person code reviews and hermetic builds:
Provenance is verifiable information about software artifacts describing where and when it was created, how it was produced, and who created it.
SLSA focuses on creating verifiable, tamper-evident records called build provenance, which document where, when, and how software was built—including details like the build platform, source repository, build recipe, dependencies, and cryptographic signatures. This helps ensure software authenticity and prevents supply chain attacks.

So SLSA creates build provenance through these 5 components:
- builder identity: which platform built the software
- source repository: the source code
- build recipe: how the software was built, and the build pipeline info
- materials: what dependencies were needed to build the app
- crypto signatures: proof of authenticity
Tools like the SLSA Verifier automate checking these records to confirm that software artifacts are trustworthy before deployment.
Digital signatures and artifact integrity
In order to ensure the integrity of artifacts, we need to use digital signatures to create tamper-evident artifacts where it makes unauthorized modifications of the artifact immediately detectable.
- what they are: Digital signatures protect software artifacts by providing cryptographic proof that the software has not been altered since it was signed.
- how they work: They mathematically bind the signature to both the content and the signer's identity, so even a single bit change invalidates the signature, making tampering immediately detectable.
- the resultThis ensures that software artifacts come from a trusted source and have not been modified during distribution, establishing a secure and trusted software supply chain.
- tools: Tools like Sigstore and Cosign automate this process, enabling verification that software is authentic and untampered before deployment.
Veracode basics
Application profiles
In simple terms, an application profile is a digital container or "folder" in the Veracode Platform that stores all the security information for a specific piece of software. You must create an application profile before you can submit a scan.
An application profile performs three main functions:
- Identifies your software: It stores the name, description, and business unit of the application you are testing.
- Sets security standards: It links your application to a specific security policy. This policy defines whether your application "passes" or "fails" based on the flaws and vulnerabilities found during scans.
- Organizes results: It aggregates results from different types of scans (such as Static Analysis and DAST) into a single report, allowing you to track security performance over time.
The number of different application profiles you need to create depends on the architecture of your application.
NOTE
In general terms you should think of an application profile as representing a single service, like a front end, a back end, or an individual microservice.
When you create a profile, you define several important details:
- Business criticality: How important the application is to your organization. This usually determines which security policy applies.
- Teams and owners: Who is responsible for the application and who has permission to view the scan results.
- Metadata and tags: Information used to organize and filter your applications within your portfolio.
IMPORTANT
You must create an application profile before you can submit a scan to Veracode.
Here are general tips
- One profile per application: We recommend creating one profile for a single application or monolith. For complex architectures, like microservices, you typically create multiple profiles.
- Data stays in the profile: Findings, mitigations, and comments are specific to an application profile and cannot be transferred to another profile.
Creating application profiles
- Go to My Portfolio -> Applications

- Fill out the application name, business criticality level, and any policies to attach for that level.

User roles and permissions
In the Veracode Platform, user access is controlled through roles, which are collections of specific permissions. These roles are assigned to user accounts to determine what actions they can perform.
In Veracode, there are two types of users:
- UI users: human users you add to your team and assign them roles
- API Users: These are non-human accounts used for automation (CI/CD pipelines). They have their own set of roles (e.g., Upload API, Results API).
Here are key permission concepts.
- Team Restrictions: Most technical roles (Creator, Submitter, Reviewer) require membership in a specific team to see that team's applications and data.
- Scan Type Restrictions: You can limit a user's role to specific scan types (e.g., only Static Analysis or only DAST).
Admin roles
These roles are responsible for managing the Veracode Platform itself and the users within it.
- Administrator: Manages users, teams, and SAML settings. This role can view most areas but cannot create or delete scans. Note: You cannot have both the Administrator and Team Admin roles.
- Team Admin: A localized version of the Administrator. They can manage users and teams but only within the specific teams they manage.
- Policy Administrator: Responsible for governance. They create and edit security policies, set default policies, and assign them to applications.
Tech and analysis roles
These roles are used by developers and security engineers to perform the day-to-day work of security testing.
- Security Lead: The most powerful technical role. They can create application profiles, view all scan results across the organization, submit any scan, and approve mitigations.
- Creator: Focused on the initial setup. They can create application profiles and workspaces for their assigned teams. They can also request and delete scans for those applications.
- Submitter: The primary role for developers. They can upload binaries and request scans for their teams' applications but cannot create or delete application profiles.
- Reviewer: A "read-only plus" role. They can view scan results, reports, and flaw details for their teams. They can propose mitigations but cannot approve them.
Specialized roles
Some roles provide targeted access to specific features or products.
- Mitigation Approver: Can approve or reject proposed mitigations (exceptions) for flaws.
- Sandbox Administrator / User: These roles allow users to create and scan in "sandboxes," which are private testing areas that do not affect an application's official policy compliance.
- Executive: Provides high-level visibility. They can view Analytics and reports for all applications in the organization.
- Security Labs (Admin/Manager/User): These roles are specific to Veracode's interactive training platform, Security Labs.
- Workspace Administrator / Editor: Specific to Veracode Software Composition Analysis (SCA) for managing workspaces and agents.
Security policies
Veracode security policies set a threshold of security requirements for your applications.
You can set them on:
- Individual application profile level
- Applies to all application profiles for a team
- Applies to all application profiles for a portfolio
NOTE
Veracode security policies are the governing standards that define an organization's security requirements for its applications.
A security policy is built from several key constraints called security policy constraints:
- Rules: These define which types of findings are prohibited. You can set rules based on:
- Severity: e.g., "No findings with a severity of Very High or High."
- CWE Categories: e.g., "No SQL Injection or Cross-Site Scripting (XSS)."
- CVSS Score: e.g., "No findings with a CVSS score greater than 7.0."
- Veracode Level (VL): A pre-defined security tier (VL1 to VL5) based on scan types and results.
- Scan Requirements: This mandates that specific scan types (Static, Dynamic, SCA, or MPT) must be performed at a minimum frequency (e.g., "Must perform a Static Analysis scan every 30 days").
- Remediation Grace Periods: This gives developers a window to fix violations before the application officially fails policy. For example, you might allow 30 days to fix "High" severity flaws and 90 days for "Medium."
- evaluation timeframe: defines the period during which findings violate the policy.

When a scan is completed, the results are evaluated against these rules to determine if the application is Pass or Fail (Policy Compliance status).
An application's compliance status is calculated based on the latest results of its policy scans:
- not assessed: the application has not yet had a policy level scan run on it.
- Pass: The application meets all rules and scan requirements, and no grace periods have expired.
- Did Not Pass: The application violates one or more rules or has failed to meet a scan requirement within the required timeframe.
- Conditional Pass: The application has open findings that violate policy, but they are still within their grace period.

If a finding cannot be fixed (e.g., a false positive or an acceptable business risk), a user can propose a Mitigation.
If a Mitigation Approver accepts the proposal, that specific finding is excluded from the policy evaluation, allowing the application to pass even if the code remains unchanged.
Types of policies
There are three main types of built-in policies that Veracode provides:
- transitional policies: Not recommended, very simple, leads to false positives.
- recommended policies: built-in better policies for business criticality
- SCA policies: policies directly meant for SCA (software composition analysis)
For all of these policies, you have them categorized into strictness levels: "low", "medium", "high", or "very high."
Security policy planning
Security policy planning is a strategic process used to establish a consistent set of security standards across your entire application portfolio. Effective planning ensures that your security goals are technically sound and achievable for your development teams.
business criticality
When you create an application profile, you assign it a Business Criticality (Very High to Very Low).
The foundation of your policy plan is identifying how important each application is to your business. This determines the level of scrutiny and risk tolerance for that application.
- Very High/High: Mission-critical applications (e.g., customer-facing financial portals). These require the strictest rules and frequent scanning.
- Medium: Applications with moderate risk (e.g., internal HR systems).
- Low/Very Low: Non-critical applications with no sensitive data.
policy constraints
Your policy is built from specific rules that dictate what "security" looks like for your organization:
- Finding Rules: Prohibit findings based on Severity (e.g., no Severity 4 or 5 flaws), CWE Category (e.g., no SQL Injection), or CVSS Score (e.g., nothing above 7.0).
- Scan Requirements: Specify which scans must be run and how often. For high-criticality apps, we recommend performing Static (SAST), Dynamic (DAST), and SCA (open-source) scans at least every 30 days.
- Remediation Grace Periods: Set realistic deadlines for fixing violations. For example, you might allow 30 days to fix "High" severity flaws but 90 days for "Medium."
strategy and rollout
- Uniformity: Use policies to enforce a uniform standard across different teams and business units.
- Phased Approach: Start with achievable goals (e.g., "Fix all Critical flaws in 30 days") and gradually tighten the policy as your security posture improves.
- Stakeholder Alignment: Involve AppSec managers, security leaders, and developers in the planning process to ensure the grace periods and rules are practical.
continuous monitoring
- Review Compliance: Use the Policy Evaluation section in the Veracode Platform to monitor which applications are passing or failing.
- Adjust as Needed: If applications are consistently failing due to unrealistic grace periods, review and adjust the policy to better balance security and speed.
Creating custom policies
NOTE
You must have the policy administrator tole to perform policy maintenance activities.
- GO to policies -> policy to create a new policy

- Add the policy name and description

- Add a new rule. IN this example, we select basic CWE vulnerabilities like SQL injections to look for.

Veracode Tools
Veracode CLI
Installation
Check out:
Install the Veracode CLI | Veracode Docs
Authentication
You can authenticate with Veracode in the following ways:
- SSO: If your organization uses single sign-on (SSO), use OAuth to sign in with your username and password.
- HMAC (static API credentials): If your organization doesn't use SSO, use your API credentials to authenticate with Veracode using HMAC. When using the CLI in automation, such as scripts, use HMAC authentication.
SSO Auth
Use OAuth authentication if your organization uses SSO and you interact directly with the CLI.
TIP
When using the CLI in automation, where you do not interact with the CLI, then use HMAC with a veracode credentials file.
-
In the CLI, run:
veracode auth login -
Enter your username and password.
-
Select Sign in to authenticate. You can now return to the CLI.
HMAC Auth
Use HMAC authentication to authenticate with Veracode using your API credentials. Use this method if your organization doesn't use SSO, or you're using Veracode CLI for automation, such as in a script.
To setup Veracode integrations you need to store the Veracode API credentials for your user locally on your device in a Veracode credentials file, which usually lives in a ~/.veracode/credentials file on your local machine.
NOTE
To authenticate both the CLI and the VS Code extension, you need Veracode API credentials and then store them in a ~/.veracode/credentials file.
- From your user profile menu, select API Credentials.

- Select Generate API Credentials and save the ID and Secret Key.

- Store your credentials in a file named
credentialsin a.veracodefolder in your home directory:- Windows:
C:\Users\<username>\.veracode\credentials - macOS/Linux:
~/.veracode/credentials
- Windows:
[default]
veracode_api_key_id = <YOUR_API_ID>
veracode_api_key_secret = <YOUR_API_SECRET>
Or optionally, authenticate with HMAC by running the veracode configure command, which pulls the generated API credentials from your veracode account and automatically populations the ~/.veracode/credentials file with those credentials:
- Set the environment variables for the API credentials:
set VERACODE_API_KEY_ID=<your_API_ID>
set VERACODE_API_KEY_SECRET=<your_API_key>
- Run the
veracode configurecommand to read those env vars
veracode configure
Veracode CLI with github and gitlab
You can authenticate your GitHub and GitLab repositories using the GITHUB_TOKEN and GITLAB_TOKEN environment variables, respectively. These variables store your personal access token (PAT) and are used when you run commands such as veracode scan and veracode repository add.
To configure the environment variable for authenticating your GitHub repository, run:
export GITHUB_TOKEN=<your_github_token>
To configure the environment variable for authenticating your GitLab repository, run:
export GITLAB_TOKEN=<your_gitlab_token>
Veracode Fix
Veracode Fix is an AI-assisted remediation solution that generates secure code patches for security findings found in your application.
It supports both Static Analysis (SAST) flaws and Software Composition Analysis (SCA) vulnerabilities across several languages, including Java, C#, JavaScript, TypeScript, and Python.
NOTE
To use Veracode Fix, you must have a Veracode account with the Submitter role.

Veracode fix CLI
You can use veracode fix with the CLI
The following table shows the available commands for each Fix product and their supported flags:
| Product | Command | Without --remote | With --remote |
|---|---|---|---|
| Fix for SAST | veracode fix | Supported | Not available |
| Fix for SCA | veracode fix sca <source> | Not available | Supported |
NOTE
The --remote flag is required for Fix for SCA and is not available for SAST fixes. It enables server-side processing for SCA, which supports batch operations and handling of complex dependency changes.
Veracode fix github action
The Veracode Fix GitHub action is a GitHub app in the marketplace that you can install and then it would run Veracode scans on any of your pull requests.

Veracode Scan - VSCode
The VSCode Veracode scan extension allows you to run veracode application profile security testing on your codebase and then view the results directly in the IDE.
Here is the high level overview behind how Veracode Scan for VSCode allows you to expedite your security testing workflow:
- Packages your project
- Uploads your packaged project to Veracode for scanning against an application profile.
- Downloads the results and then displays them in your IDE
Veracode scan is a combination of three key components:
- static analysis: uses Veracode's static analysis testing to find application security vulnerabilities on your codebase using SAST. ALso highlights technical debt and insecure coding patterns.
- SCA: uses Veracode's software composition analysis to find vulnerabilities in third-party packages using agent-based testing.
- Veracode Fix: generates code patches to remediate some of the identified flaws or vulnerabilities using AI.
Setup
Here are the steps to set it up:
- Ensure that your veracode account has a submitter role.
- Download the Veracode Scan extension in VSCode
- Authenticate with SSO in the extension or use HMAC with the
~/.veracode/credentialsfile after generating API credentials.

- Install the local agent for SCA

SCA
For SCA, you must enable a policy to filter out which SCA vulnerabilities you actually want to care about.

Veracode fix
Vulnerability flaws that appear with a blue icon means that Veracode Fix can automatically fix them.

Qodana
Qodana is a SAST tool that has great integrations with CI/CD and IDEs. Qodana is delivered as a Docker image, making it portable and compatible with virtually any CI system, such as GitHub Actions, GitLab CI/CD, and TeamCity
IMPORTANT
Running Qodana locally requires the Docker engine to be on.
Here are all the tools Qodana offers:
- CLI: CLI for running SAST on your codebase
- CI/CD: actions for Github actions, Gitlab workflows, Teamcity, Jenkins, etc.
- IDE plugin: run Qodana SAST analysis from your IDE
You control the analysis through a qodana.yaml configuration file placed in your project root. This file tracks your settings, including enabled inspections and excluded directories
- Qodana provides a visual dashboard to monitor project state, filter results, and track progress over time. Y - ou can even click an "Open in IDE" button to jump directly to specific issues within your local IntelliJ IDEA project The main differences between the Qodana Community (free) and Qodana Ultimate plans revolve around the breadth of inspection coverage, advanced security features, and enterprise-grade support.
Qodana Community (Free)
- Core Inspection Set: Provides access to the essential, open-source static analysis inspections derived from JetBrains IDEs.
- Standard CI/CD Integration: Ideal for open-source projects or smaller teams that need basic code quality checks without complex security requirements.
- Limited Scope: Focuses on general code health, structural issues, and best practices that are part of the standard IntelliJ inspection profiles.
Qodana Ultimate
- Comprehensive Inspections: Unlocks the full suite of static analysis tools, including deep inspections that cover a wider range of frameworks and languages.
- Advanced Security & Compliance: Includes specialized security features, such as OWASP taint analysis and more rigorous checks to help meet professional and enterprise security standards.
- Baseline & Filtering: Allows for more advanced reporting, such as setting a "baseline" to ignore legacy issues and focus only on new code quality regressions.
- Enterprise Features: Designed for teams and businesses, offering enhanced support, better integration with enterprise CI/CD pipelines, and capabilities often required for compliance or regulated environments.
In summary, while the Community plan is a powerful tool for maintaining general code quality, the Ultimate plan is built for professional teams that require deeper security vulnerability detection, advanced compliance reporting, and broader language support.
Basics
Project tokens, CI/CD
Tokens
Each project in Qodana Cloud requires a specific unique token to establish a connection with your CI/CD pipeline, local CLI, or IDE to a specific Qodana project.
When you create a new project in Qodana Cloud, it generates this token so that your CI server, such as GitHub Actions, can authenticate and successfully upload the results of your code quality scans
once you connect your local qodana scans to a qodana project in the cloud via a project token, qodana cloud will store the scan history for you.

Here is how to create a new qodana project in qodana cloud and then connect it to your CI/CD pipeline in Github
- Go to qodana cloud and click on create new project, then put in your github repo URL

- Copy the qodana project token
- Set up the CI pipeline in Github which uses the
qodanaaction
name: Qodana
on:
  workflow_dispatch:
  pull_request:
    branches: [main bks]
  push:
    branches:
      - master

jobs:
  qodana:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v3
        with:
          fetch-depth: 0
      - name: 'Qodana Scan'
        uses: JetBrains/qodana-action@v2023.3
        with:
          args: --apply-fixes
          pr-mode: false
          push-fixes: pull-request
        env:
          QODANA_TOKEN: ${{ secrets.QODANA_TOKEN }}
- Add a
secrets.QODANA_TOKENrepository secret

Configuration
Qodana supports two major places to configure behavior:
qodana.yaml- The thing launching Qodana, such as Qodana CLI, Docker, your IDE, or CI/CD system.
JetBrains specifically recommends YAML for configuration that would otherwise produce long commands, particularly inspection settings and bootstrap.
Tool-level settings can override settings from qodana.yaml
NOTE
Think of qodana.yaml as the configuration describing what Qodana should do, and the CLI, CI/CD, or IDE as the execution medium for executing Qodana.
Basics - linter, profiles, inspections
This is a basic qodana.yaml:
version: uses version 1.0 for the configuration schemalinter: points to thejetbrains/qodana-jvm:2026.2as the image for running SAST analysis on a JVM project'profile: the specific profile to use for the SAST setup. In this case, we use the starter profile.
version: "1.0"

linter: jetbrains/qodana-jvm:2026.2

profile:
  name: qodana.starter
Here is some terminology:
- linter: the Qodana analysis environment appropriate for your technology stack,
NOTE
You use a JVM linter image for JVM projects, and node linter image for node projects.
- profile: a set of inspections and the files they are applied to, representing the full security testing and linting procedure against an application.
- inspection: a single vulnerability to inspect, which contains patterns and rules.
NOTE
In Qodana, a profile is a customizable set of inspections and rules applied to your files
- Customization: You can define which checks are active, disable specific categories, or exclude entire folders (like test directories) from analysis to fit your team's standards
- Automation: These profile adjustments are automatically reflected in your
qodana.yaml, ensuring that every CI run follows your customized ruleset
Qodana provides these built-in profiles to use:
empty: empty profile containing no inspections, which you can use to fully customize and use manual configuration.qodana.sanity: very small sanity checks.qodana.starter: small ruleset, basic security testsqodana.recommended: larger ruleset, a more comprehensive profile intended for CI/CD and largely corresponding to the default inspection profile
Think of profiles and linters in this hierarchy:
LINTER
qodana-jvm
    │
    └── PROFILE
        qodana.recommended
            │
            ├── Inspection A
            ├── Inspection B
            ├── Inspection C
            ├── Inspection D
            └── ...
Bootstrapping
For applications
Profiles and inspections
Dashboard
The Qodana dashboard has several things you can do with it.
SARIF
SARIF is industry-standard file format used to exchange static analysis results between different tools.
After Qodana completes a code scan, it generates a SARIF file containing the analysis findings, which is then pushed to the cloud dashboard for visualization and integration with the IDE plugin.
Baseline and quality gate
By moving existing issues into the baseline, you can effectively hide them from current reports, allowing you to configure a quality gate that focuses exclusively on identifying and blocking newly introduced issues in your code
A quality gate is a configuration feature within a CI (Continuous Integration) pipeline, such as in Qodana, used to enforce code standards before changes are merged into the main codebase.
It works by:
- Defining criteria: You set specific thresholds for code quality, such as a limit on the number of new issues allowed or minimum required code coverage
- Blocking merges: If the scan identifies new issues that violate these established thresholds, the pipeline will cause the build to fail, preventing the problematic code from being merged.
- Focusing on new code: When combined with a baseline—which hides pre-existing technical debt—a quality gate ensures that developers only focus on and address newly introduced problems in their current work.
To set a quality gate in Qodana, follow these steps within your project's configuration:
- Define the Baseline: Before configuring the gate, it is recommended to move existing technical debt into a baseline. This ensures the quality gate only blocks builds based on new issues rather than pre-existing ones
- Configure Criteria: Navigate to the quality gate settings where you can define thresholds based on various criteria, such as specific issue severity (e.g., critical or high) or required code coverage percentages
- Apply to Pipeline: Once configured, the quality gate integrates into your CI/CD pipeline. If a scan detects new issues that exceed your set thresholds, the pipeline will cause the build to fail, effectively preventing the code from being merged
Filters
Here's an example of creating a filter and then saving the filter so you can reuse it later.

Inspections and profile
You can enable or disable inspections from the dashboard by looking at the found problems and then clicking on More actions and then disabling the inspection category or the specific inspection.

You can edit the profile in the dashboard directly and then download the modified qodana.yaml to put that into your project root.
TIP
If you have the Qodana IntelliJ IDE extension installed, edits int he UI automatically update the qodana.yaml in your IDE.
Comparing against builds
The UI stores all previous scans and scan history, so you can compare scan histories to see what bugs got fixed or introduced.

CLI
The CLI is just a wrapper around the Qodana Docker image that runs the container against a profile.
Installation
Here is how to install on Windows:
scoop bucket add jetbrains https://github.com/JetBrains/scoop-utils
scoop install qodana
Here is how to install on Mac:
brew install jetbrains/utils/qodana
How to install on Linux:
curl -fsSL https://jb.gg/qodana-cli/install | bash
Setup
To run SAST in the cloud, you need a QODANA_TOKEN env var to authenticate with a specific qodana project:
QODANA_TOKEN="***********************************MzHc"
qodana scan
Then the dashboard results will appear in the cloud after the scan.
You can also set up completions like so:
qodana completion bash
qodana completion powershell
qodana completion zsh
qodana init
Running qodana init in a project will set up the qodana.yaml for you, choosing the linter image and configuration version
qodana scan
qodana scan --show-report --port 8888 --print-problems
--show-report: shows the qodana dashboard in localhost--port <port-number>: hardcodes the port for the qodana dashboard--profile <profile>: the specific profile to use--print-problems: if set, then shows all inspections from the profile.
IDE plugin
Here is how to use the Jetbrains IDE plugin with Qodana:
- Navigate to the Problems tool window and click the Qodana tab4
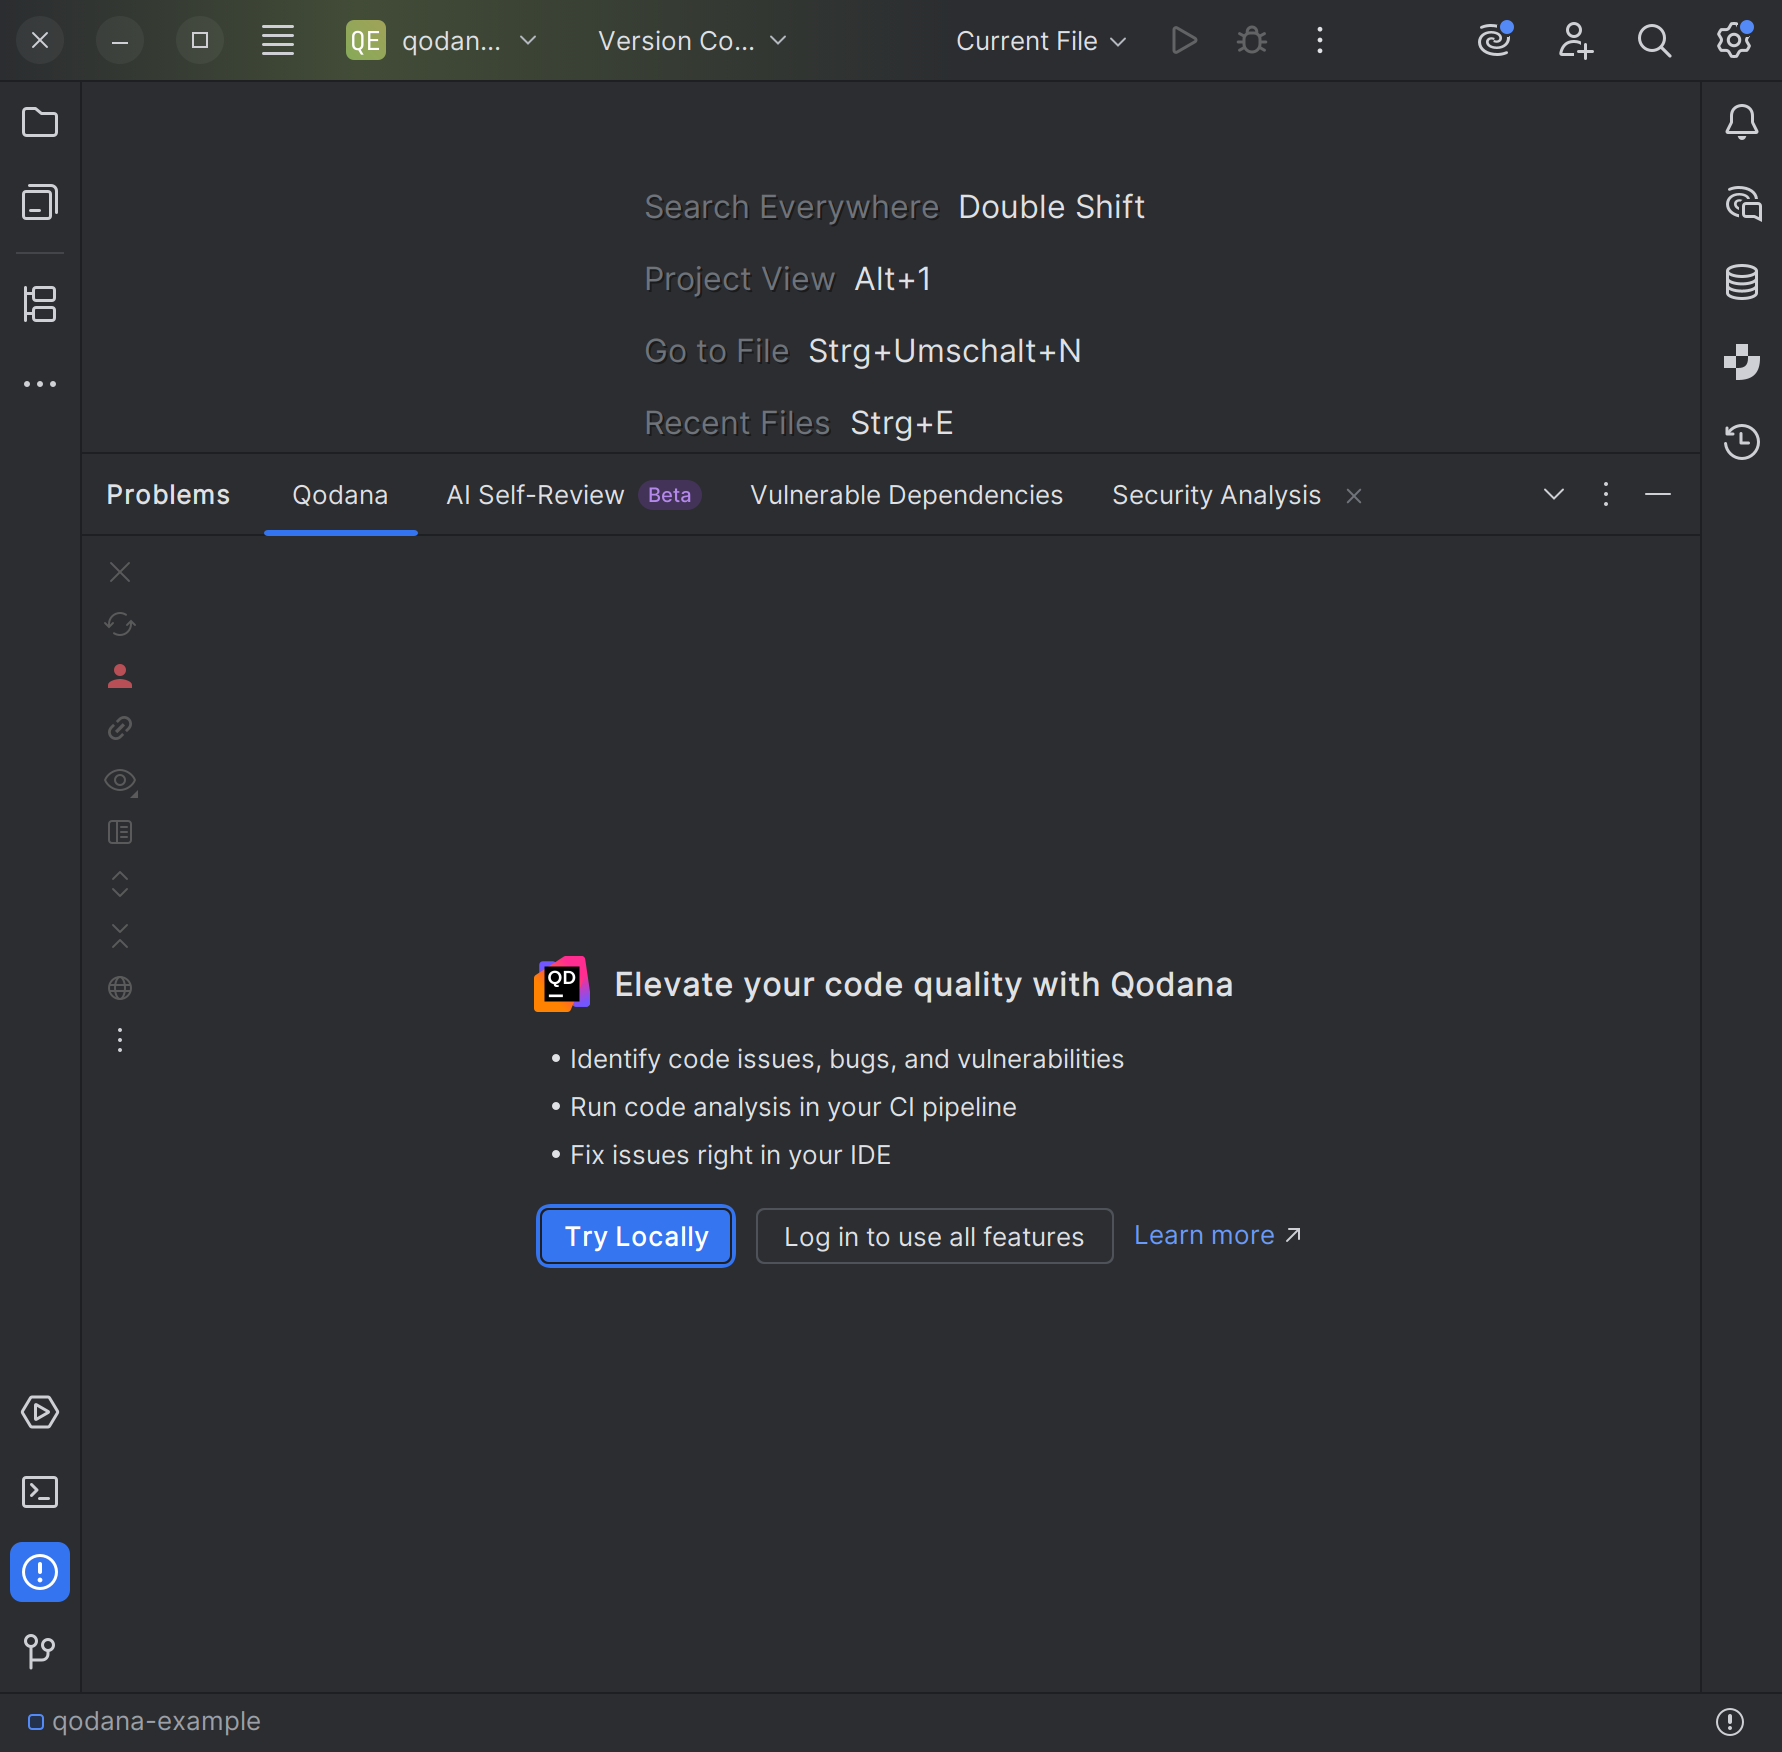
- Log in or try locally and then paste in the qodana token, then add the
qodana.yamlto the project root.
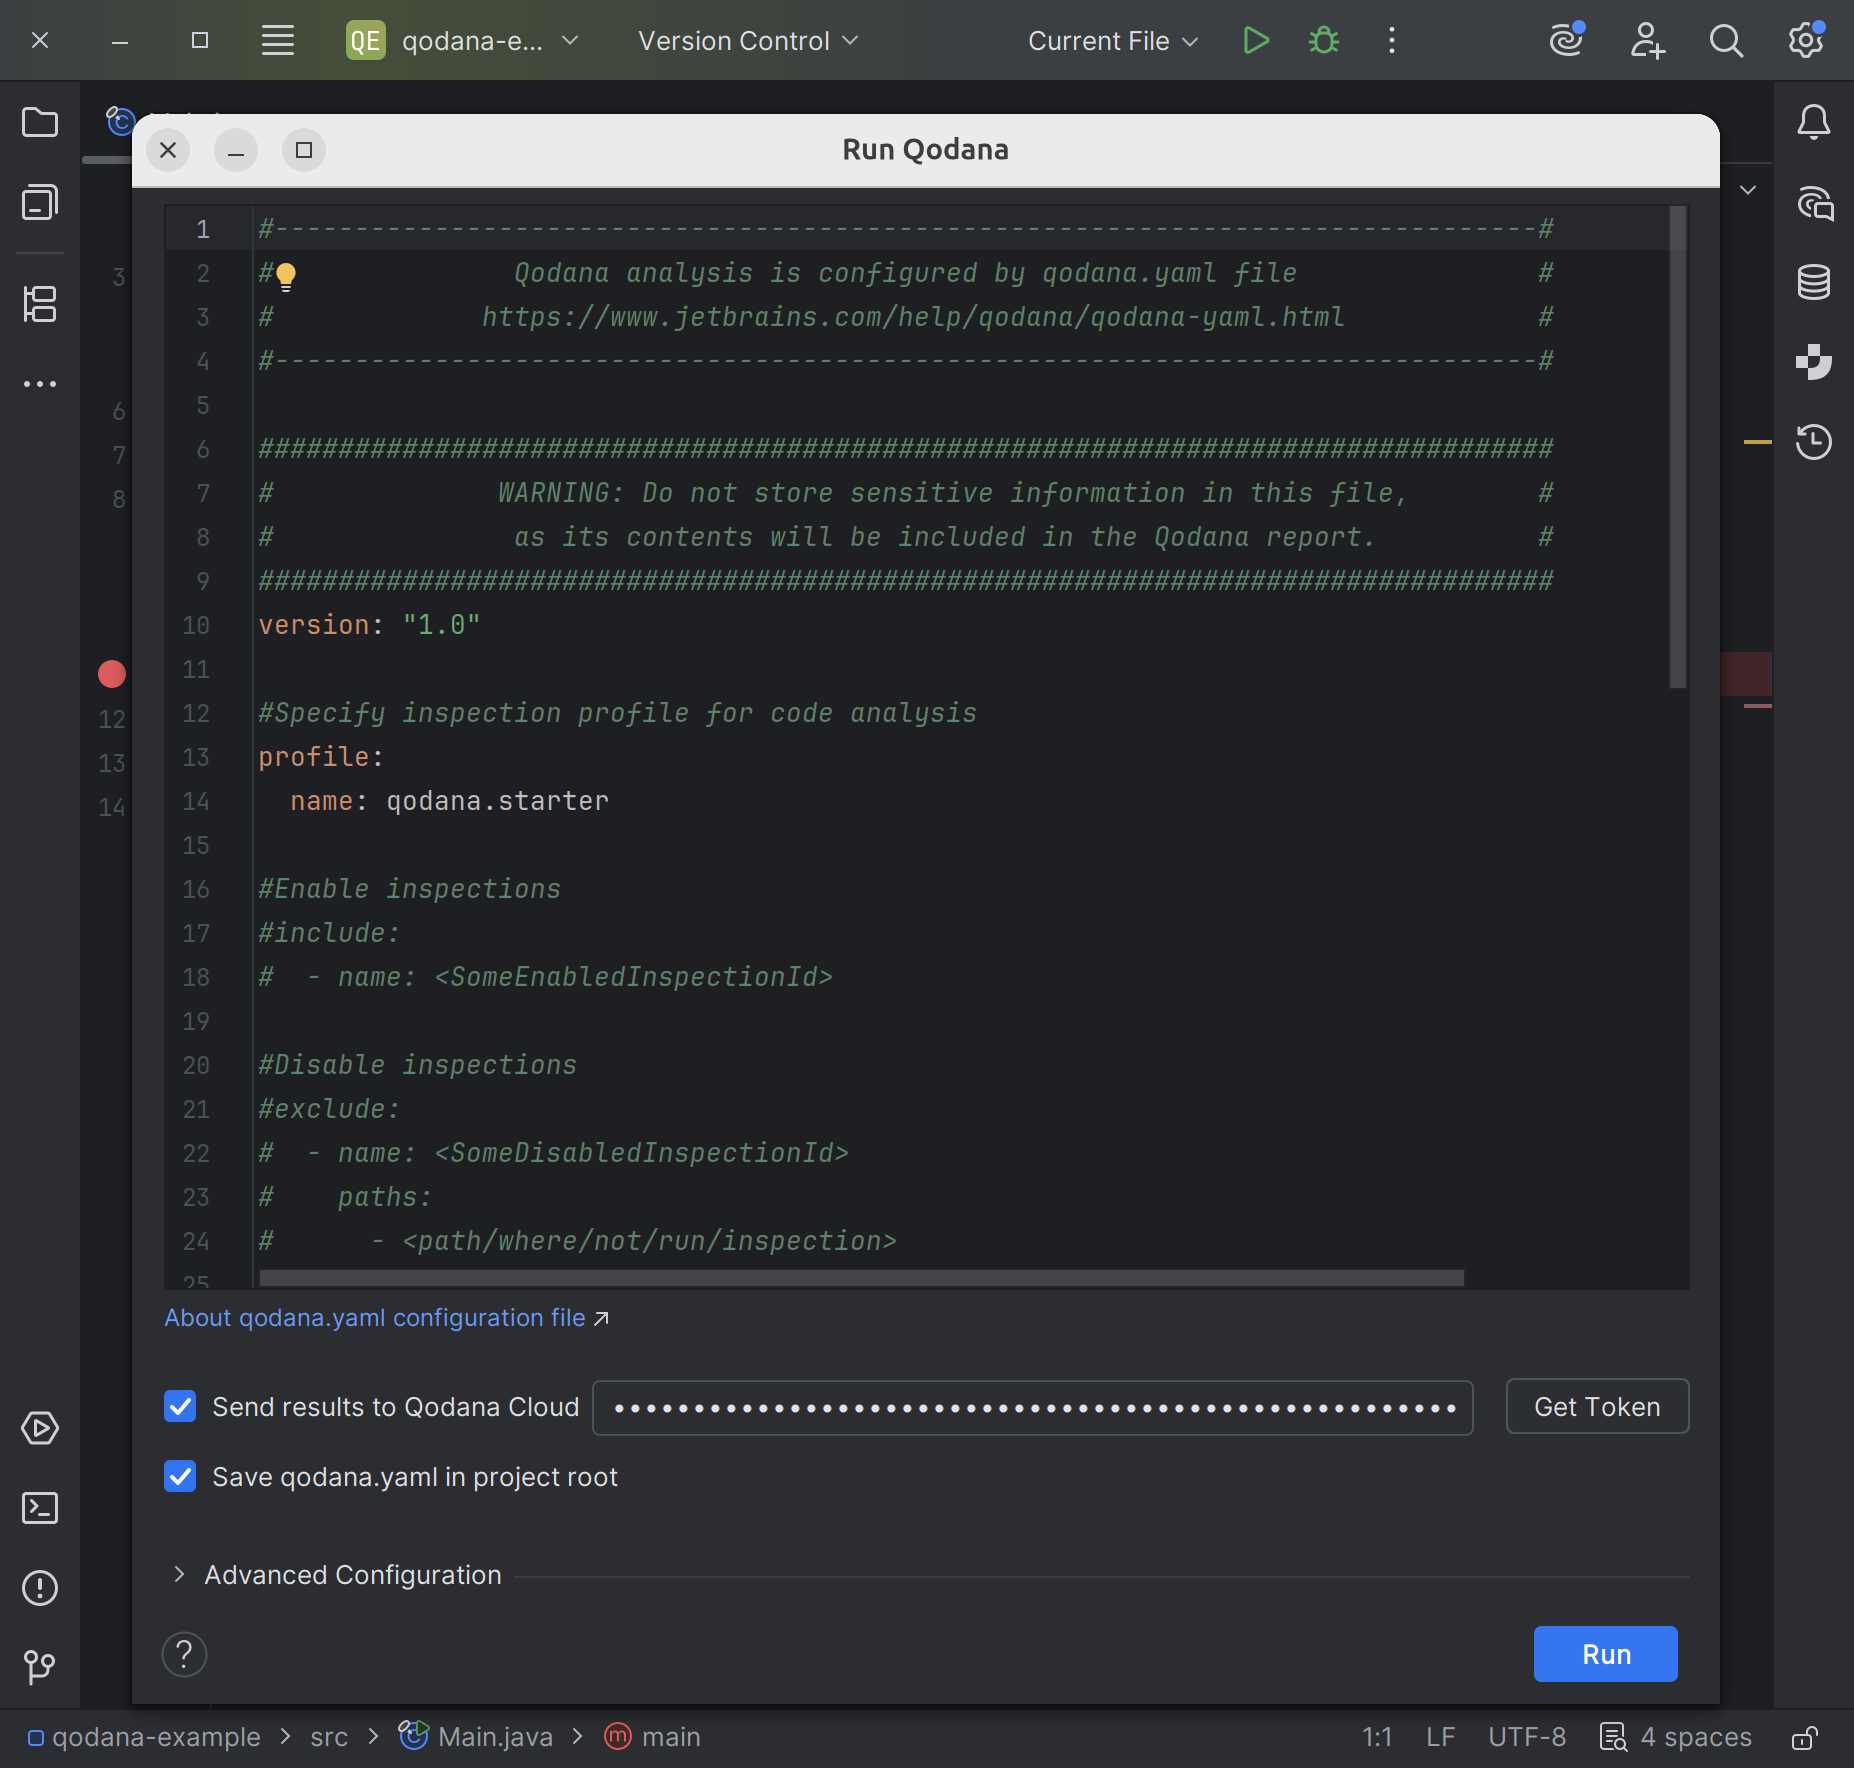
- After the scan runs, click on Open Qodana report in browser

CI/CD
CI/CD in Qodana allows you to shift security left:
                 Developer
                     |
                     v
                 Git push
                     |
                     v
               CI pipeline
                     |
                     v
              Qodana analysis
                     |
           +---------+---------+
           |                   |
        passes              violates
      quality gate         quality gate
           |                   |
           v                   v
       continue               fail
Github
#-------------------------------------------------------------------------------#
#        Discover additional configuration options in our documentation         #
#               https://www.jetbrains.com/help/qodana/github.html               #
#-------------------------------------------------------------------------------#

name: Qodana
on:
  workflow_dispatch:
  pull_request:
  push:
    branches:
      - master
      - testing-zone/DVPS-3364-3365

jobs:
  qodana:
    runs-on: ubuntu-latest
    permissions:
      contents: write
      pull-requests: write
      checks: write
    steps:
      - uses: actions/checkout@v4
        with:
          ref: ${{ github.event.pull_request.head.sha }}
          fetch-depth: 0
      - name: 'Qodana Scan'
        uses: JetBrains/qodana-action@v2026.2
        env:
          QODANA_TOKEN: ${{ secrets.QODANA_TOKEN }}
        with:
          # When pr-mode is set to true, Qodana analyzes only the files that have been changed
          pr-mode: false
          use-caches: true
          post-pr-comment: true
          use-annotations: true
          # Upload Qodana results (SARIF, other artifacts, logs) as an artifact to the job
          upload-result: false
          # quick-fixes available in Ultimate and Ultimate Plus plans
          push-fixes: 'none'
Here's another example:
name: Qodana
on:
  workflow_dispatch:
  pull_request:
    branches: [main bks]
  push:
    branches:
      - master

jobs:
  qodana:
    runs-on: ubuntu-latest
    permissions:
      contents: write
      pull-requests: write
      checks: write
    steps:
      - uses: actions/checkout@v3
        with:
          fetch-depth: 0
      - name: 'Qodana Scan'
        uses: JetBrains/qodana-action@v2023.3
        with:
          args: --apply-fixes
          pr-mode: false
          push-fixes: pull-request
        env:
          QODANA_TOKEN: ${{ secrets.QODANA_TOKEN }}
Here are all the args you can pass:
args: the command line arguments to pass--apply-fixes: will try to apply automatic fixes to findings
pr-mode: boolean, where if set to true, will only analyze changed files in the commit, and if false, analyzes entire codebase.push-fixes: if the CLI command was run with--apply-fixes, will submit those code changes for fixing those findings as a pull request.
GItlab
#-------------------------------------------------------------------------------#
#        Discover additional configuration options in our documentation         #
#              https://www.jetbrains.com/help/qodana/gitlab.html                #
#-------------------------------------------------------------------------------#

include:
  - component: $CI_SERVER_FQDN/qodana/qodana/qodana-gitlab-ci@v2026.2
    inputs:
      # When mr-mode is set to true, Qodana analyzes only the files that have been changed
      mr-mode: false
      use-caches: true
      post-mr-comment: true
      # Upload Qodana results (SARIF, other artifacts, logs) as an artifact to the job
      upload-result: false
      # quick-fixes available in Ultimate and Ultimate Plus plans
      push-fixes: 'none'

qodana:
  rules:
    - if: $CI_PIPELINE_SOURCE == "merge_request_event"
    - if: $CI_COMMIT_BRANCH == "master"
    - if: $CI_COMMIT_BRANCH == "testing-zone/DVPS-3364-3365"
Teamcity
import jetbrains.buildServer.configs.kotlin.*
import jetbrains.buildServer.configs.kotlin.buildFeatures.perfmon
import jetbrains.buildServer.configs.kotlin.buildSteps.qodana
import jetbrains.buildServer.configs.kotlin.triggers.vcs
import jetbrains.buildServer.configs.kotlin.vcs.GitVcsRoot

version = "2022.10"

project {
  vcsRoot(ProjectVcsRoot)
  buildType(Build)
}

object Build : BuildType({
  name = "Build"
  vcs {
    root(ProjectVcsRoot)
  }
  steps {
    qodana {
      name = "Qodana Step"
      reportAsTests = true
      linter = jvm {}
    }
  }
  triggers {
    vcs {}
  }
  features {
    perfmon {}
  }
})

object ProjectVcsRoot : GitVcsRoot({
  name = "https://gitlab.compusearch.com/devops/teamcityci/prismci.git#refs/heads/master"
  url = "https://gitlab.compusearch.com/devops/teamcityci/prismci.git"
  branch = "refs/heads/master"
  branchSpec = """
    refs/heads/testing-zone/DVPS-3364-3365  """.trimIndent()
})
DevSecOps pipeline creation
Gitlab
- Create a YAML like so
# This file is a template, and might need editing before it works on your project.
# To contribute improvements to CI/CD templates, please follow the Development guide at:
# https://docs.gitlab.com/ee/development/cicd/templates.html
# This specific template is located at:
# https://gitlab.com/gitlab-org/gitlab/-/blob/master/lib/gitlab/ci/templates/Getting-Started.gitlab-ci.yml

# This is a sample GitLab CI/CD configuration file that should run without any modifications.
# It demonstrates a basic 3 stage CI/CD pipeline. Instead of real tests or scripts,
# it uses echo commands to simulate the pipeline execution.
#
# A pipeline is composed of independent jobs that run scripts, grouped into stages.
# Stages run in sequential order, but jobs within stages run in parallel.
#
# For more information, see: https://docs.gitlab.com/ee/ci/yaml/index.html#stages

image: docker:19.03.12

services:
  - docker:19.03.12-dind

before_script:
  - docker info
  - apk --update add npm                 # Install npm so we can use npm install

stages:          # List of stages for jobs, and their order of execution
  - build
  - test
  - security
  - deploy

build-job:       # This job runs in the build stage, which runs first.
  stage: build
  script:
    - echo "Compiling the code..."
    - echo "Compile complete."
    - npm install            # This job will run npm install in our example but could be anything
  artifacts:
    paths:
    - node_modules          # Save the node_modules folder so we can use it in the security-test-sca job

unit-test-job:   # This job runs in the test stage.
  stage: test    # It only starts when the job in the build stage completes successfully.
  script:
    - echo "Running unit tests... This will take about 60 seconds."
    #- sleep 60
    - echo "Code coverage is 90%"

lint-test-job:   # This job also runs in the test stage.
  stage: test    # It can run at the same time as unit-test-job (in parallel).
  script:
   - echo "Linting code... This will take about 10 seconds."
    #- sleep 10
   - echo "No lint issues found." #test comment for commit

security-test-dast:   # This job runs in the security stage.
  stage: security
  script:
    - echo "Security DAST testing..."
    - docker run -d -p 3000:3000 --name juice-shop bkimminich/juice-shop  # Run juice-shop so we have something to test
    - containerip=$(docker inspect -f "{{ .NetworkSettings.Networks.bridge.IPAddress }}" juice-shop)   # Get container IP so we can test it
    - docker run -t --name dast owasp/zap2docker-stable zap-baseline.py -t http://$containerip:3000 || failure=true  #run DAST testing against juice shop container
    - if [[ "$(docker logs dast >& container-logs ; cat container-logs | grep 'WARN-NEW. [1-9]\d*'  | wc -l)" -gt 0 ]]; then echo 'Failing job due to identified failures'; exit 1; else echo "no issues found"; exit 0; fi  # If issues are found, fail job, if no issues are found pass job

security-test-sast:
  stage: security
  script:
    - echo "Security SAST testing..."
    - ls -l
    - docker run --name sast -v /var/run/docker.sock:/var/run/docker.sock -v $(pwd):/src horuszup/horusec-cli:v2.7 horusec start -p /src -P $(pwd) || failure=true
    - if [[ "$(docker logs sast >& container-logs ; cat container-logs | grep 'Vulnerability MEDIUM is. [1-9]\d*'  | wc -l)" -gt 0 ]]; then echo 'Failing job due to identified failures'; exit 1; else echo "no issues found"; exit 0; fi # If issues are found, fail job, if no issues are found pass job

security-test-sca:
  stage: security
  script:
    - echo "Security SCA testing..."
    - docker run --name sca --env SNYK_TOKEN -v $(pwd):/app snyk/snyk:node || failure=true
    - if [[ "$(docker logs sca >& container-logs ; cat container-logs | grep 'found [1-9]\d* issues' | wc -l)" -gt 0 ]]; then echo 'Failing job due to identified failures'; exit 1; else echo "no issues found"; exit 0; fi # If issues are found, fail job, if no issues are found pass job

deploy-job:      # This job runs in the deploy stage.
  stage: deploy  # It only runs when *both* jobs in the test stage complete successfully.
  script:
    - echo "Deploying application..."
    - echo "Application successfully deployed."
- Add an environment variable secrets to the CI/CD pipeline
 Let's examine the YAML piece by piece:
- Add docker, make it available in the runner
image: docker:19.03.12

services:
  - docker:19.03.12-dind
- The
before_scriptdirective runs before any job, so use it to view package version info and install packages
before_script:
  - docker info
  - apk --update add npm
- Create a list of stages in sequential order, such that jobs belonging to the same stage can execute in parallel.
- Each job in a stage has the environment of the stage before.
- If you want to make files available for any next stages to access, then a job should register those files as artifacts
stages:          # List of stages for jobs, and their order of execution
  - build
  - test
  - security
  - deploy
- In the build job, make the
node_modulesfolder an artifact so later stages can access dependencies.
build-job:       # This job runs in the build stage, which runs first.
  stage: build
  script:
    - echo "Compiling the code..."
    - echo "Compile complete."
    - npm install            # This job will run npm install in our example but could be anything
  artifacts:
    paths:
    - node_modules          # Save the node_modules folder so we can use it in the security-test-sca job
- Run basic tests in parallel
unit-test-job:   # This job runs in the test stage.
  stage: test    # It only starts when the job in the build stage completes successfully.
  script:
    - echo "Running unit tests... This will take about 60 seconds."
    #- sleep 60
    - echo "Code coverage is 90%"

lint-test-job:   # This job also runs in the test stage.
  stage: test    # It can run at the same time as unit-test-job (in parallel).
  script:
   - echo "Linting code... This will take about 10 seconds."
    #- sleep 10
   - echo "No lint issues found." #test comment for commit
- Run security tests, fail based on result of docker logs, which you can do via bash:
exit 0: successexit 1: failure
security-test-dast:   # This job runs in the security stage.
  stage: security
  script:
    - echo "Security DAST testing..."
    - docker run -d -p 3000:3000 --name juice-shop bkimminich/juice-shop  # Run juice-shop so we have something to test
    - containerip=$(docker inspect -f "{{ .NetworkSettings.Networks.bridge.IPAddress }}" juice-shop)   # Get container IP so we can test it
    - docker run -t --name dast owasp/zap2docker-stable zap-baseline.py -t http://$containerip:3000 || failure=true  #run DAST testing against juice shop container
    - if [[ "$(docker logs dast >& container-logs ; cat container-logs | grep 'WARN-NEW. [1-9]\d*'  | wc -l)" -gt 0 ]]; then echo 'Failing job due to identified failures'; exit 1; else echo "no issues found"; exit 0; fi  # If issues are found, fail job, if no issues are found pass job

security-test-sast:
  stage: security
  script:
    - echo "Security SAST testing..."
    - ls -l
    - docker run --name sast -v /var/run/docker.sock:/var/run/docker.sock -v $(pwd):/src horuszup/horusec-cli:v2.7 horusec start -p /src -P $(pwd) || failure=true
    - if [[ "$(docker logs sast >& container-logs ; cat container-logs | grep 'Vulnerability MEDIUM is. [1-9]\d*'  | wc -l)" -gt 0 ]]; then echo 'Failing job due to identified failures'; exit 1; else echo "no issues found"; exit 0; fi # If issues are found, fail job, if no issues are found pass job

security-test-sca:
  stage: security
  script:
    - echo "Security SCA testing..."
    - docker run --name sca --env SNYK_TOKEN -v $(pwd):/app snyk/snyk:node || failure=true
    - if [[ "$(docker logs sca >& container-logs ; cat container-logs | grep 'found [1-9]\d* issues' | wc -l)" -gt 0 ]]; then echo 'Failing job due to identified failures'; exit 1; else echo "no issues found"; exit 0; fi # If issues are found, fail job, if no issues are found pass job