intro-devops
Devops foundations
What is DevOps and DevSecOps
In development, you usually have three different teams:
- development: in charge of making the code, testing it, and deploying it.
- security: in charge of making sure the app and code is secure.
- operations: in charge of making sure the app works well and consistently
However, development and operations are at odds with each other, because each of them have different objectives, or in other words, work in completely different silos:
- what dev teams want: to ship the code as fast as possible
- Main goal is speed
- what ops teams want: to make sure the app is stable for all versions
- Main goal is stability

DevOps is the intersection of integrating dev with ops teams to attain both speed and stability. It achieves this through denying the silo model, where each team works independently to do their part of the application:
- dev silo: works independently to make the code
- ops silo: works independently to test the code, implement observability.
This is often illustrated through the wall of confusion, where devs hand their code to ops, and ops is supposed to figure out how to deploy code they've never seen before.

The problem with this silo model is that it takes too long because the dev team finishes their sprint, hands the code to ops, and then waits until ops hands back the code and tells them to fix it.
DevOps fixes the silo model by using tools to integrate development with operations at every turn:
- CI/CD: creates a automated pipeline with tests that ensure if the code passes the pipeline, it gets automatically deployed with version control history and passes quality assurance of tests
- observability tools: developers can implement observability tools in production instances to log important information.
DevSecOps aims to integrate the silo of security into an automated pipeline instead of having a dedicated security team constantly hand back and forth the code with the dev team whenever they find a security vulnerability.
By modifying our code to use these tools, we can integrate each silo together into an automated pipeline that achieves all three core objectives of speed, security, and stability:
- development tools: create a CI/CD pipeline to create automated integrations for security and ops teams.
- security: add static and dynamic vulnerability analysis tools into the automated pipeline.
- operations: add observability and alarms into the pipeline and code.

Now instead of each team working individually, DevSecOps achieves all three teams working together to achieve their objectives in an automated pipeline.
Silos between business and tech
IT people take forever to get something done, but that's just because there's a silo between business and IT.
Core guiding principles
CAMS
The CAMS model in DevOps stands for Culture, Automation, Measurement, and Sharing:
- Culture focuses on changing human behaviors and breaking down silos between teams to foster collaboration.
- Automation speeds up processes and reduces manual work, helping to improve efficiency and quality.
- Measurement involves tracking key metrics to understand system performance and team outcomes.
- Sharing promotes transparency and teamwork through open communication and knowledge exchange.
NOTE
Automation is the accelerator that helps you unlock the other benefits of Devops. Manual work is a source of many efficiency and quality problems in technology value streams so you want to outsource the manual work to automation as your primary approach to creating solutions.
The CAMS model in devops helps us view our purpose as the following values:
- culture: we want to change the behavior of people
- automation: use automation to accelerate change
- measure: we need to measure what we're doing in order to improve.
- sharing: working together builds better services.
The three ways of devops

The Three Ways of DevOps are strategic principles to bring DevOps values to life:
- Systems Thinking and Principles of Flow: Focus on optimizing the entire system's outcome rather than just individual parts, ensuring smooth flow from concept to delivery.
- You have to understand the whole system to optimize it well
- The overall flow from beginning to end is how you actually produce value, not improving one part of the system at the expense of other parts.
- Amplifying Feedback Loops: Create and shorten feedback loops between teams to catch issues early and improve efficiency.
- Effective and fast feeback yields a better and more efficient system.
- Culture of Continuous Experimentation and Learning: Foster a work culture that encourages trying new ideas, learning from them, and continuously improving through practice.
Devops playbook
The five main practice areas of DevOps covered in the video are:
- Culture: Building a stable, safe environment for learning, sharing, experimenting, and collaboration.
- Process: Using agile and lean techniques like small batches, feedback loops, and lightweight change approvals.
- Infrastructure as Code: Managing infrastructure through software practices for reproducibility and rapid scaling.
- Continuous Delivery: Automating testing and deployment to release small changes frequently and reliably.
- Site Reliability Engineering: Engineering systems for reliability with observability and automation.
Shifting left and software dev lifecycle
- Software Development Lifecycle (SDLC): This is the process of planning, creating, testing, and deploying software. In DevOps, SDLC is integrated with continuous practices to make releases faster and more reliable.
- Shifting Left: This means moving tasks like testing and security earlier in the development process instead of waiting until the end. For example, security checks happen during coding and build stages, helping catch issues sooner and reduce delays.
- Value Streams: These represent the flow of work from idea through development to delivery to users. In DevOps, optimizing value streams means removing blockers and improving collaboration so software gets to production faster and with higher quality.
Containers vs VMs
A host device uses a hypervisor to manage multiple virtual machines, where each virtual machine has their own operating system (ring 0) and then the applications that live on top of that (ring 3)

A container differs from a virtual machine by not including an operating system with it. Rather, it uses the container engine's operating system (like Docker Desktop Windows or Mac).
Here are the benefits of this container approach:
- containers are slim: Because a container does not ship an entire OS with it, it takes up much less space than a VM.
- containers boot up quickly: because containers do not use their own OS, they boot up very quickly because they just use the container engine and container host OS to boot up the containers again and again.

Technical Design Documents (TDDs)
TDDs are high-level documentation pieces on how to implement a feature, talking about the purpose, system architecture, data flow, and data structures involved with the feature at a high level.
WHen writing TDDs, you should always start out describing the problem, its scope, and then get into how to solve it and the various different approaches to solving it.
Here are the four components of the TDD you should write in order:
- what problem are we trying to solve
- what is the current process?: optional, only for internal tools.
- what are the requirements?: what circumstances define the problem as being solved.
- how do we solve it?: feature proposal for solving the problem, which correctly achieves the circumstances needed that define the problem as being solved.
Devops Toolchain
- Devops Tools: software that helps accelerate your value delivery
- Devops Toolchain: a combination of devops tools that helps you automate and manage the process of creating and delivering software
Toolchains often integrate these categories of tools together in a consolidated, ordered pipeline process.
- source code management: Github, Bitbucket
- testing: third-party testing tools that scan your code looking for linting errors or runtime errorsa.
- artifact management: tools that store build artifacts.
- security scanning: tools that scan for security vulnerabilities, using SAST, DAST, IAST, etc.
- CI/CD tools: orchestrate tools together, acting as schedulers at the heart of the pipeline, like Jenkins or CircleCI.
- Deployment: complex deployment routines require dedicated tools like Octopus Deploy
- Monitoring: sentry, datadog
- Confirugation management: Getting infrastructure up and running via Ansible.
DevSecOps
There's tension between security and devs because they have opposite goals.
- devs: ship fast, eat cocaine
- security: be super safe, take it slow, ensure high quality
The problem is not that devs don't care about security, it's that they don't know what security wants them to fix. So the secret is automation and shifting security left by using security tools earlier in the development lifecycle.
Kubernetes and Cloud Native
Kubernetes is useful for the following reasons:
- built-in management features: has observability, service discovery, health monitoring, and redundant networking
- abstracts the infra: K8S manages all the infra for you
K8S has become the standard for deploying company infra to the cloud, so much so that they invented a term for this:
Cloud native just means adding and using K8S for your deployment solution. Weird name.
Chaos engineering
Chaos engineering is the discipline of experimenting on a system in order to build confidence in the system's capability to withstand real-world conditions in production.
In order words, you try to simulate breaking shit and see if the system still hods, and then if not, build the system to stand strong against failures and deliberate adversity against your system.
In chaos engineering, we aim to control the chaos that comes with emulating production failures and heavy load with several techniques:
- fault injection: intentionally applying an outage or performance degradation to a live system component.
- game day: a coordinated event where your organization plans to respond to a real or simulated incident to learn and improve from it
MLOps
MLOps, as explained in the course, is the combination of machine learning (ML) and DevOps practices. It focuses on managing not just code and infrastructure, but also the data and machine learning models that are used to find patterns in data.
Unlike traditional DevOps, MLOps involves collaboration between developers, operations teams, and data scientists, because ML workloads are often run by data scientists who may not have deep systems knowledge.
- It automates versioning and management of large data sets and ML models.
- It requires high-performance computing resources, often using GPUs, for training ML models.
- It includes continuous integration and deployment processes for software, infrastructure, and data/models.
- It involves ongoing monitoring and feedback loops to improve model results over time.
AIOps and LLMOps
AIOps is using AI to automate IT operations processes, like automatically drafting emails, ingesting data, using ML systems to flag vulnerabilities, etc.
IaC
IaC basics
- IaC (infrastructure as code): creating declarative code files that describe what resources you want to provision, what VMs to create, etc.
- configuration management: tools intended to help a a fleet of VMs provisioned automatically with IaC get into a desired state, by controlling configuration like delivering software updates to certain VMs, sending commands to them, installing packages, etc.
The benefit of IaC is error-free automated setup and teardown of resources, which saves time and money.
Provisioning vs Configuration Management vs Orchestration
- configuration management: changing control of system configuration during and after initial provisioning.
- Examples are ansible, chef, puppet
- baking: creating a custom image set up to run everything you need for your app on a server, then deploying as a part of immutable deployment.
- provisioning: the process of making a server ready for operation, including hardware, OS, system services, and network connectivity.
- Examples are pulumi and terraform
- orchestration: the act of performing coordinated operations across multiple systems while maintaining uptime by intelligently performing operations on services in such a way to avoid disruption of use while they are running.
configuration management and baking
We use configuration management tools for granularity to individually or batch apply updates to VM(s) in a fleet of VMs provisioned by IaC.
For example, Ansible is a configuration management tool that uses playbook YAML files to declaratively describe the desired state of the environment and automates the process to achieve it.
In DevOps, "configuring" means setting up and managing servers or systems at runtime using tools like Chef, Puppet, or Ansible. These tools adjust the system's settings dynamically when the server is running.
On the other hand, "baking" means creating a custom image (like a virtual server image or a container image) that already has everything set up inside it before deployment. This image is then deployed as-is, which is called immutable deployment.
Baking shifts setup work earlier in the development process, reducing risks during deployment but also making changes in production less flexible. Both approaches can be combined depending on your needs.
- Drift is when your system changes from its intended and defined state.
Declarative vs Imperative
- Declarative: You specify what the desired end state of the system should be, and the tool figures out how to achieve and maintain that state.
- Core benefit: It’s simpler and converges the system over time. Tools like Chef and Puppet use this model.
- Medium: uses stuff like playbooks or YAML files to describe how a deployment or configuration should be performed, and then you just point at the file to execute the change.
- Imperative: You specify how to perform the steps to reach the desired state, giving you full control over the process.
- Core benefit: This approach is more explicit and better for orchestrating complex changes. Tools like Ansible and Shell scripts follow this model.
- Medium: runs CLI commands to imperatively provision infra of configure changes.
Immutable provisioning
Even though IaC became a solved problem, further management of those servers still required configuration management, still creating silos between IaC and configuration management.
With the advent of containers, we now have a way to combine both IaC and configuration management together via adopting an immutable infrastructure approach where we treat our servers like disposable cattle and using immutable provisioning to launch container services that we don't have to perpetually configure.
- immutable infrastructure: an approach to provisioning and deployment of cloud resources where components are replaced rather than individually SSHed into and changed
- Immutable provisioning create deployments that are not intended to change the provisioned resources on updates, but instead delete and recreate and redeploy the entire system if needed.
- immutable deployment: instead of provisioning servers and then configuring your app to run as a service on those servers via configuration management, package your app as a container image, upload it to an image repository, and then servers pull from it to build the images and run them as the main app process.

NOTE
Kubernetes is an approach to solve immutable infra, provisioning, and deployment all at once with one tool.
NOTE
In an immutable provisioning approach, you may still experience drift if you manually change properties on certain cloud resources, but by design, you do not intend to change the infrastructure once it's deployed.
This approach avoids modifying running systems, reducing errors and enabling advanced rollout strategies like blue-green deployments.
Here are the differences between immutable provisioning and configuration management:
- immutable provisioning: changes to cloud resources replaces the cloud resources with new ones, rather than updating them.
- configuration management: a centralized agent pushes changes to update cloud resources.
IaC philosophy
Infrastructure as code is the philosophy of treating the continuous deployment of your infrastructure with software development practices: using your code to deploy the infrastructure and having the state of the infrastructure be dependent on the code.
The main reason why adhering to infrastructure as code is beneficial is because in DevOps culture you should always treat your servers as cattle rather than pets (because you shouldn't handcraft servers and cater to their unique needs).
Instead servers should be standardized and be able to be killed and provisioned without a second thought, which is possible through infrastructure as code.
This approach involves:
- Writing your infrastructure setup and configurations as code that is stored in source control, just like application code.
- Automating the creation, configuration, and deployment of servers and services, making them consistent and repeatable.
- Avoiding manual changes on individual servers; instead, you update the code, test it, and redeploy, similar to fixing bugs in software.
- Adopting a cultural shift where infrastructure is treated as disposable and replaceable ("servers as cattle, not pets"), enabling mass production and easy replacement.
This leads to more reliable systems, less firefighting, and smoother operations, which aligns well with modern DevOps and backend development practices.
CI/CD in IaC
The main purpose of a continuous delivery pipeline for infrastructure as code is to automate the process of taking your infrastructure code from development to production reliably and efficiently. It:
- Isolates changes by building and testing small batches of code, so you know exactly when and where something goes wrong.
- Enables traceability by linking deployments to specific code changes, eliminating manual changes on production servers.
- Ensures your infrastructure is consistent, repeatable, and easier to manage by automating build, test, and deployment steps.
Here is how to effectively use CI/CD in your IaC system:
- Check in your IaC code into version control
- Have unit tests that automatically run via CI pipelines to test your infrastructure before it goes through the CD pipeline.
- In the CD pipeline, deploy your IaC to a cloud provider.
Here are the key components of a CI/CD system for IaC:
- Reproducible infrastructure: Ensuring your infrastructure works the same way across development, testing, and production environments reduces bugs and deployment issues.
- Versioned artifacts: Package and version your code and infrastructure configurations to keep deployments consistent and traceable.
- Identical environments: Strive to make environments as similar as possible to avoid surprises, using tools like Docker or Vagrant to align developer and production setups.
- Deployment as code: Automate deployments using code to increase speed, reduce errors, and enable rollbacks or roll-forwards.
Then using these key components, here are the steps to implement a CI/CD pipeline to deploy your IaC:
- create versioned artifacts: Create versioned artifacts for your code and your infrastructure code.
- create an identical environment: Use that code to make a production-like environment in each phase of the dev cycle.
- deploy each identical environment: Have a mechanism to deploy it in an identical manner in each of those environments.
GitOps
GitOps is a methodology and practice that uses Git repositories as a single source of truth to deliver infrastructure as code.
The four key characteristics of GitOps according to OpenGitOps are:
- Declarative: The system's desired state is expressed declaratively, meaning that it lives somewhere in code like in YAML files.
- Versioned and immutable: The desired state is stored in a way that enforces immutability, versioning, and retains a complete version history.
- Pulled automatically: Software agents automatically pull the desired state declarations from the source repository.
- Continuously reconciled: Software agents continuously observe the actual system state and attempt to apply the desired state.
Policies as code
Policies as code are an approach that is used to define security and compliance rules for infra as code.
Policies as code help prevent risky configurations (like open network ports or missing encryption) before they reach production, using tools such as TFSEC, Chekov, Dry Run Security, and Open Policy Agent.
The main components of a policy as code system are:
- Policy: Contains the set of rules and conditions, such as denying public access to storage buckets or enforcing encryption.
- Data: The input that the policy evaluates, like CloudFormation templates or Terraform configuration files.
- Query: The command or trigger that tells the policy engine to start evaluating the policies against the data.
Configuration management
Vagrant
Vagrant is a HashiCorp tool that simplifies creating and managing developer environments. It bridges the gap between the host machine (your local computer) and the guest machine (the virtual environment) to ensure seamless integration.
By using configuration files called Vagrantfile, Vagrant automates the setup and configuration process, enabling teams to focus on development rather than environment management.
Vagrant offers several advantages over manually configuring your virtual environment:
- Vagrant ensures consistent and reproducible environments, reducing the “it works on my machine" problem and enabling smoother collaboration.
- Vagrant environments are portable and shareable, letting teams replicate setups efficiently across projects and infrastructure.
- Vagrant streamlines interactions with underlying virtualization tools by detecting versions and applying the correct flags. This ensures consistent behavior, even when team members use different versions of the same provider. Vagrant enhances workflows with features like synced folders, automatic networking, and HTTP tunneling, all designed to streamline development.
Vagrant works with providers like VirtualBox, VMware, Docker, and more, giving you the flexibility to tailor environments to your infrastructure and application requirements.
CLI
vagrant up— launches the virtual machines and installs Kubernetes.vagrant status— shows the state of your VMs.vagrant ssh <machine-name>— connects to a specific VM.vagrant halt— pauses/shuts down the VMs.
VagrantFile
Vagrant.configure("2") do |config|
  config.vm.define "control-plane" do |cp|
    cp.vm.box = "ubuntu/bionic64"
    cp.vm.hostname = "control-plane"
    # Additional config like network, synced folders
  end

  config.vm.define "worker-node1" do |node|
    node.vm.box = "ubuntu/bionic64"
    node.vm.hostname = "worker-node1"
  end

  # More nodes as needed
end
CI/CD
Basics
- CI (continuous integration): the practice of automating the integration of code changes from multiple contributors into a single software project while maintaining code quality and app stability.
- CD (continuous delivery): the practice of automating the deployment of code changes made via CI and deploying the app to a staging environment
- After CD, the QA team takes over and stress-tests the app in the staging environment, and then they deploy the app to production
- continuous deployment differs from continuous delivery in that continuous deployment automatically deploys to production, by automatically releasing changes to production after passing tests, enabling multiple deployments per day.

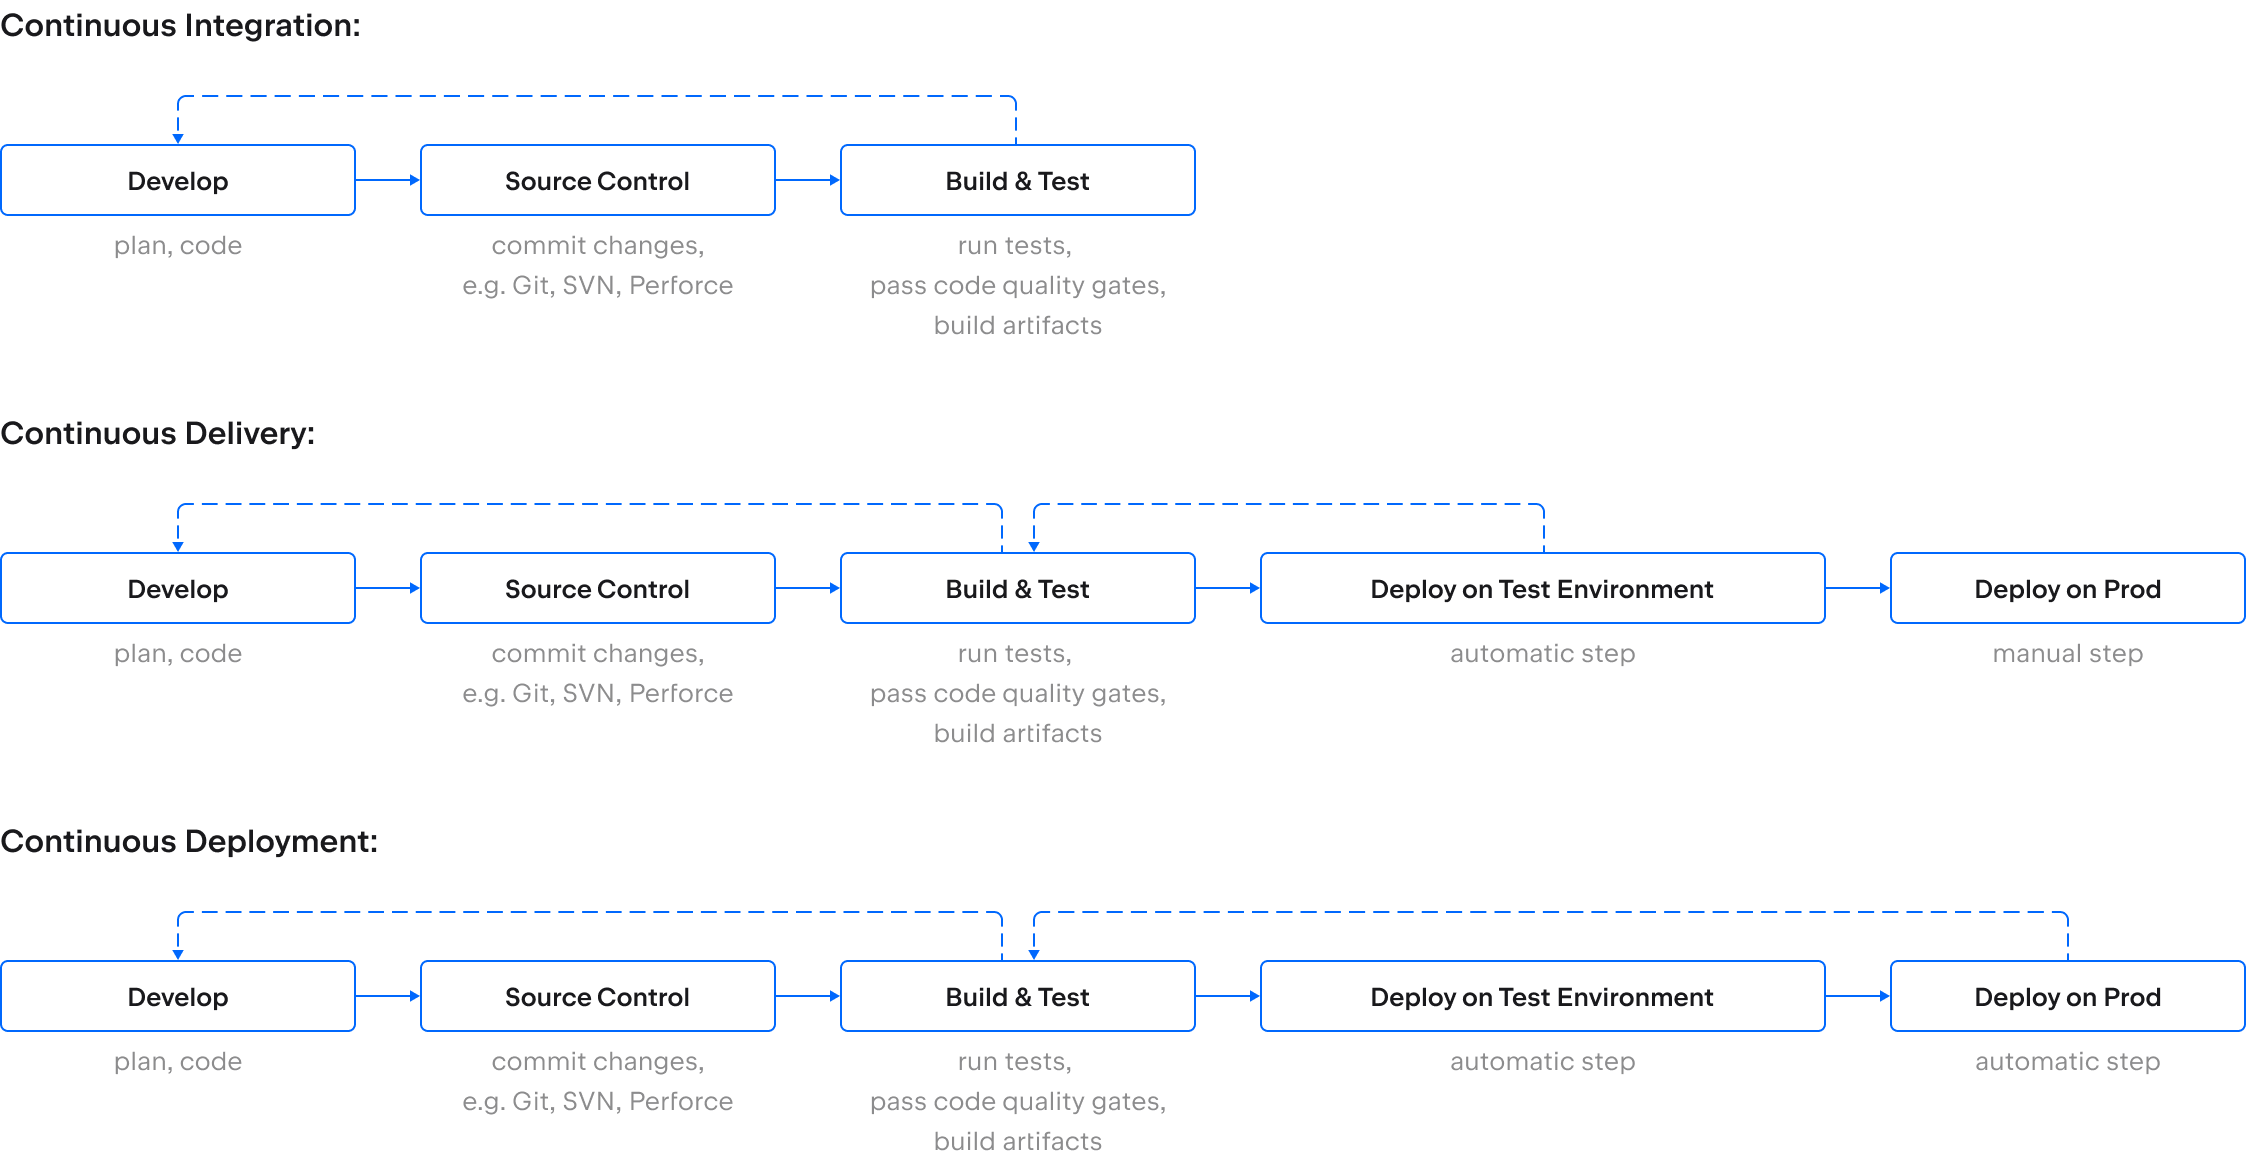
CI
Without CI, developers work for days on separate branches and then merge large changes together, often causing:
- Build failures
- Merge conflicts
- Hidden bugs
- Long debugging sessions
CI encourages small, frequent integrations so problems are found while the changes are still fresh in developers' minds.
NOTE
The biggest benefit is fast feedback. Instead of discovering a bug days or weeks later, CI can tell you within minutes that your change broke something. This dramatically reduces troubleshooting time.
Successful CI requires:
- Version control (Git, SVN, etc.)
- Frequent commits and merges
- Automated builds
- Automated tests
- Fast response to build failures
- Ongoing maintenance of the pipeline and test suite
There are six practices that will help you with continuous integration:
- fast builds: the build should take less time than it takes to get a cup of coffee.
- commit small changes: seek to commit the smallest amount of code per commit, since small commits makes isolating failure points easier and enables easy rollback
- don't leave the build broken: When you leave the build broken, you block delivery
- use a trunk-based dev flow: Devs should frequently merge in dev to make sure they are up to date with the latest changes, which makes merging easier and less likely to cuase a broken build.

- don't allow flaky automated tests: Tests should always be deterministic, never failing for random reasons.
- the build should return a status, log, and artifact: Builds must have appropriate observability, which can be achieved via adding these three components:
- build log: a detailed record of all the tests run and the results of the run.
- artifact: installable dist version of the application, should be tagged with the version number.
Continuous delivery
It's not how much you can deliver, but how little.
- Build artifacts only once: built once, then the artifacts are used across all environments, like staging, prod, test, etc.
- artifacts should be immutable: only the CI system should be able to write the artifact, and only the CD system should have read access to the artifact.
- Deploy to a pre-production environment: A pre-prod environment should have all the same settings and cloud resources as a production environment
- stop deploys if a previous step fails: if any point in the build pipeline fails, then need to fail the entire pipeline to prevent a broken build from making it through to the next stage.
- deploys should be idempotent: deployments should be deterministic, never changing with the same inputs.
NOTE
Why do we use pre-prod environments? It's because it helps us do the acceptance testing, integration tests, smoke testing, and end-to-end testing that is difficult to fully simulate on dev desktops or build servers.
QA
Automated testing is the main driver that enables CI/CD to be valuable.
Any good QA team must add these tests to an application so that the pipeline can have good test coverage in CI:
- unit testing
- code hygeine: uses linters and formatters to ensure there is no tech debt and you are using best practices
- integration testing
- acceptance testing: also known as end to end testing, tests the entire flow of the app as a user would do it.
Continuous deployment
Continuous delivery means your code changes are automatically deployed to a test environment and are always ready to be released, but the actual release to production might still need manual approval.
Continuous deployment takes this further by automatically releasing every change to production as soon as it passes all tests, allowing multiple deployments per day without manual steps.
NOTE
So, continuous deployment is like continuous delivery plus automatic release to production, making the process faster and more automated.
NOTE
To do continuous deployment the best, you should make sure that the way you deploy to testing and to production are as similar as possible.
- Using one mechanism for test and another for production guarantees you will have production issues.
- Deploy to similar environments for the highest likelihood of success.
Continuous deployment implementations need an opinionated system that also satisfies these core qualities:
- safe: changes do not break anything in prod.
- reversible: easy to rollback to different prod versions, no lingering state
- no down time: does not affect users and data in prod.
There are three types of deployment strategies you can do for continuous deployment:
- blue-green deployment: provision infra with the new version of your code and direct the production load balancer to direct traffic towards the infra with the new code.

- canary deployment: provision some infra with the new version of your code and then distribute a small percentage of production traffic to the infra running the new code.

- A/B deployment: feature-based rollout where you use feature flags to decide which groups of users to allow them to use the new feature, and then the rest of the users do not get access to the new feature.

Branching strategies
CI encourages developers to integrate changes frequently instead of waiting weeks or months. The more frequently changes are integrated, the easier it is to:
- Detect bugs
- Avoid merge conflicts
- Release software faster
- Maintain deployment confidence
The challenge is deciding where those integrations happen and which branches should trigger automated testing and deployments.
That's why we need branching strategies.
Put simply, a branching strategy is your team’s agreement on how and when to create and merge branches in version control.
NOTE
How you set up your version control system and use branches will impact how you set up your CI/CD pipeline, so it’s important to choose a model that meets your needs.
A branching strategy is simply an agreement on:
- When to create branches
- When to merge them
- Which branches are used for development
- Which branches are used for releases
Here are the different types of branching strategies:
- trunk-based development: Everyone commits directly to a central branch (often
mainormaster). - feature-based development: Each feature gets its own branch.
- release branches: create dedicated branches for codebases that are candidates to become releases, and then run CI/CD on the release branches.
Overall, here are best practices to keep in mind when working with branching strategies:
- Run builds on feature branches.
- Validate pull requests before merge.
- Keep branches short-lived.
- Use release branches for versioned releases.
- Use hotfix branches for emergencies.
Here's what to avoid:
- Long-running feature branches.
- Waiting weeks before merging.
- Running CI only on the main branch.
- Maintaining many stale branches simultaneously.
The closer you stay to continuous integration, the more value you get from CI/CD. Branches are useful, but they should not prevent frequent integration and automated testing.
Trunk-based development
Trunk-based development is the simplest conceptual approach and a good fit for mature CI/CD environments practicing frequent deployment. It works by having everyone commit directly to a central branch (often main or master).
main
 ├─ Commit A
 ├─ Commit B
 ├─ Commit C
 └─ Deploy
benefits:
- Maximum continuous integration
- Very small merge conflicts
- Fastest path to production
- Simpler branch structure
cons:
- Requires strong automated testing
- Requires disciplined teams
- Risk of unfinished features reaching production unless feature flags are used
Feature branch development
Each feature gets its own branch.
main
 ├─ feature/login
 ├─ feature/reporting
 └─ feature/export
Benefits
- Keeps unfinished work out of production
- Makes experimentation safer
- Easier code reviews
- Cleaner separation of work streams
Drawbacks
- Delays integration
- Larger merge conflicts
- Harder bug resolution
- Reduced benefits of CI if branches live too long
NOTE
This is the main criticism from trunk-based development advocates.
When working with feature branches, it's important to implement these three best practices so feature-based development stays manageable:
- add CI to feature branches: Run CI builds on feature branches, not just main, as this results in an even tighter feedback loop.
- keep branches small: Keep feature branches short-lived (1-2 days if possible).
- merge in often to avoid merge conflicts: Regularly merge or rebase from main to stay current.
Release branches
When a release is approaching:
main
 ├─ Feature A
 ├─ Feature B
 └─ release/7.6

release/7.6
 ├─ Bug Fix 1
 ├─ Bug Fix 2
 └─ Production Release
Once the release branch is created:
- No new features are added.
- Only testing and bug fixes occur.
- New feature development continues elsewhere
Here are the key benefits:
- Stabilizes releases
- Supports versioned products
- Makes long-term maintenance easier
- Works well for Continuous Delivery
However, there is a main tradeoff:
WARNING
Bug fixes made on the release branch must also be merged back into main to avoid losing those fixes in future releases
Release branches are particularly useful when:
- You support multiple product versions.
- Customers don't all upgrade immediately.
- You need maintenance releases.
NOTE
This pattern is common in enterprise software such as the work you're doing around PRISM/TeamCity builds.
Hotfix branch
A hotfix branch is created specifically for urgent production issues.
release/7.6
    │
    └─ hotfix/security-fix
The goal is to:
- Fix the issue quickly.
- Run necessary CI validation.
- Deploy immediately.
- Merge the fix back to the main development stream
Types of CI/CD tools
CI/CD tools fall into four categories: self-hosted, Software as a Service (SaaS), cloud service providers, and code repositories, each with different setup and flexibility levels.
- self-hosted: runs on your hardware or company machines or personal cloud VM.
- Self-hosted tools offer the most control but require more maintenance
- SaaS: vendor provides and maintains the tool, and it runs completely in the cloud.
- SaaS tools are easy to start with
- code repository: stores the repo and CI/CD in one place.
- code repository tools simplify collaboration by combining code and CI/CD management
- cloud service providers: AWS, Azure, etc., where you have cloud integration as well as code pipelines.
- cloud providers integrate well with cloud infrastructure
Choose based on your context: individuals benefit from SaaS or code repository tools, small teams from code repository tools, and enterprises from self-hosted or cloud provider tools.
Self-hosted tools

Jenkins
- Install jenkins
- Setup plugins
- Create a
Makefilefor ease of use for running commands (a level of abstraction on top of running raw bash commands)
FUNCTION=undefined
PLATFORM=undefined
URL=undefined
VERSION=undefined
BUILD_NUMBER=undefined
CODE=$(shell ls *.py)

ifneq (,$(findstring -staging,$(FUNCTION)))
	ENVIRONMENT = STAGING
else ifneq (,$(findstring -production,$(FUNCTION)))
	ENVIRONMENT = PRODUCTION
else
	ENVIRONMENT = undefined
endif

hello:
	@echo "Here are the targets for this Makefile:"
	@echo "  requirements   - install the project requirements"
	@echo "  lint           - run linters on the code"
	@echo "  black          - run black to format the code"
	@echo "  test           - run the tests"
	@echo "  build          - build the lambda.zip file"
	@echo "  deploy         - deploy the lambda.zip file to AWS"
	@echo "  testdeployment - test the deployment"
	@echo "  clean          - remove the lambda.zip file"
	@echo "  all            - clean, lint, black, test, build, and deploy"
	@echo
	@echo
	@echo "You must set the FUNCTION variables to use the deploy target."
	@echo "FUNCTION must be set to the name of an existing lambda function to update."
	@echo "For example:"
	@echo
	@echo "  make deploy FUNCTION=sample-application-staging"
	@echo
	@echo "Optional deploy variables are:"
	@echo "  VERSION       - the version of the code being deployed (default: undefined)"
	@echo "  PLATFORM      - the platform being used for the deployment (default: undefined)"
	@echo "  BUILD_NUMBER  - the build number assigned by the deployment platform (default: undefined)"
	@echo "  URL           - the URL to use for testing the deployment (default: undefined)"
	@echo

requirements:
	pip install -U pip
	pip install --requirement requirements.txt

check:
	set
	zip --version
	python --version
	pylint --version
	flake8 --version
	aws --version

lint:
	pylint --exit-zero --errors-only --disable=C0301 --disable=C0326 --disable=R,C $(CODE)
	flake8 --exit-zero --ignore=E501,E231 $(CODE)


black:
	black --diff $(CODE)

test:
	python -m unittest -v index_test

build:
	zip lambda.zip index.py data.json template.html

deploy:
	aws sts get-caller-identity

	aws lambda wait function-active \
		--function-name="$(FUNCTION)"

	aws lambda update-function-configuration \
		--function-name="$(FUNCTION)" \
		--environment "Variables={PLATFORM=$(PLATFORM),VERSION=$(VERSION),BUILD_NUMBER=$(BUILD_NUMBER),ENVIRONMENT=$(ENVIRONMENT)}"

	aws lambda wait function-updated \
		--function-name="$(FUNCTION)"

	aws lambda update-function-code \
		--function-name="$(FUNCTION)" \
	 	--zip-file=fileb://lambda.zip

	aws lambda wait function-updated \
		--function-name="$(FUNCTION)"

testdeployment:
	curl -s $(URL) | grep $(VERSION)

clean:
	rm -vf lambda.zip

all: clean lint black test build deploy

.PHONY: test build deploy all clean
- Create a pipeline via a
Jenkinsfilein your repo:
pipeline {
    agent any

    environment {
        AWS_ACCESS_KEY_ID         = credentials('AWS_ACCESS_KEY_ID')
        AWS_SECRET_ACCESS_KEY     = credentials('AWS_SECRET_ACCESS_KEY')
        AWS_DEFAULT_REGION        = 'UPDATE_THIS_VALUE'
        STAGING_FUNCTION_NAME     = 'UPDATE_THIS_VALUE'
        STAGING_URL               = 'UPDATE_THIS_VALUE'
        PRODUCTION_FUNCTION_NAME  = 'UPDATE_THIS_VALUE'
        PRODUCTION_URL            = 'UPDATE_THIS_VALUE'
    }

    stages {
        stage('Requirements') {
            steps {
                sh('''
                    #!/bin/bash
                    python3 -m venv local
                    . ./local/bin/activate
                    make requirements
                ''')
            }
        }

        stage('Check') {
            parallel {
                stage('Check:Lint') {
                    steps {
                        sh('''
                            #!/bin/bash
                            . ./local/bin/activate
                            make check lint
                        ''')
                    }
                }

                stage('Check:Test') {
                    steps {
                        sh('''
                            #!/bin/bash
                            . ./local/bin/activate
                            make test
                        ''')
                    }
                }
            }
        }

        stage('Build') {
            steps {
                sh('''
                    #!/bin/bash
                    make build
                ''')
            }
        }

        stage('Deploy Staging') {
            steps {
                sh('''
                    #!/bin/bash
                    make deploy \
                        PLATFORM="Jenkins" \
                        FUNCTION=${STAGING_FUNCTION_NAME} \
                        VERSION=${GIT_COMMIT} \
                        BUILD_NUMBER=${BUILD_NUMBER}
                ''')
            }
        }

        stage('Test Staging') {
            steps {
                sh('''
                    #!/bin/bash
                    make testdeployment URL=${STAGING_URL} VERSION=${GIT_COMMIT}
                ''')
            }
        }

        stage('Deploy Production') {
            steps {
                sh('''
                    #!/bin/bash
                    make deploy \
                        PLATFORM="Jenkins" \
                        FUNCTION=${PRODUCTION_FUNCTION_NAME} \
                        VERSION=${GIT_COMMIT} \
                        BUILD_NUMBER=${BUILD_NUMBER}
                ''')
            }
        }

        stage('Test Production') {
            steps {
                sh('''
                    #!/bin/bash
                    make testdeployment URL=${PRODUCTION_URL} VERSION=${GIT_COMMIT}
                ''')
            }
        }
    }

    post {
        success {
            // Archive the lambda.zip file as an artifact
            archiveArtifacts artifacts: 'lambda.zip', allowEmptyArchive: false
        }
    }
}
Bamboo
Bamboo is a paid atlassian CI/CD product that can be self-hosted, but also has remote agents to run the CI/CD pipelines in the cloud.
Bamboo uses Spec files in YAML to create and run a CI/CD pipeline
Teamcity
Teamcity is a Jetbrains product meant for CI/CD jobs and has tight integrations with Jetbrains IDE and Visual Studio.
The config files for Teamcity can be written in XML or Kotlin.
- Install TeamCity: Begin by installing TeamCity on your server or local machine. TeamCity is a closed-source application but offers a free license with full features for small teams (up to 100 build configurations and 3 build agents).
- Configure Your Project: You can set up your CI/CD pipeline either through the web interface or by importing configuration files.
- Use Configuration Files: TeamCity supports XML and Kotlin for pipeline configuration. XML is structured but verbose, while Kotlin is easier to read and allows for code reuse with templates. The course provides Kotlin-based settings files you can import to quickly set up pipelines.
- Set Up Build Steps: In the web interface, select your build job, then "Edit configuration" and "Build steps" to define each step of your pipeline. Steps can be configured with various runner types; command line runners are common but others are available depending on your technology stack.
- Run Your Pipeline: Start the build from the TeamCity home page. You can monitor the build status in real-time, view logs, and check detailed output for each step.
- Integrate with IDEs: If you use JetBrains IDEs like IntelliJ or PyCharm, TeamCity integrates directly, allowing you to trigger builds and view results without leaving your coding environment.
- Monitor and Maintain: Use the build logs and status summaries to troubleshoot and optimize your CI/CD process.
Here are the general steps to set up a pipeline:
- Create a
Makefileas an abstraction over provisioning commands
FUNCTION=undefined
PLATFORM=undefined
URL=undefined
VERSION=undefined
BUILD_NUMBER=undefined
CODE=$(shell ls *.py)

ifneq (,$(findstring -staging,$(FUNCTION)))
	ENVIRONMENT = STAGING
else ifneq (,$(findstring -production,$(FUNCTION)))
	ENVIRONMENT = PRODUCTION
else
	ENVIRONMENT = undefined
endif

hello:
	@echo "Here are the targets for this Makefile:"
	@echo "  requirements   - install the project requirements"
	@echo "  lint           - run linters on the code"
	@echo "  black          - run black to format the code"
	@echo "  test           - run the tests"
	@echo "  build          - build the lambda.zip file"
	@echo "  deploy         - deploy the lambda.zip file to AWS"
	@echo "  testdeployment - test the deployment"
	@echo "  clean          - remove the lambda.zip file"
	@echo "  all            - clean, lint, black, test, build, and deploy"
	@echo
	@echo
	@echo "You must set the FUNCTION variables to use the deploy target."
	@echo "FUNCTION must be set to the name of an existing lambda function to update."
	@echo "For example:"
	@echo
	@echo "  make deploy FUNCTION=sample-application-staging"
	@echo
	@echo "Optional deploy variables are:"
	@echo "  VERSION       - the version of the code being deployed (default: undefined)"
	@echo "  PLATFORM      - the platform being used for the deployment (default: undefined)"
	@echo "  BUILD_NUMBER  - the build number assigned by the deployment platform (default: undefined)"
	@echo "  URL           - the URL to use for testing the deployment (default: undefined)"
	@echo

requirements:
	pip install -U pip
	pip install --requirement requirements.txt

check:
	set
	zip --version
	python --version
	pylint --version
	flake8 --version
	aws --version

lint:
	pylint --exit-zero --errors-only --disable=C0301 --disable=C0326 --disable=R,C $(CODE)
	flake8 --exit-zero --ignore=E501,E231 $(CODE)


black:
	black --diff $(CODE)

test:
	python -m unittest -v index_test

build:
	zip lambda.zip index.py data.json template.html

deploy:
	aws sts get-caller-identity

	aws lambda wait function-active \
		--function-name="$(FUNCTION)"

	aws lambda update-function-configuration \
		--function-name="$(FUNCTION)" \
		--environment "Variables={PLATFORM=$(PLATFORM),VERSION=$(VERSION),BUILD_NUMBER=$(BUILD_NUMBER),ENVIRONMENT=$(ENVIRONMENT)}"

	aws lambda wait function-updated \
		--function-name="$(FUNCTION)"

	aws lambda update-function-code \
		--function-name="$(FUNCTION)" \
	 	--zip-file=fileb://lambda.zip

	aws lambda wait function-updated \
		--function-name="$(FUNCTION)"

testdeployment:
	curl -s $(URL) | grep $(VERSION)

clean:
	rm -vf lambda.zip

all: clean lint black test build deploy

.PHONY: test build deploy all clean
- Write a
settings.ktsfile that is recognized by TeamCity as the file to use to create a project and set up the pipeline.
import jetbrains.buildServer.configs.kotlin.*
import jetbrains.buildServer.configs.kotlin.buildFeatures.perfmon
import jetbrains.buildServer.configs.kotlin.buildSteps.script
import jetbrains.buildServer.configs.kotlin.projectFeatures.githubIssues
import jetbrains.buildServer.configs.kotlin.triggers.vcs
import jetbrains.buildServer.configs.kotlin.vcs.GitVcsRoot

/*
The settings script is an entry point for defining a TeamCity
project hierarchy. The script should contain a single call to the
project() function with a Project instance or an init function as
an argument.

VcsRoots, BuildTypes, Templates, and subprojects can be
registered inside the project using the vcsRoot(), buildType(),
template(), and subProject() methods respectively.

To debug settings scripts in command-line, run the

    mvnDebug org.jetbrains.teamcity:teamcity-configs-maven-plugin:generate

command and attach your debugger to the port 8000.

To debug in IntelliJ Idea, open the 'Maven Projects' tool window (View
-> Tool Windows -> Maven Projects), find the generate task node
(Plugins -> teamcity-configs -> teamcity-configs:generate), the
'Debug' option is available in the context menu for the task.
*/

version = "2023.05"

project {
    buildType(Build)
    features {
    }
}

object Build : BuildType({
    name = "Build"
    enablePersonalBuilds = false
    artifactRules = "+:lambda.zip"
    maxRunningBuilds = 1
    publishArtifacts = PublishMode.SUCCESSFUL

    // please configure the parameters manually in the TeamCity UI
    // Select Project -> Edit Project -> Build (Under Build Configurations) -> Parameters
    // Edit each parameter with the values for your deployments
    params {
        password("env.AWS_SECRET_ACCESS_KEY", "reference", display = ParameterDisplay.HIDDEN)
        password("env.AWS_ACCESS_KEY_ID", "reference", display = ParameterDisplay.HIDDEN)
        param("env.AWS_DEFAULT_REGION", "UPDATE_THIS_VALUE")
        param("env.STAGING_FUNCTION_NAME", "UPDATE_THIS_VALUE")
        param("env.STAGING_URL", "UPDATE_THIS_VALUE")
        param("env.PRODUCTION_FUNCTION_NAME", "UPDATE_THIS_VALUE")
        param("env.PRODUCTION_URL", "UPDATE_THIS_VALUE")
    }

    steps {
        script {
            name = "Requirements"
            scriptContent = """
                python3 -m venv local
                . ./local/bin/activate
                make requirements
            """.trimIndent()
        }
        script {
            name = "Check"
            scriptContent = """
                . ./local/bin/activate
                make check lint test
            """.trimIndent()
        }
        script {
            name = "Build"
            scriptContent = "make build"
        }
        script {
            name = "Deploy Staging"
            scriptContent = """
                make deploy \
                	PLATFORM="TeamCity" \
                    FUNCTION=${'$'}{STAGING_FUNCTION_NAME} \
                    VERSION=${'$'}{BUILD_VCS_NUMBER} \
                    BUILD_NUMBER=${'$'}{BUILD_NUMBER}
            """.trimIndent()
        }
        script {
            name = "Test Staging"
            scriptContent = "make testdeployment URL=${'$'}{STAGING_URL} VERSION=${'$'}{BUILD_VCS_NUMBER}"
        }
        script {
            name = "Deploy Production"
            scriptContent = """
                make deploy \
                	PLATFORM="TeamCity" \
                    FUNCTION=${'$'}{PRODUCTION_FUNCTION_NAME} \
                    VERSION=${'$'}{BUILD_VCS_NUMBER} \
                    BUILD_NUMBER=${'$'}{BUILD_NUMBER}
            """.trimIndent()
        }
        script {
            name = "Test Production"
            scriptContent = "make testdeployment URL=${'$'}{PRODUCTION_URL} VERSION=${'$'}{BUILD_VCS_NUMBER}"
        }
    }
})
- Manually run the pipeline or upload your code via a commit and push to trigger the pipeline.
SaaS CI/CD

TravisCI
TravisCI reads a travis.yml to create the pipeline
---
# Specify the programming language to be used, in this case, Python.
language: python

# Define the Python version to be used for the build.
python:
  - "3.9"

# Try to speed up builds with caching
cache: pip

# 'install' represents the 'Requirements' stage of the pipeline.
install:
  # Install required Python packages specified in the 'requirements.txt' file.
  - pip install --quiet --upgrade --requirement requirements.txt

  # Install AWS CLI
  - pip install --quiet --upgrade awscli

# Each step in the 'script' represents the remaining stages of the pipeline.
script:
  # Check: Run the 'check', 'lint', and 'test' targets defined in the Makefile.
  - make check lint test

  # Build: Clean previous builds and initiate a new build.
  - make clean build

  # Deploy Staging: Deploy to the staging environment using specified parameters.
  - make deploy FUNCTION=${STAGING_FUNCTION_NAME} PLATFORM="Travis CI" VERSION=${TRAVIS_COMMIT} BUILD_NUMBER=${TRAVIS_BUILD_NUMBER}

  # Test Staging: Perform deployment testing for the staging environment.
  - make testdeployment URL=${STAGING_URL} VERSION=${TRAVIS_COMMIT}

  # Deploy Production: Deploy to the production environment using specified parameters.
  - make deploy FUNCTION=${PRODUCTION_FUNCTION_NAME} PLATFORM="Travis CI" VERSION=${TRAVIS_COMMIT} BUILD_NUMBER=${TRAVIS_BUILD_NUMBER}

  # Test Production: Perform deployment testing for the production environment.
  - make testdeployment URL=${PRODUCTION_URL} VERSION=${TRAVIS_COMMIT}
CircleCI
CircleCI stands out because it supports a wide range of build environments including Ubuntu, Windows, MacOS, and even specialized processors like GPUs and ARM.
- It also caters to mobile development for iOS and Android.
- CircleCI uses Docker containers or virtual machines to run your builds, giving flexibility and consistency.
- Its "orbs" feature allows you to reuse shared configurations easily, saving time.
- Plus, it offers an intuitive command line tool for testing and debugging locally.
Here's how to understand what to do:
- Understand CircleCI's Environment: CircleCI runs your CI/CD workflows using Docker containers or virtual machines, providing access to Ubuntu, Windows, and MacOS environments. It also supports specialized environments like GPUs and ARM processors, and mobile platforms including iOS and Android.
- Set Up Your Project: Begin by linking your code repository (e.g., GitHub, GitLab, Bitbucket) to CircleCI. This integration allows CircleCI to trigger builds automatically when you push code.
- Configure Your Pipeline: Create a
.circlecidirectory in your project root and add aconfig.ymlfile. This YAML file defines all your jobs and workflows, specifying the steps to build, test, and deploy your application. - Use Orbs for Reusable Configurations: CircleCI offers "orbs," which are packaged, shareable configurations that save time by reusing common setup patterns. You can find orbs in the CircleCI registry for various tools and services.
- Run and Monitor Builds: You can start builds by pushing code or manually triggering pipelines via the CircleCI dashboard. Monitor progress in real-time by selecting active steps to view commands and output.
- Analyze Build Trends: Use the Insights page on CircleCI to track average runtimes, success rates, and failure trends over time, helping you optimize your CI/CD process.
- Consider Pricing: CircleCI offers three pricing tiers suitable for individuals, teams, and enterprises. Each tier includes free build minutes monthly, with additional minutes available for purchase. Pricing scales based on concurrent jobs and team size.
CircleCI reads a config.yaml to create a pipeline:
# Use the latest 2.1 version of CircleCI pipeline process engine.
# See: https://circleci.com/docs/configuration-reference
version: 2.1

# Orbs are reusable packages of CircleCI configuration that you may share across projects, enabling you to create encapsulated, parameterized commands, jobs, and executors that can be used across multiple projects.
# See: https://circleci.com/docs/orb-intro/
orbs:
  # The python orb contains a set of prepackaged CircleCI configuration you can use repeatedly in your configuration files
  # Orb commands and jobs help you with common scripting around a language/tool
  # so you dont have to copy and paste it everywhere.
  # See the orb documentation here: https://circleci.com/developer/orbs/orb/circleci/python
  python: circleci/python@1.5.0

# Define a job to be invoked later in a workflow.
# See: https://circleci.com/docs/configuration-reference/#jobs
jobs:
  integration: # This is the name of the job
    # These next lines defines a Docker executors: https://circleci.com/docs/executor-types/
    # You can specify an image from Dockerhub or use one of the convenience images from CircleCI's Developer Hub
    # A list of available CircleCI Docker convenience images are available here: https://circleci.com/developer/images/image/cimg/python
    # The executor is the environment in which the steps below will be executed - below will use a python 3.10.2 container
    # Change the version below to your required version of python
    docker:
      - image: cimg/python:3.10.2
    # Checkout the code as the first step. This is a dedicated CircleCI step.
    # The python orb's install-packages step will install the dependencies from a Pipfile via Pipenv by default.
    # Here we're making sure we use just use the system-wide pip. By default it uses the project root's requirements.txt.
    # Then run your tests!
    # CircleCI will report the results back to your VCS provider.
    steps:
      - checkout
      # This step takes care of the requirements
      - python/install-packages:
          pkg-manager: pip
      - run:
          name: install aws CLI
          command: pip install --quiet --upgrade awscli
      - run:
          name: check
          command: make check lint test

  build: # New job for build
    docker:
      - image: cimg/python:3.10.2
    steps:
      - checkout
      - run:
          name: install aws cli
          command: pip install --quiet --upgrade awscli
      - run:
          name: build
          command: make clean build
      - persist_to_workspace: # Persist the lambda.zip to workspace
          root: .
          paths:
            - lambda.zip

  deploy-test-staging:
    docker:
      - image: cimg/python:3.10.2
    steps:
      - checkout
      - attach_workspace: # Attach workspace to get the lambda.zip
          at: .
      - run:
          name: install aws cli
          command: pip install --quiet --upgrade awscli
      - run:
          name: deploy
          command: make deploy FUNCTION=${STAGING_FUNCTION_NAME} PLATFORM="CircleCI" VERSION=${CIRCLE_SHA1} BUILD_NUMBER=${CIRCLE_BUILD_NUM}
      - run:
          name: test
          command: make testdeployment URL=${STAGING_URL} VERSION=${CIRCLE_SHA1}

  deploy-test-production:
    docker:
      - image: cimg/python:3.10.2
    steps:
      - checkout
      - attach_workspace: # Attach workspace to get the lambda.zip
          at: .
      - run:
          name: install aws cli
          command: pip install --quiet --upgrade awscli
      - run:
          name: deploy
          command: make deploy FUNCTION=${PRODUCTION_FUNCTION_NAME} PLATFORM="CircleCI" VERSION=${CIRCLE_SHA1} BUILD_NUMBER=${CIRCLE_BUILD_NUM}
      - run:
          name: test
          command: make testdeployment URL=${PRODUCTION_URL} VERSION=${CIRCLE_SHA1}

# Invoke jobs via workflows
# See: https://circleci.com/docs/configuration-reference/#workflows
workflows:
  experimental-pipeline:
    jobs:
      - integration
      - build:
          requires:
            - integration
      - deploy-test-staging:
          requires:
            - build
      - deploy-test-production:
          requires:
            - deploy-test-staging
Cloud CI/CD

Code repos

Gitlab
- Create a
Makefileas an abstraction over bash commands:
FUNCTION=undefined
PLATFORM=undefined
URL=undefined
VERSION=undefined
BUILD_NUMBER=undefined
CODE=$(shell ls *.py)

ifneq (,$(findstring -staging,$(FUNCTION)))
	ENVIRONMENT = STAGING
else ifneq (,$(findstring -production,$(FUNCTION)))
	ENVIRONMENT = PRODUCTION
else
	ENVIRONMENT = undefined
endif

hello:
	@echo "Here are the targets for this Makefile:"
	@echo "  requirements   - install the project requirements"
	@echo "  lint           - run linters on the code"
	@echo "  black          - run black to format the code"
	@echo "  test           - run the tests"
	@echo "  build          - build the lambda.zip file"
	@echo "  deploy         - deploy the lambda.zip file to AWS"
	@echo "  testdeployment - test the deployment"
	@echo "  clean          - remove the lambda.zip file"
	@echo "  all            - clean, lint, black, test, build, and deploy"
	@echo
	@echo
	@echo "You must set the FUNCTION variables to use the deploy target."
	@echo "FUNCTION must be set to the name of an existing lambda function to update."
	@echo "For example:"
	@echo
	@echo "  make deploy FUNCTION=sample-application-staging"
	@echo
	@echo "Optional deploy variables are:"
	@echo "  VERSION       - the version of the code being deployed (default: undefined)"
	@echo "  PLATFORM      - the platform being used for the deployment (default: undefined)"
	@echo "  BUILD_NUMBER  - the build number assigned by the deployment platform (default: undefined)"
	@echo "  URL           - the URL to use for testing the deployment (default: undefined)"
	@echo

requirements:
	pip install -U pip
	pip install --requirement requirements.txt

check:
	set
	zip --version
	python --version
	pylint --version
	flake8 --version
	aws --version

lint:
	pylint --exit-zero --errors-only --disable=C0301 --disable=C0326 --disable=R,C $(CODE)
	flake8 --exit-zero --ignore=E501,E231 $(CODE)


black:
	black --diff $(CODE)

test:
	python -m unittest -v index_test

build:
	zip lambda.zip index.py data.json template.html

deploy:
	aws sts get-caller-identity

	aws lambda wait function-active \
		--function-name="$(FUNCTION)"

	aws lambda update-function-configuration \
		--function-name="$(FUNCTION)" \
		--environment "Variables={PLATFORM=$(PLATFORM),VERSION=$(VERSION),BUILD_NUMBER=$(BUILD_NUMBER),ENVIRONMENT=$(ENVIRONMENT)}"

	aws lambda wait function-updated \
		--function-name="$(FUNCTION)"

	aws lambda update-function-code \
		--function-name="$(FUNCTION)" \
	 	--zip-file=fileb://lambda.zip

	aws lambda wait function-updated \
		--function-name="$(FUNCTION)"

testdeployment:
	curl -s $(URL) | grep $(VERSION)

clean:
	rm -vf lambda.zip

all: clean lint black test build deploy

.PHONY: test build deploy all clean
- Create a
github-ci.yamlfile for the pipeline
# Use the Python 3.11 image as the base image for this pipeline.
image: python:3.11

# Define the stages of the pipeline in the order they should run.
stages:
  - requirements
  - check
  - test
  - build
  - staging
  - production

# The requirements job sets up the Python virtual environment and installs necessary dependencies.
Requirements:
  stage: requirements
  # Cache the virtual environment to speed up subsequent jobs.
  cache:
    key: venv
    paths:
      - venv
  script:
    - python -m venv venv
    - venv/bin/pip install --upgrade --requirement requirements.txt
    - make requirements

# The check job performs static code analysis and linting.
Check:
  stage: check
  needs: ["Requirements"]
  cache:
    policy: pull
    key: venv
    paths:
      - venv
  # Setup necessary utilities for the job.
  before_script:
    - apt-get update -y
    - apt-get install -qq zip
  script:
    - source venv/bin/activate
    - make check
    - make lint

# The test job runs the project's tests.
Test:
  stage: test
  needs: ["Check"]
  cache:
    policy: pull
    key: venv
    paths:
      - venv
  script:
    - source venv/bin/activate
    - make test

# The build job creates the deployable artifact.
Build:
  stage: build
  needs: ["Test"]
  before_script:
    - apt-get update -y
    - apt-get install -qq zip
  script:
    - make build
  # Store the lambda.zip as an artifact to be used in subsequent stages.
  artifacts:
    paths:
      - ./lambda.zip

# The staging job deploys the code to the staging environment.
Staging:
  stage: staging
  environment: Staging
  needs: ["Build"]
  # Define environment variables for AWS and the function name.
  variables:
    AWS_DEFAULT_REGION: $AWS_DEFAULT_REGION
    AWS_ACCESS_KEY_ID: $AWS_ACCESS_KEY_ID
    AWS_SECRET_ACCESS_KEY: $AWS_SECRET_ACCESS_KEY
    FUNCTION: $FUNCTION_NAME
  cache:
    policy: pull
    key: venv
    paths:
      - venv
  script:
    - source venv/bin/activate
    - make deploy PLATFORM="GitLab CI" FUNCTION=$FUNCTION VERSION=$CI_COMMIT_SHA BUILD_NUMBER=$CI_PIPELINE_ID
    # Test the deployed code in the staging environment.
    - make testdeployment URL=$CI_ENVIRONMENT_URL VERSION=$CI_COMMIT_SHA
  dependencies:
    - Build

# The production job deploys the code to the production environment.
Production:
  stage: production
  environment: Production
  needs: ["Build", "Staging"]
  variables:
    AWS_DEFAULT_REGION: $AWS_DEFAULT_REGION
    AWS_ACCESS_KEY_ID: $AWS_ACCESS_KEY_ID
    AWS_SECRET_ACCESS_KEY: $AWS_SECRET_ACCESS_KEY
    FUNCTION: $FUNCTION_NAME
  cache:
    policy: pull
    key: venv
    paths:
      - venv
  script:
    - source venv/bin/activate
    - make deploy PLATFORM="GitLab CI" FUNCTION=$FUNCTION VERSION=$CI_COMMIT_SHA BUILD_NUMBER=$CI_PIPELINE_ID
    # Test the deployed code in the production environment.
    - make testdeployment URL=$CI_ENVIRONMENT_URL VERSION=$CI_COMMIT_SHA
  dependencies:
    - Build
BitBucket
- Create a
Makefileas an abstraction over bash commands:
FUNCTION=undefined
PLATFORM=undefined
URL=undefined
VERSION=undefined
BUILD_NUMBER=undefined
CODE=$(shell ls *.py)

ifneq (,$(findstring -staging,$(FUNCTION)))
	ENVIRONMENT = STAGING
else ifneq (,$(findstring -production,$(FUNCTION)))
	ENVIRONMENT = PRODUCTION
else
	ENVIRONMENT = undefined
endif

hello:
	@echo "Here are the targets for this Makefile:"
	@echo "  requirements   - install the project requirements"
	@echo "  lint           - run linters on the code"
	@echo "  black          - run black to format the code"
	@echo "  test           - run the tests"
	@echo "  build          - build the lambda.zip file"
	@echo "  deploy         - deploy the lambda.zip file to AWS"
	@echo "  testdeployment - test the deployment"
	@echo "  clean          - remove the lambda.zip file"
	@echo "  all            - clean, lint, black, test, build, and deploy"
	@echo
	@echo
	@echo "You must set the FUNCTION variables to use the deploy target."
	@echo "FUNCTION must be set to the name of an existing lambda function to update."
	@echo "For example:"
	@echo
	@echo "  make deploy FUNCTION=sample-application-staging"
	@echo
	@echo "Optional deploy variables are:"
	@echo "  VERSION       - the version of the code being deployed (default: undefined)"
	@echo "  PLATFORM      - the platform being used for the deployment (default: undefined)"
	@echo "  BUILD_NUMBER  - the build number assigned by the deployment platform (default: undefined)"
	@echo "  URL           - the URL to use for testing the deployment (default: undefined)"
	@echo

requirements:
	pip install -U pip
	pip install --requirement requirements.txt

check:
	set
	zip --version
	python --version
	pylint --version
	flake8 --version
	aws --version

lint:
	pylint --exit-zero --errors-only --disable=C0301 --disable=C0326 --disable=R,C $(CODE)
	flake8 --exit-zero --ignore=E501,E231 $(CODE)


black:
	black --diff $(CODE)

test:
	python -m unittest -v index_test

build:
	zip lambda.zip index.py data.json template.html

deploy:
	aws sts get-caller-identity

	aws lambda wait function-active \
		--function-name="$(FUNCTION)"

	aws lambda update-function-configuration \
		--function-name="$(FUNCTION)" \
		--environment "Variables={PLATFORM=$(PLATFORM),VERSION=$(VERSION),BUILD_NUMBER=$(BUILD_NUMBER),ENVIRONMENT=$(ENVIRONMENT)}"

	aws lambda wait function-updated \
		--function-name="$(FUNCTION)"

	aws lambda update-function-code \
		--function-name="$(FUNCTION)" \
	 	--zip-file=fileb://lambda.zip

	aws lambda wait function-updated \
		--function-name="$(FUNCTION)"

testdeployment:
	curl -s $(URL) | grep $(VERSION)

clean:
	rm -vf lambda.zip

all: clean lint black test build deploy

.PHONY: test build deploy all clean
- Create a
bitbucket-pipeline.ymlfile for the pipeline
# Use the latest version of Python
image: python

pipelines:
  default:
    # Step 1: Prepare the environment by installing all necessary dependencies.
    - step:
        name: Requirements
        caches:
          - pip
        script:
          - make requirements

    # Step 2: In parallel, conduct code checks and run tests to validate the code quality and functionality.
    - parallel:
        # Sub-Step 1: Perform code checks and linting to ensure code quality.
        - step:
            name: Check
            caches:
              - pip
            script:
              - apt-get update -y
              - apt-get install -qq zip
              - make requirements
              - make check
              - make lint

        # Sub-Step 2: Execute tests to confirm that the code works as expected.
        - step:
            name: Test
            caches:
              - pip
            script:
              - make requirements
              - make test

    # Step 3: Build the application and generate a ZIP artifact for deployment.
    - step:
        name: Build
        script:
          - apt-get update -y
          - apt-get install -qq zip
          - make build
        artifacts:
          - lambda.zip

    # Step 4: Deploy the application to the staging environment and validate the deployment.
    - step:
        name: Staging
        deployment: staging
        caches:
          - pip
        script:
          - make requirements
          - make deploy PLATFORM="Bitbucket Pipelines" \
            FUNCTION=$STAGING_FUNCTION_NAME \
            VERSION=$BITBUCKET_COMMIT \
            BUILD_NUMBER=$BITBUCKET_BUILD_NUMBER
          - make testdeployment URL=$STAGING_URL VERSION=$BITBUCKET_COMMIT

    # Step 5: If staging is successful, deploy the application to the production environment and validate the deployment.
    - step:
        name: Production
        deployment: production
        caches:
          - pip
        script:
          - make requirements
          - make deploy PLATFORM="Bitbucket Pipelines" \
            FUNCTION=$PRODUCTION_FUNCTION_NAME \
            VERSION=$BITBUCKET_COMMIT \
            BUILD_NUMBER=$BITBUCKET_BUILD_NUMBER
          - make testdeployment URL=$PRODUCTION_URL VERSION=$BITBUCKET_COMMIT
Artifact repositories
An artifact repository is a centralized storage system for your build outputs—like compiled applications, packages, and dependencies. It acts like a library where you keep tested and versioned software components.
Using one ensures that what you test is exactly what gets deployed, improving reliability and security.
- It also helps track versions, manage access, and makes it easier to roll back to previous versions if needed.
- This is key in continuous integration and delivery pipelines to maintain consistency and control over your software releases.
Observability and monitoring
Intro
Observability
Of a system's non-functional requirements (see [[03-system-design#Requirements]]), availability, reliability, and performance all contribute to the overall stability of a software system.
We can determine the stability level of a system by viewing the state of a system through output measurements called signals, which include metrics, logs, and traces.
This is called observability:
Observability is the possibility of observing the state of a system through output measurements.

Observability is a measure of how well the internal states of a system can be inferred from knowledge of its external output.
- high observability: you can tell with high likelihood the state of your system by viewing the metrics, traces, and logs your application outputs.
- low observability: you have a low likelihood at any time of knowing the stability of your system.
NOTE
Therefore we get good observability when by looking at the logs and metrics of our system, we can tell what is going on.
There are four pillars of observability:
- metrics: numeric values that provide insights into the characteristics of a system
- like how CPU usage or memory usage give insight into the performance of an app
- logs: text records that get outputted from either infra or apps, lets devs know what is going on and leaves and audit trail.
- traces: show the lifecycle of a request as it passes through services and infra, show the entire path of a request and how it flows throughout a distributed service
- events: events are emitted when something of note happens or changes within your infrastructure.
Metrics, traces, and logs make up the telemetry signals that offer observability into a system's stability:
- Metrics: These are numeric aggregates that offer a high-level overview of a system’s health and performance. Metrics help track overall trends but may not provide detailed insights into specific issues since they represent data in aggregate form.
- Logs: Logs are discrete events that provide detailed information about what happened in the system at specific times. They include contextual information and exact error messages, which are crucial for troubleshooting and understanding specific events.
- Traces: Traces track the flow of requests or operations through a system, allowing for visualization of the entire journey of a request (or other units of work). They help understand the interactions between different parts of a system and can reveal performance bottlenecks and other issues.

There are 5 areas of observability:
- synthetic checks: health checks that are automated to check if servers and services are running.
- system and application metrics: measuring time series, numerical data like CPU usage or function execution
- end user performance:
- application performance monitoring (APM): Instrumentation framework that reports performance at code level how long every function took to run and duration of database queries and I/O calls.
- real user monitoring (RUM): frontend script and analytics system like Posthog to monitor how users click on your site and what actions they take, and performance in the case of Lighthouse.
- tracing: tracing a service across complex system and the path of a request to see how long it took
- system and application logs: logs should answer these 4 questions:
- what happened
- when did it happen
- where did it happen
- what was involved
- security: uses existing logs and metrics but queries them to detect threats. Audits certain paths on endpoints, bad IP requester addresses, and suspicious or unusual behavior.
Monitoring
Monitoring uses signals to paint a picture of what is happening within the services we track, either by using dashboards, visualizations, or alerting.
There are two main types of monitoring:
- application-performance monitoring: monitoring backend performance
- frontend monitoring: monitoring frontend performance
Observability vs monitoring
- observability: uncovers both known and unknown problems
- monitoring: extracting info targeting known problems

Here are the use cases between monitoring and observability:
- monitoring: intended purpose is to alert quickly of something of note happening
- observability: intended purpose is to understand why something is happening and the underlying cause.

Observability solutions
An observability solution has three main components:
- collector: a way to collect the telemetry signals
- exporter: a way to transmit the collected data to a backend
- server: a server that processes data and visualizes it

OpenTelemetry is an open source solution that provides the collector and exporter components and leaves the backend to the choice of the user, like Prometheus or Grafana.
Observability architecture
The observability architecture models how companies usually implement observability.

- instrumentation/configuration: writing your code in such a way that it can create or export observability signals like metrics, logs, traces, or events
- collection and processing: an agent or system that collects all observability signals and processes them
- export: export the collected signals to a database or backend
- visualization: view the signals and processed and aggregated data via dashboards.
There are two types of architecture:
- vendor-based observability: using third-party vendors in each stage of the pipeline

- open-source observability: using open-source, self-hosted vendors in each stage of the pipeline
NOTE
The main tradeoff here is that vendor-based observability is quick and easy, but costly, while open source observability is free, but difficult to maintain as your architecture grows.
OpenTelemetry
Open Telemetry is an open source observability framework that provides teams with standardized protocols and tools for collecting and routing telemetry data.
The main innovation here is that it replaces the need to use custom or different venders in each stage of the observability architecture, and instead OTel makes use of libraries that help with gathering, processing, and exporting data:
- OTel instrumentation: language-specific libraries and SDKs that help with gathering, processing, and exporting data.
- OTel collector: open source collector that receives data, processes it, and exports it to different backends. Many vendors support this and collect data with OTel collector.
- OTel exporter: sends data to the third-party vendor or backend
- Otel extensions: OpenTelemetry (OTel) extensions are optional components that you can add to the OpenTelemetry collector to enhance its capabilities without needing to create a separate version of the collector.
- Extensions provide additional features like security, health monitoring, or other custom functionalities to improve how the collector operates.

OTel changes the observability architecture by replacing third-party paid vendors with the OTel collector:

Instrumentation
Instrumentation is the act of adding observability code to an app yourself to enable measurement capabilities within a system, which you have three different methods of doing it:
- zero-code: Adds API & SDK capabilities as agent or agent-link installation.
- out-of-the-box instrumentation, like how Deno turns on OpenTelemetry with a single feature flag.
- libraries: import a library as an adapter to make another logging library OTel-compatible, somewhere between zero-code and code-based.
- code-based: manually add code for instrumentation
Of zero-code instrumentation, there are three methods for implementing it:
Observability fundamentals
Events
Events are anything that is deemed important for business, security, or troubleshooting reasons and can range from user actions, system errors, configuration changes, security breaches, network traffic, performance metrics, to software updates and service statuses.
NOTE
Events validate that an expected action happened.
Some common examples of events include:
- Completing a batch processing job.
- Triggering scheduled tasks or cron jobs.
- Changes in user permissions or roles.
- Receiving an incoming HTTP request.
- Database transactions like creating, updating, or deleting records.
- Executing a function.
- Registering or authenticating a user.
- Initiating or terminating a background process.
- Writing data to a file.
- Making an HTTP request to some API.
Every event carries its own set of contextual information. For instance, a database query may include details like the query statement, the execution time, the transaction that initiated the query, and the number of affected rows.
Events are divided into metrics, logs, and traces.
Metrics
Intro
This is what makes for good metrics. They have these properties:
- understandable: perfectly clear and give insight into a characteristic of a specific system
- actionable: alerts your team and drives change
- improvable: able to be improved upon after action
- multidimensional: adds tags to your metrics for more info, like which stage the environment is in.
Here are the benefits of metrics:
- easy to generate alerts: Metrics offer a more efficient means of generating alerts compared to logs because querying a time-series database is typically much faster than querying log data.
- help in performance auditing: They are also instrumental in performance optimization and tuning. By tracking response times, throughput, and resource utilization, you can identify bottlenecks and inefficiencies within your systems, helping you make informed decisions about where to allocate resources for maximum impact.
- tracks business value: Another critical use case for metrics is in business intelligence and decision-making. Numbers related to user engagement, feature usage, and transaction volumes offer valuable insights into customer behavior and preferences.
- help in incident response: Finally, metrics are fundamental in incident response and post-mortem analysis. When an incident occurs, metrics can help in quickly identifying the scope and impact. After resolving the issue, a detailed analysis of the relevant metrics can reveal the root cause and inform strategies to prevent future occurrences.
Metric types

- counters: simple increment-only metrics that keep track of the number of occurrences of a specific event or activity
- examples: API requests, error occurrences, system restarts
- use case 1: when you want to record a value that goes up
- use case 2: when you want to be able to query how fast the value is increasing
- gauges: metrics that provide a snapshot of a particular value at a specific point in time, as numeric time-series data that can fluctuate
- examples: CPU utilization, memory, number of database connections
- histograms: measure the distribution and frequency of time durations for specific events, and then group those numeric values into categorical buckets
- example: classifying a continuous numeric value like request duration into a bucket like fast or slow
Each of the metrics has a purpose:
- counters: used for capacity planning, so you can track load and traffic through counting API requests, error occurences, etc. happen, and then plan for what you recorded.
- gauges: used for performance optimization
- histograms: used for end users to understand the metrics better
Metric aggregation
- sums: summing metrics is useful when you want to track the total count or quantity of events over a period.
- rates: rates are useful when you want to measure how something changes over time.
- mean: averages are useful for finding the central tendency of data, but hide outliers.
- example: you can find the average response time to calculate the typical performance of your website.
- percentile: used to understand the distribution of data and to identify outliers
- example: for example the 90th percentile of response times can help you understand what 90% of your users experience.
Averages and percentiles


- If P50 = 1ms, it means that the other 50% of the requests took longer than 1ms to complete
- If P90 = 2ms, it means that 90% of requests took less than 2ms to complete, while the other 10% of the requests took longer than 2ms to complete
We also use percentile notation for histograms:
- For in P percentile, as increases, the value shifts to the right to make the CDF larger.

Cardinality
High-cardinality data, like email addresses or transaction IDs, are typically avoided in metrics due to their vast and unpredictable range but low-cardinality data such as Boolean values, response time buckets are much more manageable.
Reliability metrics
The reliability of a system concerns how error-free and error-resilient it is, therefore the core reliability metrics that we want to track in an observability solution are as follows:
- MTTD (Mean time to detect): the average time it takes to detect an error
- MTTR (Mean time to repair): the average time it takes for your dev team to repair an error after detection
- MTBF (Mean time between failures): the average time it takes before the error gets thrown again or fails again
- MTTF (Mean time to failure): the sum of MTTD, MTTR, and MTBF, basically the timespan between the first detection and second detection of an error
NOTE
If you have just a monitoring solution, it reduces MTTD drastically, but if you have a full observability solution, it reduces MTTD, MTTR and MTBF because observability gives you the details of the underlying cause of the error, letting the error get fixed faster.
Because observability lets you improve on all these metrics, it leads to a more reliable thus stable system.
Google's four golden signals
Google's four golden signals are a good foundation for defining which metrics you should track in your application.
- errors: rate of unsuccessful events or requests within a service or infra
- throughput/traffic: How much volume of requests or events being received by a service or infra
- latency: the amount of time taken for a request or event to be completed
- saturation: the measure of how a service or infrastructure's limited resources are utilized, like CPU utilization
NOTE
If all of these 4 golden signals look good, then your system is probably working as expected.

Metric collection
In a real-world application, you need software that performs metric collection, like Prometheus or Open Telemetry.
Metric collection has two possible methods:
- push method: pushing the metrics to a server endpoint that you host on your app.
- pull method: your application hosts an endpoint that provides APIs for the time series database to read the metrics. Then a tool like Prometheus will scrape the metrics from that endpoint.
pull method
NOTE
Use Cases: Ideal for environments with static endpoints or where components are known for consistent uptime.
Advantages:
- Controlled Data Collection: The monitoring system (like Prometheus) actively requests metrics from targets, which ensures data consistency and control over polling intervals.
- Dynamic Targeting: It easily adapts to changes in the infrastructure. When new services are added, the monitoring system can automatically scrape them if configured correctly.
- Simpler Error Handling: In case of a communication problem, the pull method typically allows the monitoring system to detect issues directly.
Cons:
- Overhead: The polling mechanism may generate extra network traffic and may lead to overhead if the scraping happens too frequently.
- Complexity with Disparate Services: When dealing with numerous instances or IoT devices in varying locations, setting up scraping can get complex.
Push method
Advantages:
- Immediate Metric Availability: Services can send their metrics in real-time, making them available as soon as they are generated.
- Ease of Use for Short-lived Services: Particularly useful for ephemeral applications like microservices, where instances may come and go rapidly.
Cons:
- Lack of Control: There's less control over how often metrics are sent, potentially leading to data overload or gaps if a service fails to push metrics.
- Temporary Storage Requirement: Requires a push gateway for managing the pushed metrics, which adds another component that needs maintenance.
NOTE
Use Cases: Best suited for scenarios where applications are short-lived or when real-time monitoring is crucial.
Logs
logs should answer these 4 questions:
- what happened
- when did it happen
- where did it happen
- what was involved

Here are the different log level semantics you should stick to:

NOTE
In production, we only filter to listen to log levels of INFO and above to cut out debug noise.
Applications generate a variety of logs, each serving a distinct purpose, including but not limited to:
- Debug logs: Designed specifically for troubleshooting, these logs provide extensive detail to facilitate quick resolution of issues. Given their voluminous nature, debug logs are typically generated in limited scenarios, such as during a debugging session, rather than continuously, to avoid overwhelming storage and processing capacities.
- Error logs: These logs document the occurrence of unexpected errors within the application's operations. They capture critical information about the error condition, such as the type of error, the location within the application where it occurred, and a timestamp. This helps in diagnosing issues and preventing future occurrences.
- Audit logs: These logs track and record sequential actions or events, offering a transparent trail of activities including user actions, system changes, or data access, making them invaluable for compliance and security.
- Application logs: These are records of significant events at the application level, encompassing business transactions, state changes, and other events critical to the business logic of the application. They're pivotal for understanding the application's behavior in the context of business operations.
- Security logs: Focused on security-related events, these logs are essential for detecting, understanding, and responding to security incidents. They record login attempts, access control activities, and any other actions that could affect the application's security posture.
Log benefits
- quicker troubleshooting: One of the primary benefits of logs is their role in troubleshooting and debugging. When something goes wrong, logs provide the historical context needed to understand the sequence of events leading up to an issue which effectively decreases the Mean Time To Acknowledgement (MTTA), a crucial metric for evaluating incident response efficiency.
- shortens time to detect an issue: Essentially, by shortening the time to detect an issue, log data allows responders to start addressing the problem sooner, which ultimately minimizes application downtime and reduces the incident's impact on end-users.
- security and compliance: Security and compliance is another area where logs play a critical role. By recording all attempts to access the system, successful or otherwise, these logs can help identify patterns of malicious activity, unauthorized access attempts, and potential vulnerabilities within the system.
- ux audit: Logging is also commonly used to gain insights into user behavior, application performance, and usage patterns. This information is invaluable for strategic decisions, such as where to allocate resources for development, how to improve user experience, and which features or services are most valued by users.
Log limitations
- logging storage: The impact of logging on system performance can also not be overlooked. Detailed logging can significantly consume resources, affecting application efficiency. Balancing the need for detailed logs while maintaining system efficiency requires careful tuning and consideration.
- security leaks: Another challenge is ensuring the security and privacy of log data. Since logs often contain sensitive information, they must be transmitted and stored securely to ensure private data isn't leaked to the outside world.
Traces
Traces track the complete journey of a request through a system, so we can visualize it and see what went wrong.

Within tracing, there are two important objects to keep track of:
- trace: complete journey of a single request, tagged with a unique trace ID that follows the request everywhere it goes. Here are the components:
- Trace ID
- Span IDs
- Timestamps: store start and end time of the trace
- Attributes
- span: a single operation within a trace which cannot be decomposed any further. Each service handling the request creates one or more spans.
- Span ID
- Parent Span ID: store spawning span
- Attributes (key-value pair context)
- Timestamps: store start and end time of the span

Here is how we identify traces and spans:
- how to identify traces: with a unique trace ID for the request
- how to identify spans: store the spawning span parent ID and a unique ID for the current span.
Debugging with the three signals
The three signals of metrics, logs, and traces in observability should be tracked for any application.
Here is how they work in tandem to help you debug an error
- Metrics alert you
- Traces show you where an error happened
- Logs explain why the error occurred
Here is what happens if you skimp out on any one of these signals:
- skipping metrics: you will never be alerted of the error.
- skipping traces: without traces it will be considerably harder for us to understand which specific component caused the failure in the system.
- skipping logs: without logs it will be considerably harder to understand the exact reason why the error occurred in that specific component.
metrics with logs
Metrics are particularly useful for pinpointing performance bottlenecks within an application's subsystems by tracking latency and throughput, which logs, given their detailed and context-rich nature, might struggle to do efficiently.
Once a potential issue is identified through metrics, logs can then provide the detailed context needed to drill down into specific problematic requests or events.
This illustrates the complementary roles of logs and metrics: metrics offer a high-level overview with limited context, ideal for monitoring and performance analysis across broad system components, while logs provide deep, contextual details for thorough investigation of specific events.
SLI, SLO, SLA
SLIs (service level indicators) are metrics that are particularly relevant to the UX a client experiences, where if you improve upon SLI metrics, that has a direct cause to improve the UX of a customer.

NOTE
Service Level Indicators (SLIs) are metrics that reflect the performance and reliability of a service from the user's perspective.
It's essential for SLIs to represent the entire experience of the user because:
- User-Centric Focus: SLIs must be user-facing, meaning they should reflect metrics that the user directly interacts with or is affected by. This ensures that the indicators provide a relevant context for the user's experience.
- Comprehensive Insights: When SLIs encompass the complete user experience, they allow teams to identify and understand issues that might impact user satisfaction. If SLIs focus only on specific technical metrics (like CPU usage), they can provide a misleading picture of service performance, potentially overlooking what matters most to users.
- Measurability: SLIs should be objective and quantifiable, enabling teams to set clear benchmarks and improve service quality based on user feedback. A good SLI can help organizations understand whether they are meeting their user experience goals and how improvements can be made.
A SLO is a business target value for an SLI, basically a promise you make about service quality and the benchmark you want to hit for your key SLIs.

An SLA is a contractual agreement with your customers to maintain specific SLI benchmarks throughout the year, like 99.999% availability.
NOTE
SLAs should always be less than SLOs because SLOs are the ideal benchmark you want to hit while SLAs are the minimum you can guarantee and commit to.
NOTE
Each additional notch in an SLO requires exponentially more effort to achieve, so choose your SLOs and SLAs wisely and consider the trade-offs between implementing those improvements to hit those SLAs and just maintaining the status quo.

Error budget
The error budget is how much you can afford to fail based on your SLO.
You can consider it as the difference between 100% success for an SLI and the SLO success percentage you set for that SLI.
NOTE
Based on the time your error budget allocates for you, you can use that time in experimentation and to push risky features faster.

OpenTelemetry
Fundamentals
Opentelemetry application development has these components:
- signals: the collection of metrics, logs, and traces
- context: the environmental context answering "when?", "where?", and "what?" for the circumstances surrounding the signals being collected.
- When did this event occur?
- Where did this event occur?
- What triggered this event?
- semantic conventions: Standardized naming and attribute keys (e.g.,
service.name) that ensure telemetry data is consistent and can be correlated across different systems and vendors

APIs and SDKs are what we use to implement instrumentation.
The OpenTelemetry API and SDK serve different roles in building observability into your application:
- The API (Application Programming Interface): Acts as the standardized, language-agnostic interface (0:06:28). It defines the methods and structures for generating telemetry data (traces, logs, and metrics) within your application code. A key feature of the API is that it is "safe" to include in your code—if OpenTelemetry is not installed or configured, calls to the API will simply do nothing rather than causing errors or system overhead. This allows developers to instrument shared libraries or modules without forcing their users to use OpenTelemetry.
- The SDK (Software Development Kit): Acts as the implementation layer that communicates with the API (0:07:13). While the API defines how you write telemetry, the SDK contains the actual logic required for capturing, processing, and exporting that data to your observability backend (0:07:15 - 0:07:28).
There are two types of instrumentation that OTel allows you to do:
- Automatic Instrumentation: Uses libraries that detect popular frameworks (like Express, HTTP, or AWS SDK) and automatically add monitoring code without you writing manual logic
- Instrumentation Libraries are pre-built modules that allow OTel to hook into your existing dependencies (e.g., Bunion, Pino, Winston for logging) to convert their output into the standardized OTel format.
- Manual Instrumentation: Adding code explicitly to your application to capture custom events. You can do OTel instrumentation via the OpenTelemetry APIs and SDKs.
Zero-code instrumentation
There are three zero-code instrumentation
OTel Collector
The OpenTelemetry Collector offers a vendor-agnostic implementation of how to receive, process and export telemetry data. It removes the need to run, operate, and maintain multiple agents/collectors. This works with improved scalability and supports open source observability data formats (e.g. Jaeger, Prometheus, Fluent Bit, etc.) sending to one or more open source or commercial backends.
- Usability: Reasonable default configuration, supports popular protocols, runs and collects out of the box.
- Performance: Highly stable and performant under varying loads and configurations.
- Observability: An exemplar of an observable service.
- Extensibility: Customizable without touching the core code.
- Unification: Single codebase, deployable as an agent or collector with support for traces, metrics, and logs.
Prometheus
Intro
Prometheus is a time-series database designed for storing and querying metrics. Unlike push-based systems, Prometheus uses a pull model: it scrapes metrics from target endpoints at regular intervals.
NOTE
Prometheus is a key tool in the observability landscape focused on collecting and storing metrics—numerical data that represent the performance and health of your system.
It fits alongside other observability tools that handle logs, traces, and events to give you a comprehensive view of your application.
To implement Prometheus in your server app for observability:
- Instrument your app: Add code (using client libraries like the Prometheus client for Node.js) to expose metrics such as request counts, latencies, or custom events.
- Expose a metrics endpoint: Create an HTTP endpoint (commonly
/metrics) where Prometheus can pull from and scrape these metrics. - Set up a collector: Use tools like the OpenTelemetry collector configured with a Prometheus receiver to gather metrics from your app.
- Export and visualize: Send the collected metrics to a backend like Grafana Cloud to analyze and visualize them.
Prometheus architecture
Prometheus is under the hood a time-series database designed for storing metrics, where each time series entry is identified by a metric name and labels.
- metric: a unique metric bucket
- labels: a key-value pair

You can query individual metrics in the Prometheus database via labels or other query expressions using the PromQL query language.
NOTE
The goal is to choose your labels wisely so your buckets don't have too many or too little metrics.

Prometheus can't handle extremely large throughput, so instead it focuses on a pull-based model, where Prometheus routinely pulls data from exporters like Kinesis or SQL.
An exporter is the Prometheus-compatible interface you can implement on any data source to allow Prometheus to scrape data from that data source.
- scrape destination: Every exporter must implement the same interface to make their data available in a Prometheus-compatible format on the
/metricsendpoint of their node exporter process - scrape interval: The default is that every 15 seconds, Prometheus pulls data from data sources with exporters and stores that data in Prometheus.
For applications that want to push their own custom metrics to Prometheus instead of pushing them to an intermediary data source with an exporter, those apps can instead push metric, value, and time entries to a push gateway (temporary data store), which has a built-in exporter Prometheus can scrape from.

Prometheus ports
Prometheus requires special ports to be active on the Prometheus instance and other components:
- 9090: the port with the Prometheus UI
- 9091: the pull-based scraper process
- 9100: the port that exporters should be running on
Installation
Mac Homebrew installation
- Install with brew
brew install prometheus
- Create the prometheus YAML config file
touch /usr/local/etc/prometheus.yml
global:
  scrape_interval: 15s # how often do you want it to scrape

scrape_configs: # tells which targets it should monitor.
  - job_name: "prometheus" # There could be multiple jobs
    static_configs:
      - targets: ["localhost:9090"] # By default it will scrape localhost:9090/metrics but this can be overridden
- Stop the prometheus service
brew stop service prometheus
- Start prometheus by pointing at the config file:
prometheus --config.file=/usr/local/etc/prometheus.yml
Linux installation
- Set up the prometheus service
[Unit]
Description=Prometheus
Documentation=https://prometheus.io/docs/introduction/overview/
Wants=network-online.target
After=network-online.target

[Service]
Type=simple
User=prometheus
Group=prometheus
ExecReload=/bin/kill -HUP $MAINPID
ExecStart=/usr/local/bin/prometheus \
  --config.file=/etc/prometheus/prometheus.yml \
  --storage.tsdb.path=/var/lib/prometheus \
  --web.console.templates=/etc/prometheus/consoles \
  --web.console.libraries=/etc/prometheus/console_libraries \
  --web.listen-address=0.0.0.0:9090 \
  --web.external-url=

SyslogIdentifier=prometheus
Restart=always

[Install]
WantedBy=multi-user.target
EOF
Exporters
- node exporter: an official Prometheus exporter for collecting metrics that are exposed by Linux-based kernels.
- Metric examples: CPU, disk, memory, Network I/O
Creating a node exporter
- Create an EC2 instance with Ubuntu AMI, install Prometheus on it
- Create an EC2 instance with Ubuntu AMI
- Expose these ports on the security group
- 22: for SSHing into the node exporter instance
- 9100: the port prometheus uses to connect to a node exporter, set this source to the security group ID of the prometheus instance to only allow prometheus to send traffic to this node exporter instance on port 9100.

- SSH into the node exporter instance
- Install the node exporter software onto the node exporter instance, which you can do manually by following this guide or by using homebrew for linux, which starts the node exporter service on port 9100.
brew install node_exporter
brew services start node_exporter
- Update the prometheus YAML (stored at
/usr/local/etc/prometheus.yml)
global:
  scrape_interval: 15s
scrape_configs:
  # let prometheus scrape itself, at localhost:9090/metrics
  - job_name: "prometheus"
    static_configs:
      - targets: ["localhost:9090"]

  # for an ec2 instance node exporter
  - job_name: 'node_exporter_ec2_instance'
    static_configs:
	  - targets: ['172.31.29.28:9100']

  # for a local node exporter
  - job_name: 'node_exporter_local_instance'
    static_configs:
	  - targets: ['localhost:9100']
prometheus.yaml
The prometheus.yaml file provides configuration for prometheus settings:
global: global settingsscrape_configs: the list of exporter targets and the configuration for how to target them.
global:
  scrape_interval: 15s
scrape_configs:
  # let prometheus scrape itself, at localhost:9090/metrics
  - job_name: "prometheus"
    static_configs:
      - targets: ["localhost:9090"]

  # for an ec2 instance node exporter
  - job_name: 'node_exporter_ec2_instance'
    static_configs:
	  - targets: ['172.31.29.28:9100']

  # for a local node exporter
  - job_name: 'node_exporter_local_instance'
    static_configs:
	  - targets: ['localhost:9100']
Exporters
Adding jobs under the scrape_configs block lets you register different exporter targets for scraping.
global:
  scrape_interval: 15s
scrape_configs:
  # let prometheus scrape itself, at localhost:9090/metrics
  - job_name: "prometheus"
    static_configs:
      - targets: ["localhost:9090"]

  # for an ec2 instance node exporter
  - job_name: 'node_exporter_ec2_instance'
    static_configs:
	  - targets: ['172.31.29.28:9100']

  # for a local node exporter
  - job_name: 'node_exporter_local_instance'
    static_configs:
	  - targets: ['localhost:9100']
Each job has two components:
- job name: the name of the job, which names the exporter target in the Prometheus UI and uniquely identifies the exporter.
- configuration: configuration for how to actually connect to the exporter is under the
static_configsblocktargets: the list of processes to target.
NOTE
Prometheus will target the /metrics endpoint on all of the target process for scraping metrics data.
Here are examples of exporters you can target:
- cloud node exporter: target a cloud instance running a node exporter service on port 9100
- local node exporter: run a local node exporter instace running a node exporter service on port 9100
TIP
You can go to http://localhost:9100/metrics if running a local node exporter to view all the metrics being outputted by your machine.
PromQL
Primitive data types
The only primitive data types in prometheus are strings and floats.
- querying by strings: you can query by exact string match or regex matching:

- querying by numbers: You can query by exact numeric value
Instant and Range vectors
You then have instant vectors and range vectors:
- instant vectors: return one sampled entry
- range vectors: return multiple entries at once
Instant vectors allow the selection of a set of time series, and from that returns only a single sample value for each at a given timestamp. Basically, with instant vectors, here are the rules:
- you only query by metric name
- You can further filter down by providing labels
- Only one result is returned per query

Maybe this will make it more clear:

A range vector represents a set of instant vectors over a specified period of time.
- It produces a series of data points that shows how the metric values have changed over that time range.
- For instance, when querying a metric over the last 5 minutes, the range vector captures multiple instant vectors for that duration and provides a history of values.


graphing vectors
You can also choose to instant vectors as a graph:

IMPORTANT
One important thing to note is that graphing only works for instant vectors, not range vectors.
in summary
There are two key differences between instant vectors and range vectors:
- Timeframe: Instant vectors capture metric values at a single point in time, while range vectors capture metric values over a period of time.
- Usage: Instant vectors are typically used when you want real-time values or snapshots, whereas range vectors are useful for understanding trends and patterns over time.
Querying
Basic querying is done by labels, which are key-value pairs:

You have these operators for querying on labels:
=for exact match!=: for not equals=~: for regex matching on string values, where for the specified label, the value must match the regex expression (on the right)
Operators
arithmetic operators
You have binary arithmetic operators, where you can apply mathematical operations from scalars onto vectors:
- scalars with vectors: broadcast arithmetic, scalar operation applies to every value of instant vector.
- vectors with vectors: length-based matching, only vectors of same dimensionality can be multiplied with.


binary operators
A boolean in Prometheus is 1 for true and 0 for false.

When performed on scalars, all the binary operators return a boolean value of 1 or 0:

When performing boolean operations on vectors, this conditionally filters entries in a vector, making the resultant vector smaller and filtered.
There are two possible ways you can do this filtering:
- scalar on vector: filters entries on a vector based on a boolean operator with a scalar.
- vector on vector: filters entries on a vector based on comparison with another vector.

set binary operators
Set binary operators are boolean keyword operators that can only be applied to instant vectors and basically perform set operations:
and: performs set intersection (commutative)or: performs set union (commutative)unless: performs set difference (not commutative)

Time offsets
You can get instant vectors offset by time, like finding metrics from 10 minutes ago, using the offset keyword.
Here's the syntax:
<Instant vector> offset <timespan>
This returns a new instant vector.
aggregation operators and functions
Aggregation operators aggregate the elements of a single instant vector, which results in a new instant vector with aggregated values.
Here is the basic syntax for using aggregation operators:
<aggregation operator>(<instant vector>)

# filter by label
<aggregation operator>(<instant vector>) by (<label list>)

# exclude by label
<aggregation operator>(<instant vector>) without (<label list>)
You have these aggregation operators:
sum: returns sum of all entries in the vectormin: returns the minimum of all entries in the vectormax: returns the maximum of all entries in the vectoravg: returns the average of all entries in the vectorstddev: returns the standard deviation of all entries in the vectorstdvar: returns the variance of all entries in the vectorcount: returns the number of entries in the vectorgroup: groups entries together, the value by entry key is 1 for all entries.count_values: counts the number of elements with the same valuestopk: returns the largest entries by value from the vectorbottomk: returns the smallest entries by value from the vector

The by and without keywords are used for groupby operations before running aggregation:
- (level 1) average with
by: here we group entries by unique values of thecodelabel, then average over those buckets:

- (level 2) average with
byand time offset: Here we first perform the time offset to get an instant vector, then we group entries by unique values of thecodelabel, then average over those buckets:

range vector variants
You also have the range vector variants for all of these aggregation operators:

Vector functions
Here are the basic vector functions:
absent(<instant_vector>): returns an instance vector with the key being the metric-label-value combination you queried by and the value being a boolean, true if not found and false if exists.

absent_over_time(<range_vector>): returns an instance vector with the key being the range vector you queried by and the value being a boolean, true if not found and false if exists.

abs(<instant_vector>): applies absolute value to all entries of the vectorlog2(<instant_vector>): applies log2 to all entries of the vectorlog10(<instant_vector>): applies log10 to all entries of the vectorln(<instant_vector>): applies ln to all entries of the vectorceil(<instant_vector>): applies ceiling function to all entries of the vectorfloor(<instant_vector>): applies floor function to all entries of the vector
Then you have these transformation/mapping vector functions:
sort(<instant_vector>): returns the vector in ascending order of valuessort_desc(<instant_vector>): returns the vector in descending order of valuestimestamp(<instant_vector>): for each entry, returns the timestamp of when it was recorded.
You also have these clamping functions which filter instant vectors:
clamp(<instant_vector>, min, max): includes only the values in an instant vector that are within the specified rangeclamp_min(<instant_vector>, min): includes only the values in an instant vector that are above the specified minimum bound.clamp_max(<instant_vector>, max): includes only the values in an instant vector that are below the specified maximum bound.

You also have the delta and idelta functions for getting differences between range vectors over a period of time:

delta(<range_vector>): This function calculates the difference between the first and last values of an instantaneous vector over a specified time range.- use case: It is essential for gauge metrics that can go up and down.
- Example: If you want to find the change in CPU temperature over the last two hours, you would use:
delta(nodes_cpu_temp[2h])
idelta(<range_vector>): Similar todelta, butideltaspecifically looks at the change in the last and first samples, treating them as if they are counters that only increase.- use case: Use this when you want to eliminate negative changes, which is ideal for counters that only increment.
- Example: If you want to analyze the rate of requests to a service where the value only increases, such as in a web server metrics, you might write:
idelta(http_requests_total[5m])
NOTE
delta can show both increases and decreases, while idelta only captures increases (treating it as if negative deltas don’t exist).
NodeJS with Prometheus
Basic push gateway setup
- import the prometheus client library
const client = require("prom-client");
- create a registry and collect default metrics: This sets up default Node.js metrics like memory and CPU usage.
const register = new client.Registry();
client.collectDefaultMetrics({ register });
- define a custom counter metric: This counter will track how many times products are viewed, labeled by product ID.
const productViews = new client.Counter({
  name: "product_views_total",
  help: "Count of product views",
  labelNames: ["productId"],
});
register.registerMetric(productViews);
- create a
/metricsendpoint: This endpoint exposes the metrics for Prometheus to scrape.
const express = require("express");
const app = express();

app.get("/metrics", async (req, res) => {
  res.set("Content-Type", register.contentType);
  res.end(await register.metrics());
});
NOTE
Prometheus does not receive pushed data. That's why we need to create a /metrics endpoint so Prometheus can scrape that endpoint for metrics.
Now whenever one of our observable metrics change, like how we manually increment the counter in the product view handler, the following sequence of events will happen:
- Prometheus gets notified of the metric change
- Now whenever prometheus scrapes the
/metricsendpoint, theregister.metrics()method is returning the freshest, newest metrics values.
app.get("/product/:id", (req, res) => {
  const productId = req.params.id;
  productViews.labels(productId).inc();
  res.send(`Product ${productId} viewed`);
});
Here's the complete app:
const client = require("prom-client");

const register = new client.Registry();
client.collectDefaultMetrics({ register });

const productViews = new client.Counter({
  name: "product_views_total",
  help: "Count of product views",
  labelNames: ["productId"],
});
register.registerMetric(productViews);

const express = require("express");
const app = express();

app.get("/metrics", async (req, res) => {
  res.set("Content-Type", register.contentType);
  res.end(await register.metrics());
});

app.get("/product/:id", (req, res) => {
  const productId = req.params.id;
  productViews.labels(productId).inc();
  res.send(`Product ${productId} viewed`);
});

app.listen(3000);
Grafana
Grafana Installation
ubuntu installation
If you want to install Grafana on an Ubuntu machine, follow these instructions:
Or just run this script:
sudo update
sudo apt-get install -y adduser libfontconfig1 musl
wget https://dl.grafana.com/oss/release/grafana_10.2.2_amd64.deb
sudo dpkg -i grafana_10.2.2_amd64.deb

sudo systemctl daemon-reload
sudo systemctl enable grafana-server
sudo systemctl start grafana-server
sudo systemctl status grafana-server
Amazon Linux installation
sudo yum install -y https://dl.grafana.com/oss/release/grafana-10.2.2-1.x86_64.rpm

sudo systemctl enable grafana-server
sudo systemctl start grafana-server
sudo systemctl status grafana-server
Homebrew installation
- Install grafana via brew
brew install grafana
- Create a copy of the grafana configuration file and then you can edit it to your liking.
cd /usr/local/etc/grafana
cp grafana.ini custom.ini
- Restart the grafana service
brew services info grafana
brew service restart grafana
Docker installation
Grafana custom configuration
The grafana.ini is the source of truth for configuration of the grafana service on Linux systems, and has these top level keys:
[server]: configuration for the server process that runs grafanahttp_port: the port to run on. The default is 3000.
[database]: configuration for the database to use for data storage. The default is a local sqlite instance.[paths]: the default directories for where to store grafana data and logs, which you can override
Then after modifying the grafana configuration, you need to restart that service:
sudo systemctl restart grafana-server
# or
brew services restart grafana
Grafana Cloud
Observability app
Observability answers three questions, and we have different tools to solve those questions:
| Question | Signal | Tool |
|---|---|---|
| Is my system healthy? | Metrics | Prometheus |
| What happened during a request? | Traces | OpenTelemetry |
| What exactly was logged? | Logs | Winston, filelog receiver |
Here are examples of what signals we should measure for each question:
- metrics: "How many times was product 123 viewed?"
- traces: "What services participated in the request? And how long did each take?"
- logs: "What was the exact error?"
Observability architectures
There are three common approaches to implementing observability in your app:
- prometheus to grafana: save metrics to a
/metricsendpoint on your server, let Prometheus scrape those metrics and then send them to Grafana for visualization.- pro: simple and easy
- con: tracks metrics only, no traces, logs are separate
Application
    │
    ▼
/metrics endpoint
    │
    ▼
Prometheus
    │
    ▼
Grafana
- approach 2 - direct to grafana: Application exports directly to grafana cloud via API
- pro: simple
- con: harder to manage
Application
    │
    ▼
Grafana Cloud
- approach 3 - use Otel collector: use the OTel collector to collect metrics, traces, and logs, and then send them to grafana cloud.
App
 │
 ├── Metrics
 ├── Traces
 └── Logs
      │
      ▼
OTel Collector
      │
      ▼
Grafana Cloud
Prometheus + Grafana in Docker
Site Reliability Engineering
Reliability Engineering
SRE is having good engineering practices and designing systems that can tolerate failure through code.
- Reliability is the ability of a system to perform its intended function correctly and consistently when it is expected to.
- resilience: the ability of a system to maintain or regain a stable state and continue operations after a major incident occurred
- SRE is the discipline of using a software engineering approach to automate operation processes
Most of SRE comes down to dealing with integration points
- integration points: An integration point is a single point that connects many services together. It is the number one cause of issues in an architecture.
- cascading failure: occurs based on an issue with an integration point
All systems fail
All systems eventually fail because changes introduce new modes of failure.
What we're aiming for is not the perfect system, but a system with high resilience:
- redundancy: running multiple instance copies of cloud resources for failover
- automatic scaling and load balancing
Circuit breaker
The circuit breaker is a system design concept that is a mitigation against failing systems, where if it detects high frequency of errors, it stops making requests to those failing systems instead of continuing to bombard them with requests

Configuration
Runtime config that varies by deployment should be separated out from the app code and stored into env vars
Incident response
Three activities of incident response management:
- troubleshooting: understanding the system enough to know how to fix
- automation: having the tooling to already speed up and conduct remediation activities
- communication: communicating to end users and stakeholds what went wrong and how you fixed it.
NOTE
If someone makes a mistake and your system goes down, then your system was bad in the first place. Everybody makes mistakes. As an engineer your job is to make the system work anyway.
Postmortems
Here are the core principles behind the mindset you should have when conducting a postmortem:
- There is no root cause: everything happens as a degradation over time.
- Postmortems should be blameles
- Use transparent communication when communicating outages.
Jenkins
Intro
Self-hosted jenkins consists of two components, both of which should be separate servers:
- master server: controls pipelines, schedules builds, and orchestrates minions
- agents/minions: checkout the VCS code and runs the build
- permanent agents: dedicated server instances you own for running jobs. These should have the relevant build tools installed, as well as java.
- cloud agents: ephemeral/dynamic agents spun up on demand, like a Docker image Jenkin spins up to provision a build agent.
There are two types of build configurations:
- freestyle build: the simplest method to create a build which feels like shell scripting.
- pipelines: use the groovy syntax to break up a build into several stages and then run those stages as per the pipeline.
Installation and setup
Docker installation
- Pull the docker image
docker pull jenkins/jenkins
- Create a bridge network in Docker using the following
docker network createcommand:
docker network create jenkins
- Run this command
docker run --name jenkins-docker --rm --detach \
  --privileged --network jenkins --network-alias docker \
  --env DOCKER_TLS_CERTDIR=/certs \
  --volume jenkins-docker-certs:/certs/client \
  --volume jenkins-data:/var/jenkins_home \
  --publish 2376:2376 \
  docker:dind --storage-driver overlay2
- Create a docker image to customize the jenkins image you pulled
FROM jenkins/jenkins:2.580.1-jdk21
USER root
RUN apt-get update && apt-get install -y lsb-release ca-certificates curl && \
    install -m 0755 -d /etc/apt/keyrings && \
    curl -fsSL https://download.docker.com/linux/debian/gpg -o /etc/apt/keyrings/docker.asc && \
    chmod a+r /etc/apt/keyrings/docker.asc && \
    echo "deb [arch=$(dpkg --print-architecture) signed-by=/etc/apt/keyrings/docker.asc] \
    https://download.docker.com/linux/debian $(. /etc/os-release && echo \"$VERSION_CODENAME\") stable" \
    | tee /etc/apt/sources.list.d/docker.list > /dev/null && \
    apt-get update && apt-get install -y docker-ce-cli && \
    apt-get clean && rm -rf /var/lib/apt/lists/*
USER jenkins
RUN jenkins-plugin-cli --plugins "docker-workflow json-path-api"
- Build an image from this Dockerfile
docker build -t myjenkins:2.580.1-1 .
- Run the container
docker run \
  --name jenkins \
  --restart=on-failure \
  --detach \
  --network jenkins \
  --env DOCKER_HOST=tcp://docker:2376 \
  --env DOCKER_CERT_PATH=/certs/client \
  --env DOCKER_TLS_VERIFY=1 \
  --publish 8080:8080 \
  --publish 50000:50000 \
  --volume jenkins-data:/var/jenkins_home \
  --volume jenkins-docker-certs:/certs/client:ro \
  myjenkins:2.580.1-1
- When prompted for the password, run this command to get the password from the running container
docker exec <container-id> cat /var/jenkins_home/secrets/initialAdminPassword
Locally hosted jenkins
Within a locally hosted jenkins instance on Linux, you can explore the filesystem by sshing into the k8s jenkin pod or docker container.
All Jenkins-related data is stored in /var/jenkins_home:
/var/jenkins_home/secrets/initialAdminPassword: stores the initial admin password when logging into Jenkins for the first time./var/jenkins_home/workspace: the folder that contains all jobs, where each job is a folder.
WARNING
When creating a job in jenkins, make sure to never include spaces in the name, because the job name corresponds to the folder name within the /var/jenkins_home/workspace directory.
First job (freestyle build)
Setting up VCS
You can clone down a git repo easily in Jenkins, and you only have to authenticate with git if trying to clone a private repo.
To authenticate with git for the purpose of cloning a private repo, follow these steps:
- Select git in source code management, and then click to add a new credential

- Select authenticate with github app

Now go to Github app creation to create a new github application.
- fill out fields: The only fields you need to fill out (currently) are:
- Github App name - i.e.
Jenkins - <team name> - Homepage URL - your company domain or a github repository
- Webhook URL - your jenkins instance, i.e.
https://<jenkins-host>/github-webhook/, if using local jenkins instance, make sure to use tunneling via ngrok to get an HTTPS url. - redirect URI: optional, do not set.
- Github App name - i.e.


-
Then you need to fill out the permissions
- Commit statuses - Read and Write
- Contents: Read-only (to read the
Jenkinsfileand the repository content duringgit fetch). You may need "Read & write" to update the repository such as tagging releases - Metadata: Read-only
- Pull requests: Read-only
-
subscribe to all events: fill out all the checkboxes to subscribe to all events

- create the github app: click on the button to finally create the app.
- generate a private key: to actually install the app, you must generate a private key

- convert the key into a different format jenkins can use: run this command on the downloaded key:
openssl pkcs8 -topk8 -inform PEM -outform PEM -in key-in-your-downloads-folder.pem -out converted-github-app.pem -nocrypt
Now once you have this private key secret generated and converted into a Jenkins compatible format, you can finish up the github app connection in the Jenkins UI by filling out this info:
- app ID: copy and paste the github app ID from the application settings

- key: fill in the key by copying the contents of the converted private key.

Build triggers
There are 5 types of build triggers:
- trigger build remotely: allows the jenkins webhook to be invoked, meaning you can send HTTP requests to the jenkins webhook to start a build programmatically.
- build periodically: schedule the build via cron job syntax
- poll SCM: do short-polling to constantly check if there's a new commit in the VCS, and if so, then start the build.
- github hook triggering: This is often the preferred approach for many teams. You configure GitHub (or other providers) to send a signal directly to your Jenkins server whenever code is pushed. This requires your Jenkins instance to be reachable via the network to receive the incoming webhook

Poll SCM
Here's an example of configuring Poll SCM to look at a github repo every 5 minutes for changes (it uses cron syntax).

Build environment
The build environment setting controls the build agent configuration when checking out the source code and what to do after. Here are the options you have:
- delete workspace before build starts: agents do not automatically delete checkout out source code or created files during a job. Checking this option will give you a clean slate each time, which is what you want.

Build steps
Here are the different types of build steps you can do:
- shell: run shell commands in this build agent. You have access to all the Jenkins-injected environment variables.
Environment variables
In the shell build step, you have access to all these environment variables that Jenkins injects into the build agent:
- BRANCH_NAME: For a multibranch project, this will be set to the name of the branch being built, for example in case you wish to deploy to production from master but not from feature branches; if corresponding to some kind of change request, the name is generally arbitrary (refer to CHANGE_ID and CHANGE_TARGET).
- BRANCH_IS_PRIMARY: For a multibranch project, if the SCM source reports that the branch being built is a primary branch, this will be set to "true"; else unset. Some SCM sources may report more than one branch as a primary branch while others may not supply this information.
- CHANGE_ID: For a multibranch project corresponding to some kind of change request, this will be set to the change ID, such as a pull request number, if supported; else unset.
- CHANGE_URL: For a multibranch project corresponding to some kind of change request, this will be set to the change URL, if supported; else unset.
- CHANGE_TITLE: For a multibranch project corresponding to some kind of change request, this will be set to the title of the change, if supported; else unset.
- CHANGE_AUTHOR: For a multibranch project corresponding to some kind of change request, this will be set to the username of the author of the proposed change, if supported; else unset.
- CHANGE_AUTHOR_DISPLAY_NAME: For a multibranch project corresponding to some kind of change request, this will be set to the human name of the author, if supported; else unset.
- CHANGE_AUTHOR_EMAIL: For a multibranch project corresponding to some kind of change request, this will be set to the email address of the author, if supported; else unset.
- CHANGE_TARGET: For a multibranch project corresponding to some kind of change request, this will be set to the target or base branch to which the change could be merged, if supported; else unset.
- CHANGE_BRANCH: For a multibranch project corresponding to some kind of change request, this will be set to the name of the actual head on the source control system which may or may not be different from BRANCH_NAME. For example in GitHub or Bitbucket this would have the name of the origin branch whereas BRANCH_NAME would be something like PR-24.
- CHANGE_FORK: For a multibranch project corresponding to some kind of change request, this will be set to the name of the forked repo if the change originates from one; else unset.
- TAG_NAME: For a multibranch project corresponding to some kind of tag, this will be set to the name of the tag being built, if supported; else unset.
- TAG_TIMESTAMP: For a multibranch project corresponding to some kind of tag, this will be set to a timestamp of the tag in milliseconds since Unix epoch, if supported; else unset.
- TAG_UNIXTIME: For a multibranch project corresponding to some kind of tag, this will be set to a timestamp of the tag in seconds since Unix epoch, if supported; else unset.
- TAG_DATE: For a multibranch project corresponding to some kind of tag, this will be set to a timestamp in the format as defined by java.util.Date#toString() (e.g., Wed Jan 1 00:00:00 UTC 2020), if supported; else unset.
- JOB_DISPLAY_URL: URL that will redirect to a Job in a preferred user interface
- RUN_DISPLAY_URL: URL that will redirect to a Build in a preferred user interface
- RUN_ARTIFACTS_DISPLAY_URL: URL that will redirect to Artifacts of a Build in a preferred user interface
- RUN_CHANGES_DISPLAY_URL: URL that will redirect to Changelog of a Build in a preferred user interface
- RUN_TESTS_DISPLAY_URL: URL that will redirect to Test Results of a Build in a preferred user interface
- CI: Statically set to the string "true" to indicate a "continuous integration" execution environment.
- BUILD_NUMBER: The current build number, such as "153".
- BUILD_ID: The current build ID
- BUILD_DISPLAY_NAME: The display name of the current build, which is something like "#153" by default.
- JOB_NAME: Name of the project of this build, such as "foo" or "foo/bar".
- JOB_BASE_NAME: Short Name of the project of this build stripping off folder paths, such as "foo" for "bar/foo".
- BUILD_TAG: String of "
jenkins-${JOB_NAME}-${BUILD_NUMBER}". All forward slashes ("/") in the JOB_NAME are replaced with dashes ("-"). Convenient to put into a resource file, a jar file, etc for easier identification. - EXECUTOR_NUMBER: The unique number that identifies the current executor (among executors of the same machine) that’s carrying out this build. This is the number you see in the "build executor status", except that the number starts from 0, not 1.
- NODE_NAME: Name of the agent if the build is on an agent, or "built-in" if run on the built-in node (or "master" until Jenkins 2.306).
- NODE_LABELS: Whitespace-separated list of labels that the node is assigned.
- WORKSPACE: The absolute path of the directory assigned to the build as a workspace.
- WORKSPACE_TMP: A temporary directory near the workspace that will not be browsable and will not interfere with SCM checkouts. May not initially exist, so be sure to create the directory as needed (e.g., mkdir -p on Linux). Not defined when the regular workspace is a drive root.
- JENKINS_HOME: The absolute path of the directory assigned on the controller file system for Jenkins to store data.
- JENKINS_URL: Full URL of Jenkins, like
http://server:port/jenkins/(note: only available if Jenkins URL set in system configuration). - BUILD_URL: Full URL of this build, like
http://server:port/jenkins/job/foo/15/(Jenkins URL must be set). - JOB_URL: Full URL of this job, like
http://server:port/jenkins/job/foo/(Jenkins URL must be set). - GIT_COMMIT: The commit hash being checked out.
- GIT_PREVIOUS_COMMIT: The hash of the commit last built on this branch, if any.
- GIT_PREVIOUS_SUCCESSFUL_COMMIT: The hash of the commit last successfully built on this branch, if any.
- GIT_BRANCH: The remote branch name, if any.
- GIT_LOCAL_BRANCH: The local branch name being checked out, if applicable.
- GIT_CHECKOUT_DIR: The directory that the repository will be checked out to. This contains the value set in Checkout to a sub-directory, if used.
- GIT_URL: The remote URL. If there are multiple, will be GIT_URL_1, GIT_URL_2, etc.
- GIT_COMMITTER_NAME: The configured Git committer name, if any, that will be used for FUTURE commits from the current workspace. It is read from the Global Config user.name Value field of the Jenkins Configure System page.
- GIT_AUTHOR_NAME: The configured Git author name, if any, that will be used for FUTURE commits from the current workspace. It is read from the Global Config user.name Value field of the Jenkins Configure System page.
- GIT_COMMITTER_EMAIL: The configured Git committer email, if any, that will be used for FUTURE commits from the current workspace. It is read from the Global Config user.email Value field of the Jenkins Configure System page.
- GIT_AUTHOR_EMAIL: The configured Git author email, if any, that will be used for FUTURE commits from the current workspace. It is read from the Global Config user.email Value field of the Jenkins Configure System page.
Build agents
Jenkins needs build agents in order to actually run your build.
NOTE
if running Jenkins locally, by default the container or K8S pod running jenkins acts as both the master server and a build agent with all tools already installed.
TIP
It's always recommended to offload the actual build work to a separate build agent rather than having the master server be both the orchestrator and minion.
There are two types of build agents you can create.
- cloud: you can configure EC2 instances, docker containers, and K8S pods as build agents
- node: a machine you own, like your own laptop or an EC2 instance.
Docker cloud
To add Docker containers as a build agent option, you add them as a docker cloud option, and a docker cloud has many build agent templates to choose from for creating the build agent environment.
A build agent template has these important components:
- label: used to uniquely identify a build agent template to use for a build.
- image configuration: settings for choosing the base image of the build agent template, along with container configuration.
One Docker cloud has many build agent templates.
Creating a docker cloud
To do this, we'll first create a new docker cloud:


When prompted for the docker host URI, you need to create a new container that will proxy the connection between jenkins and other containers. Follow these steps:
- Run this command to create an alpine linux container that port forwards the Docker process to another port, basically forking it.
# create container that proxies Docker TCP process
$CONTAINER_ID = $(docker run -d --restart=always -p 127.0.0.1:2377:2375 --network jenkins -v /var/run/docker.sock:/var/run/docker.sock alpine/socat tcp-listen:2375,fork,reuseaddr unix-connect:/var/run/docker.sock)

# get the IP address of that container
docker inspect $CONTAINER_ID | grep IPAddress
- Now add the TCP process for that IP as the docker host URI as per the syntax below, and then test the connection.
tcp://<container-ip>:2375

Creating a build template
Now we can move on to actually configuring the build template for container build agents that will be created.
Here are the important fields you need to consider and fill out:
- labels: labels are used for the master to determine which agent should run the current build (sort of like agent requirements in teamcity).
- image: the base image to pull down to create the build agent from.
- instance capacity: the max number of container build agents that can be running simultaneously.
- remote file system root: This is the root directory within your image for the Jenkins user to use. Think of this as the workspace directory within the build agent environment that will contain all jobs/builds created.
- The default should be
/home/jenkins
- The default should be
Here are the steps:
- Fill out label, name, and image:

- Fill out the instance settings:
- remote file system root: set this to
/home/jenkins
- remote file system root: set this to
Now once the docker build agent template has been created, you can now use it within your builds to specify that a build should run on a docker build agent using that build agent template:
Go to the configuration settings of a job and check the restrict where this build can run option, then select the label of the docker build agent template you created.

What this option does is restrict the build to only run on build agents with that specific label.
Creating a custom build agent image
- Create a dockerfile that builds off an existing jenkins build agent base image:
FROM jenkins/agent:alpine-jdk21
USER root
RUN apk add python3
RUN apk add py3-pip
RUN apk add nodejs
RUN apk add npm
USER jenkins
- Build an image from this dockerfile and upload it to a public registry.
- Use the created image as the base image for a docker build agent template.
Declarative pipelines
Declarative pipelines are config-as-code for defining a job declaratively using a Jenkinsfile in the root of a repo.
Jenkinsfile
Here is a basic jenkinsfile:
agent: the agent block defines which agent should run the job, via the label of the agent build templatestages: the stages block defines individual stages of a build which run in sequential ordertriggers: defines the build trigger
pipeline {
    agent {
        node {
            label 'docker-agent-python'
            }
      }
    triggers {
        pollSCM '* * * * *'
    }
    stages {
        stage('Build') {
            steps {
                echo "Building.."
                sh '''
                cd myapp
                pip install -r requirements.txt
                '''
            }
        }
        stage('Test') {
            steps {
                echo "Testing.."
                sh '''
                cd myapp
                python3 hello.py
                python3 hello.py --name=Brad
                '''
            }
        }
        stage('Deliver') {
            steps {
                echo 'Deliver....'
                sh '''
                echo "doing delivery stuff.."
                '''
            }
        }
    }
}
Jenkins examples
SSH agent pipeline
- Create an Ubuntu dockerfile that uses ssh agent to allow users to ssh into that container.
# Use the official Ubuntu image as a base
FROM ubuntu:latest

# Install necessary packages and Docker
RUN apt-get update && apt-get install -y \
    sudo \
    curl \
    gnupg \
    lsb-release \
    && curl -fsSL https://get.docker.com -o get-docker.sh \
    && sh get-docker.sh \
    && rm get-docker.sh \
    && usermod -aG docker root \
    && apt-get clean

# Install OpenSSH Server
RUN apt-get install -y openssh-server \
    && mkdir /var/run/sshd \
    && echo 'root:password' | chpasswd

# Create a new SSH configuration file
RUN echo 'PermitRootLogin yes' > /etc/ssh/sshd_config.d/custom.conf \
    && echo 'PasswordAuthentication yes' >> /etc/ssh/sshd_config.d/custom.conf

# Start SSH service
CMD ["/usr/sbin/sshd", "-D"]
- Create a docker compose that does the following:
- jenkins image: creates a jenkins image that runs on port 8080
- ubuntu image: create an ubuntu image that allows SSHing on it through port 2222
- volume and network connection: create a bridge network to let the jenkins container and ubuntu container communicate with each other, as well as share the same volumes between those two containers, which contains jenkins configuration and workspace data and docker engine connectivity files.
version: "3.8"

services:
  jenkins:
    image: jenkins/jenkins:lts
    container_name: jenkins-container
    ports:
      - "8080:8080"
    networks:
      - jenkins-demo-network
    volumes:
      - jenkins_home:/var/jenkins_home
      - /var/run/docker.sock:/var/run/docker.sock
      - /usr/bin/docker:/usr/bin/docker

  ubuntu:
    build:
      context: .
      dockerfile: Dockerfile
    container_name: ubuntu-ssh-container
    volumes:
      - jenkins_home:/var/jenkins_home
      - /var/run/docker.sock:/var/run/docker.sock
      - /usr/bin/docker:/usr/bin/docker
    networks:
      - jenkins-demo-network
    ports:
      - "2222:22"
      - "8086:8084"

networks:
  jenkins-demo-network:
    driver: bridge

volumes:
  jenkins_home:
- Create a react app that is hosted via Nginx on port 80, using this dockerfile
# Use the official Nginx image
FROM nginx:alpine

# Set the working directory
WORKDIR /usr/share/nginx/html

# Remove the default Nginx static files
RUN rm -rf ./*

# Copy the React build output to the Nginx web directory
COPY ./build /usr/share/nginx/html

# Expose port 80
EXPOSE 80

# Start Nginx
CMD ["nginx", "-g", "daemon off;"]
- Run
docker compose upto start the ubuntu and jenkins containers
Now the next step is to add ssh agent connectivity via credentials and plugins:
- Create a new SSH public-private key pair with the
ssh-keygencommand:
ssh-keygen
- Copy over the generated public key to the running Ubuntu container via SSH
ssh-copy-id -i jenkins-demo.pub root@localhost -p 2222
- Create a new credential of type SSH with private key


- Manually paste in the private key contents to create the credentials
The next step is to enable NodeJS and Docker tools in Jenkins, which are found in the tools tab. For all of them, you should set up automatic installers, so it installs the languages like JDK and Node on the build agents.
- Enable the docker tool, let it install automatically

- Enable the NodeJS tool, let it install automatically

Now you can create a jenkinsfile:
pipeline {
	// 1. define agent to run the build
    agent any

	// 2. define env vars and credentials
    environment {
        DOCKER_IMAGE = "whether-app"
        DOCKER_REGISTRY = "ghcr.io/dispatch-yt"
        GIT_CREDENTIALS_ID = "GIT_CREDENTIALS_ID"
        SSH_CREDENTIALS_ID = "key"
        SERVER_IP = "192.168.80.2"
        SERVER_USER = "root"
    }

    // 3. register nodejs and docker tools as possible steps
    tools {
        nodejs "nodejs"
        dockerTool "docker-website"
    }

    stages {
	    // 4. run the git step to clone a repo down
        stage('Clone Repository') {
            steps {
                git credentialsId: "${GIT_CREDENTIALS_ID}", url: 'https://github.com/dispatch-yt/react-whether-appp'
            }
        }

		// 5. run the sh steps to run bash commands
        stage('Build React Project') {
            steps {
                sh 'npm install'
                sh 'npm run build'
            }
        }

		// 6. use docker installation on build agent (current jenkins server instance)
        stage('Create Docker Image') {
            steps {
                script {
                    sh 'ls'
                    sh 'cat src/pages/Home.jsx'
                    sh 'docker build -t ${DOCKER_IMAGE}:latest -f Dockerfile .'
                }
            }
        }

        stage('Push Docker Image to GitHub Registry') {
            steps {
                script {
                    docker.withRegistry('https://ghcr.io', 'GIT_CREDENTIALS_ID') {
                        sh 'docker tag ${DOCKER_IMAGE}:latest ${DOCKER_REGISTRY}/${DOCKER_IMAGE}:latest'
                        sh 'docker push ${DOCKER_REGISTRY}/${DOCKER_IMAGE}:latest'
                    }
                }
            }
        }
        stage('SSH to Server and Deploy') {
            steps {
                script {
                    sshagent([SSH_CREDENTIALS_ID]) {
                        sh """
                        ssh -o StrictHostKeyChecking=no ${SERVER_USER}@${SERVER_IP} << EOF
                            docker stop ${DOCKER_IMAGE} || true
                            docker rm ${DOCKER_IMAGE} || true
                            docker rmi ${DOCKER_IMAGE} || true
                            docker rmi ${DOCKER_REGISTRY}/${DOCKER_IMAGE}:latest || true
                            docker pull ${DOCKER_REGISTRY}/${DOCKER_IMAGE}:latest
                            docker run -d --name ${DOCKER_IMAGE} -p 8084:80 ${DOCKER_REGISTRY}/${DOCKER_IMAGE}:latest
                        """
                    }
                }
            }
        }
    }

    post {
        always {
            cleanWs()
        }
    }
}
Source control tools
Subversion
Subversion (SVN) is a centralized version control system, which means it uses a central repository where all code changes are stored, where developers sync their code with this central location to manage versions.
NOTE
It's an open-source project by the Apache Software Foundation, designed to be safe, simple, and reliable, suitable for projects from small to large corporate operations.
On Windows, you can use SVN through command line or graphical tools like TortoiseSVN, which integrates into the system for easier use.
Subversion (SVN) and Git are both version control systems but differ mainly in architecture and workflow:
- Subversion (SVN) is a centralized system where all code changes are synced to a central repository. This means you always work with a single source of truth stored on a server.
- Git is a distributed system, so every developer has a full copy of the entire repository history locally, allowing for more flexible workflows and offline work.
Subversion repositories
Since subversion repos are centralized, that means that they are a single source of truth, and the only way to make changes is to checkout a branch and then push it up to change the centralized version.
To let other developers access the repo, you should put the centralized repo on a virtual machine every developer can SSH into.
In short, here are the different components:
- centralized repo: the centralized source of truth for the source code that nobody can change directly.
- checked out repo: a local repo branching off of the centralized repo to let you add local changes and push them up.
In a repo, you have three important subfolders which basically control the VCS system for your repo:
branches: subfolder that contains all branchestags:trunk: where all source code goes and all TortoiseSVN operations are supposed to be performed on.
TortoiseSVN
TortoiseSVN is a tool to create subversion repositories and kickstart the dev process.
- Install tortoise SVN
winget install -e --id TortoiseSVN.TortoiseSVN
- On a folder, create a new repository using tortoise SVN

- Click on Create folder structure

- Create a new folder to checkout the centralized repo by clicking on the SVN checkout folder option.

- Finish checkout, which will then create a
branch,tags, andtrunksubfolder within the local checked out repo.

Tortoize SVN workflow
This is how the commit process works:
- Add a file to the repository

- Click on the SVN Commit option to commit a file

- Commit the file or files

View logs

Reverting changes
- Click on TortoiseSVN -> Update to revision

- Click on show log to view the list of the commits and choose which commit you want to revert to.

- To see which commit to use, go to a certain commit, right click, and then select compare with working copy to view the diff between that commit and the current state of the repo.

- Complete the revision
Branches
- Right click on the
trunkfolder, select TortoiseSVN, then click on Branch/tag to create a new branch or tag.

- The name of the branch is the same as the name of the subfolder you will create within the
branchesfolder

- To switch to a branch, right click on the
trunkfolder, select TortoiseSVN, then click on switch to create a new branch or tag.

- Select the branch you want to switch to, make sure to select the fully recursive option.

- When you add and commit a file, it will now be added to the branch folder:

Merging branches
To merge branches, you need to switch back to the trunk branch and then merge a specific branch into the trunk branch.
- Switch to the trunk branch


- To merge a branch into
trunk, right click on thetrunkfolder, select TortoiseSVN, then click on merge:

- Select the merge two different trees option

- I know it sounds counterintuitive but the "From" branch should be trunk and the "To" branch should be the branch you want to merge into trunk (because the idea is that we're moving trunk from an old commit to the new commit on branch).

TortoiseGit
TortoiseGit is a windows tool to make using git easier with windows and available in the file explorer by allowing you to open a folder as a repository.
